Studios working on unreleased shows often cannot send scene files or pipeline code to cloud AI tools. Client security terms rule it out. That leaves Houdini, the most technical tool in the pipeline, without the kind of assistance the rest of software now takes for granted.
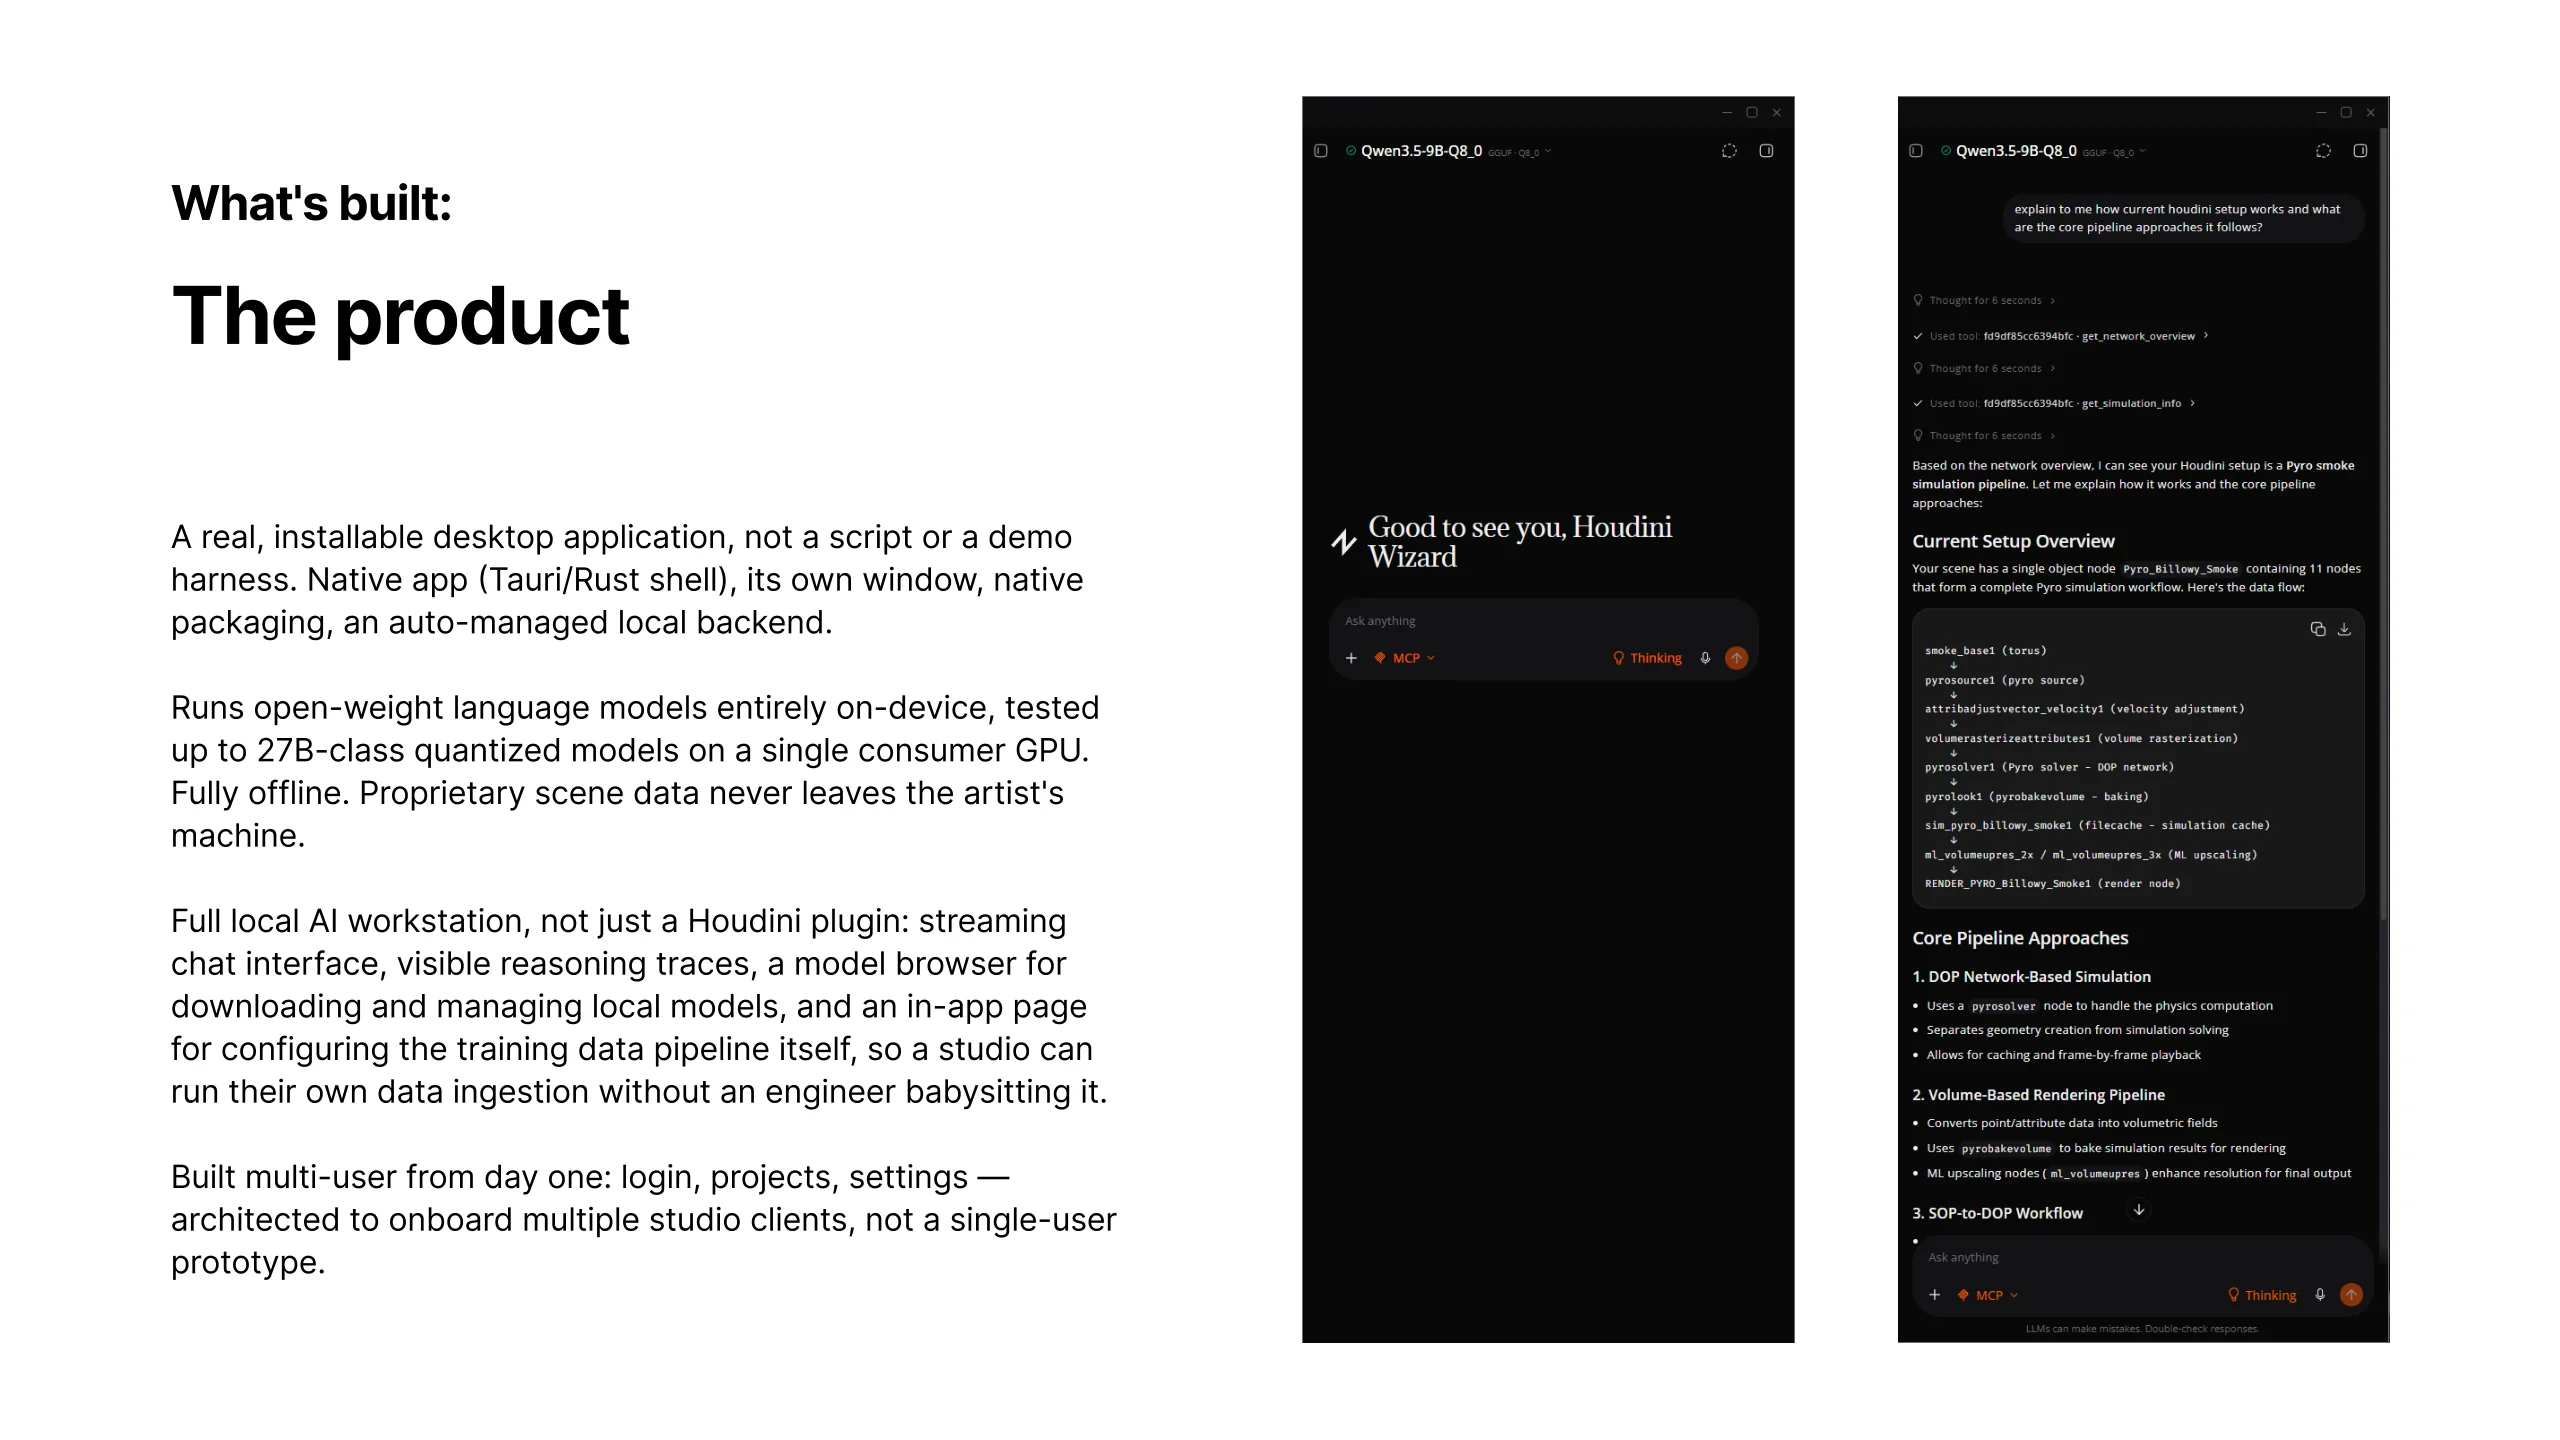
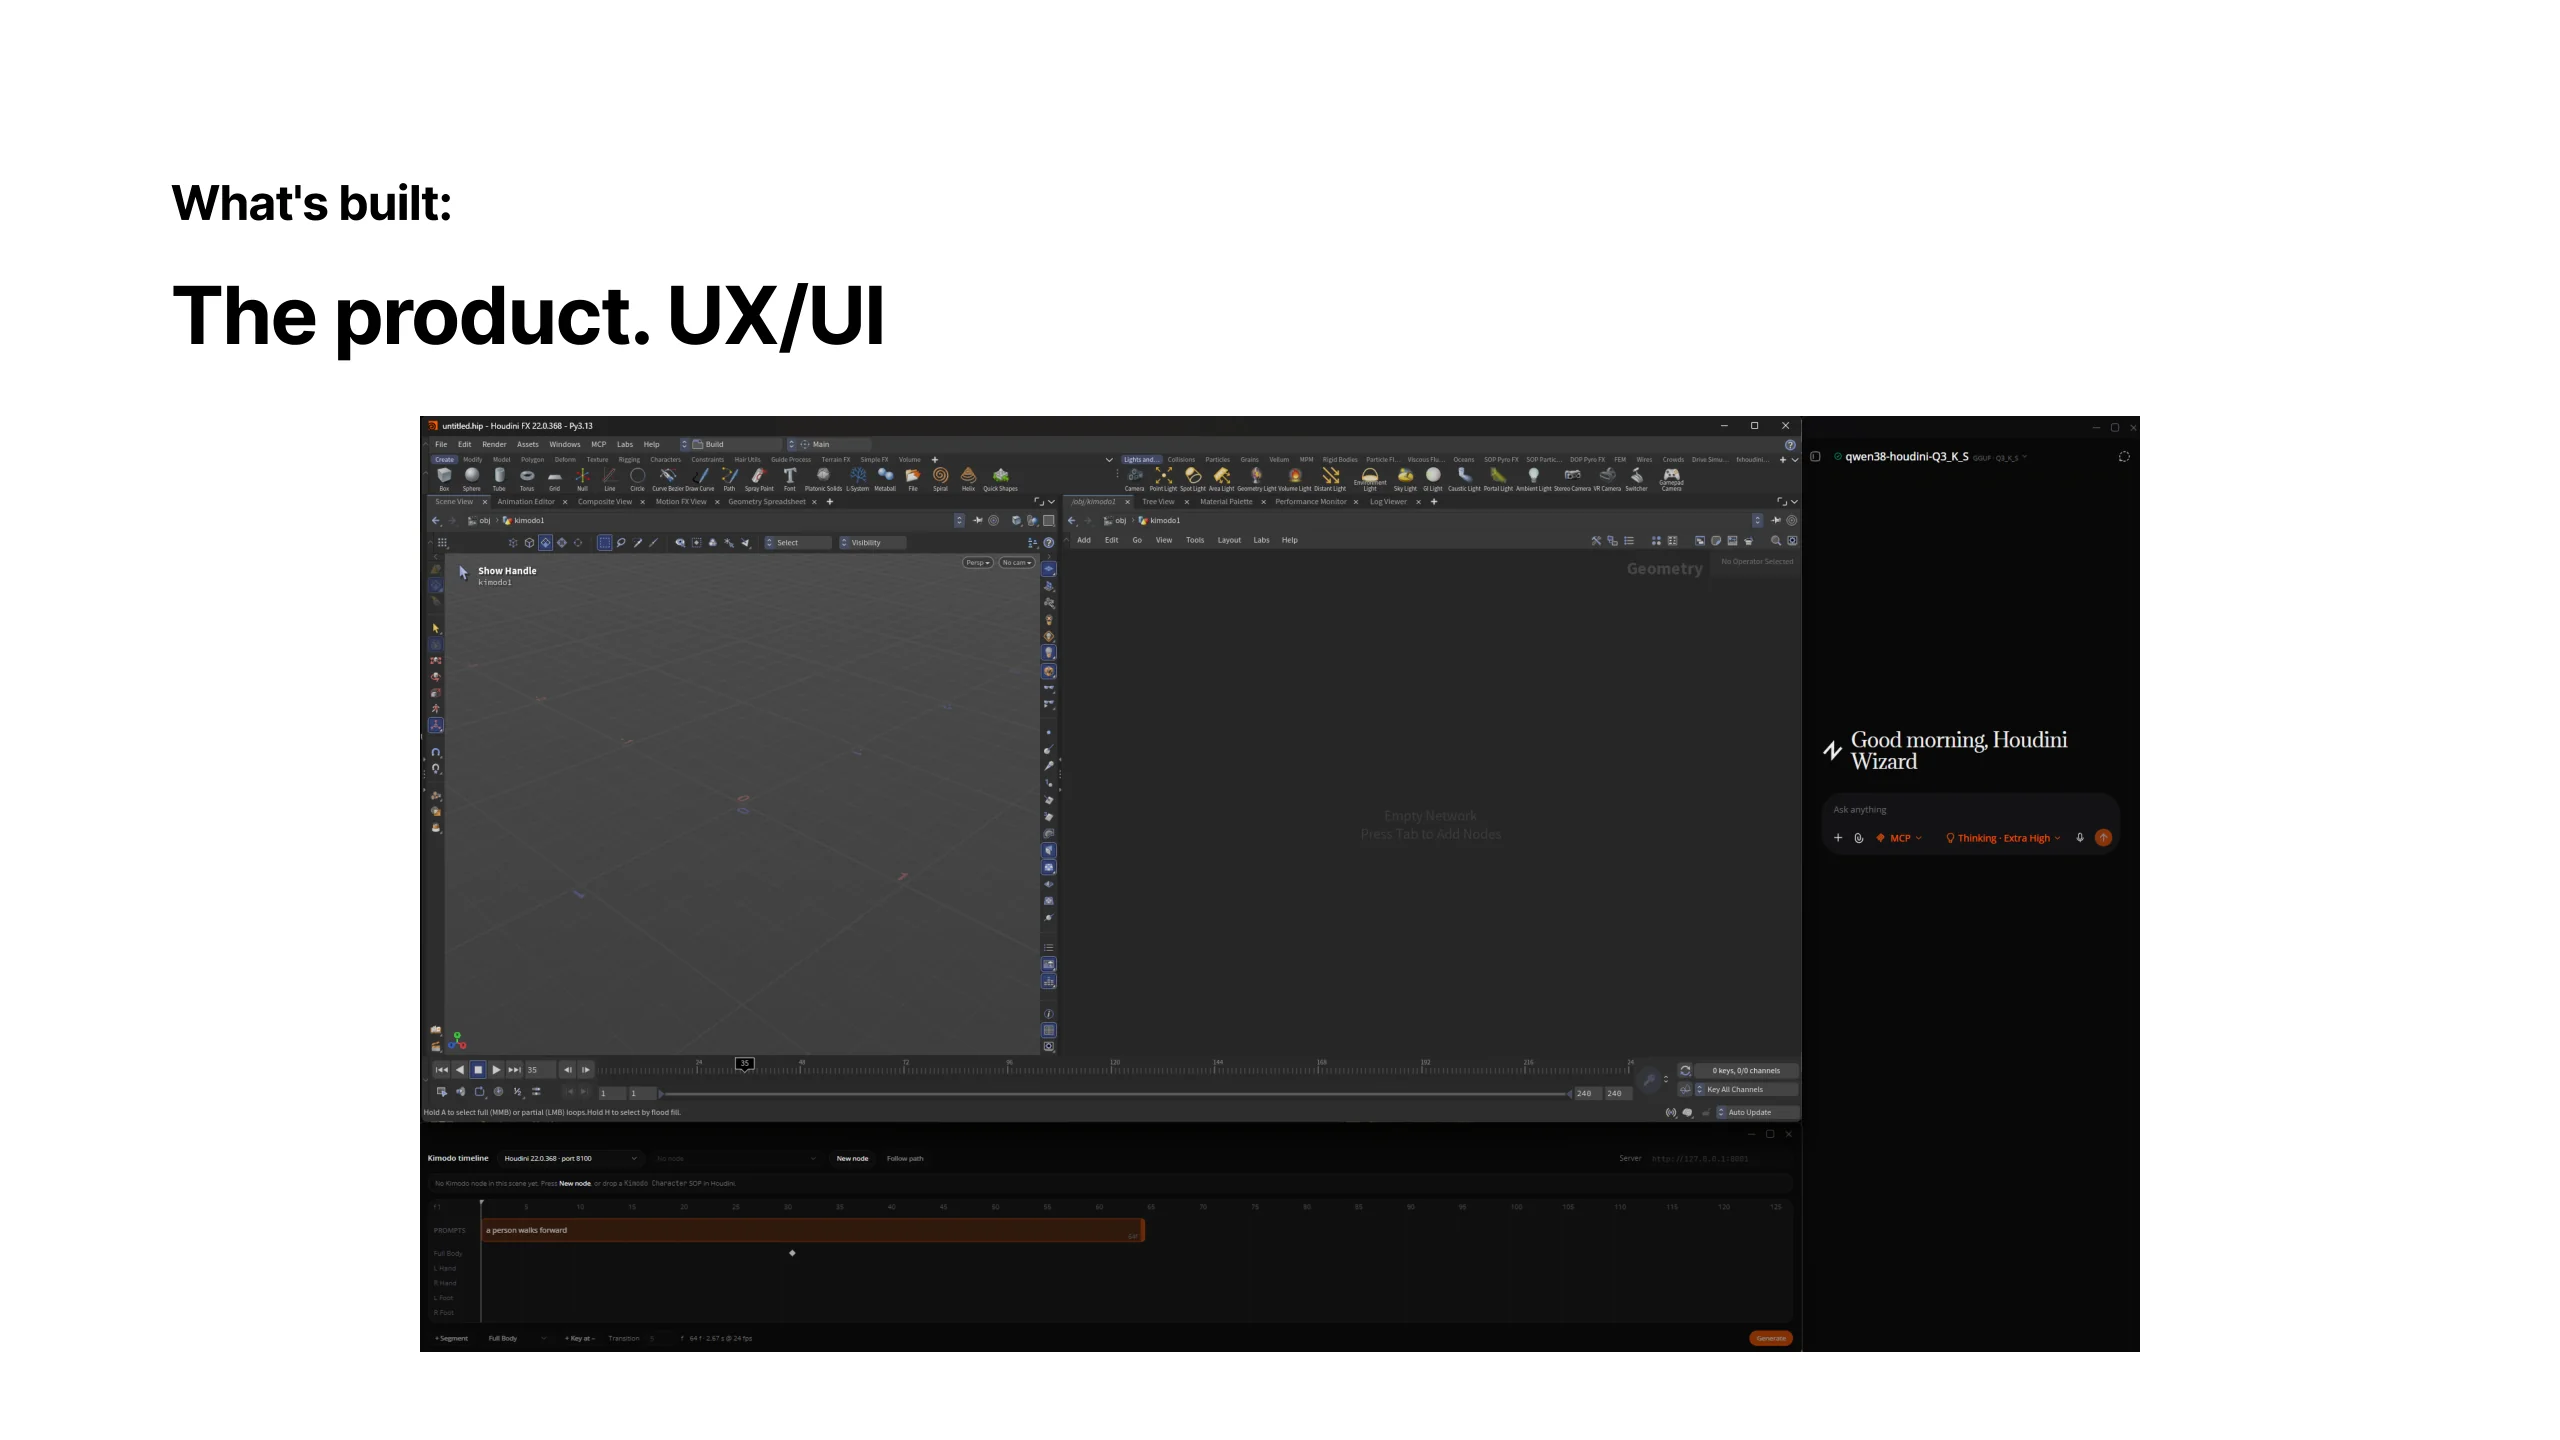
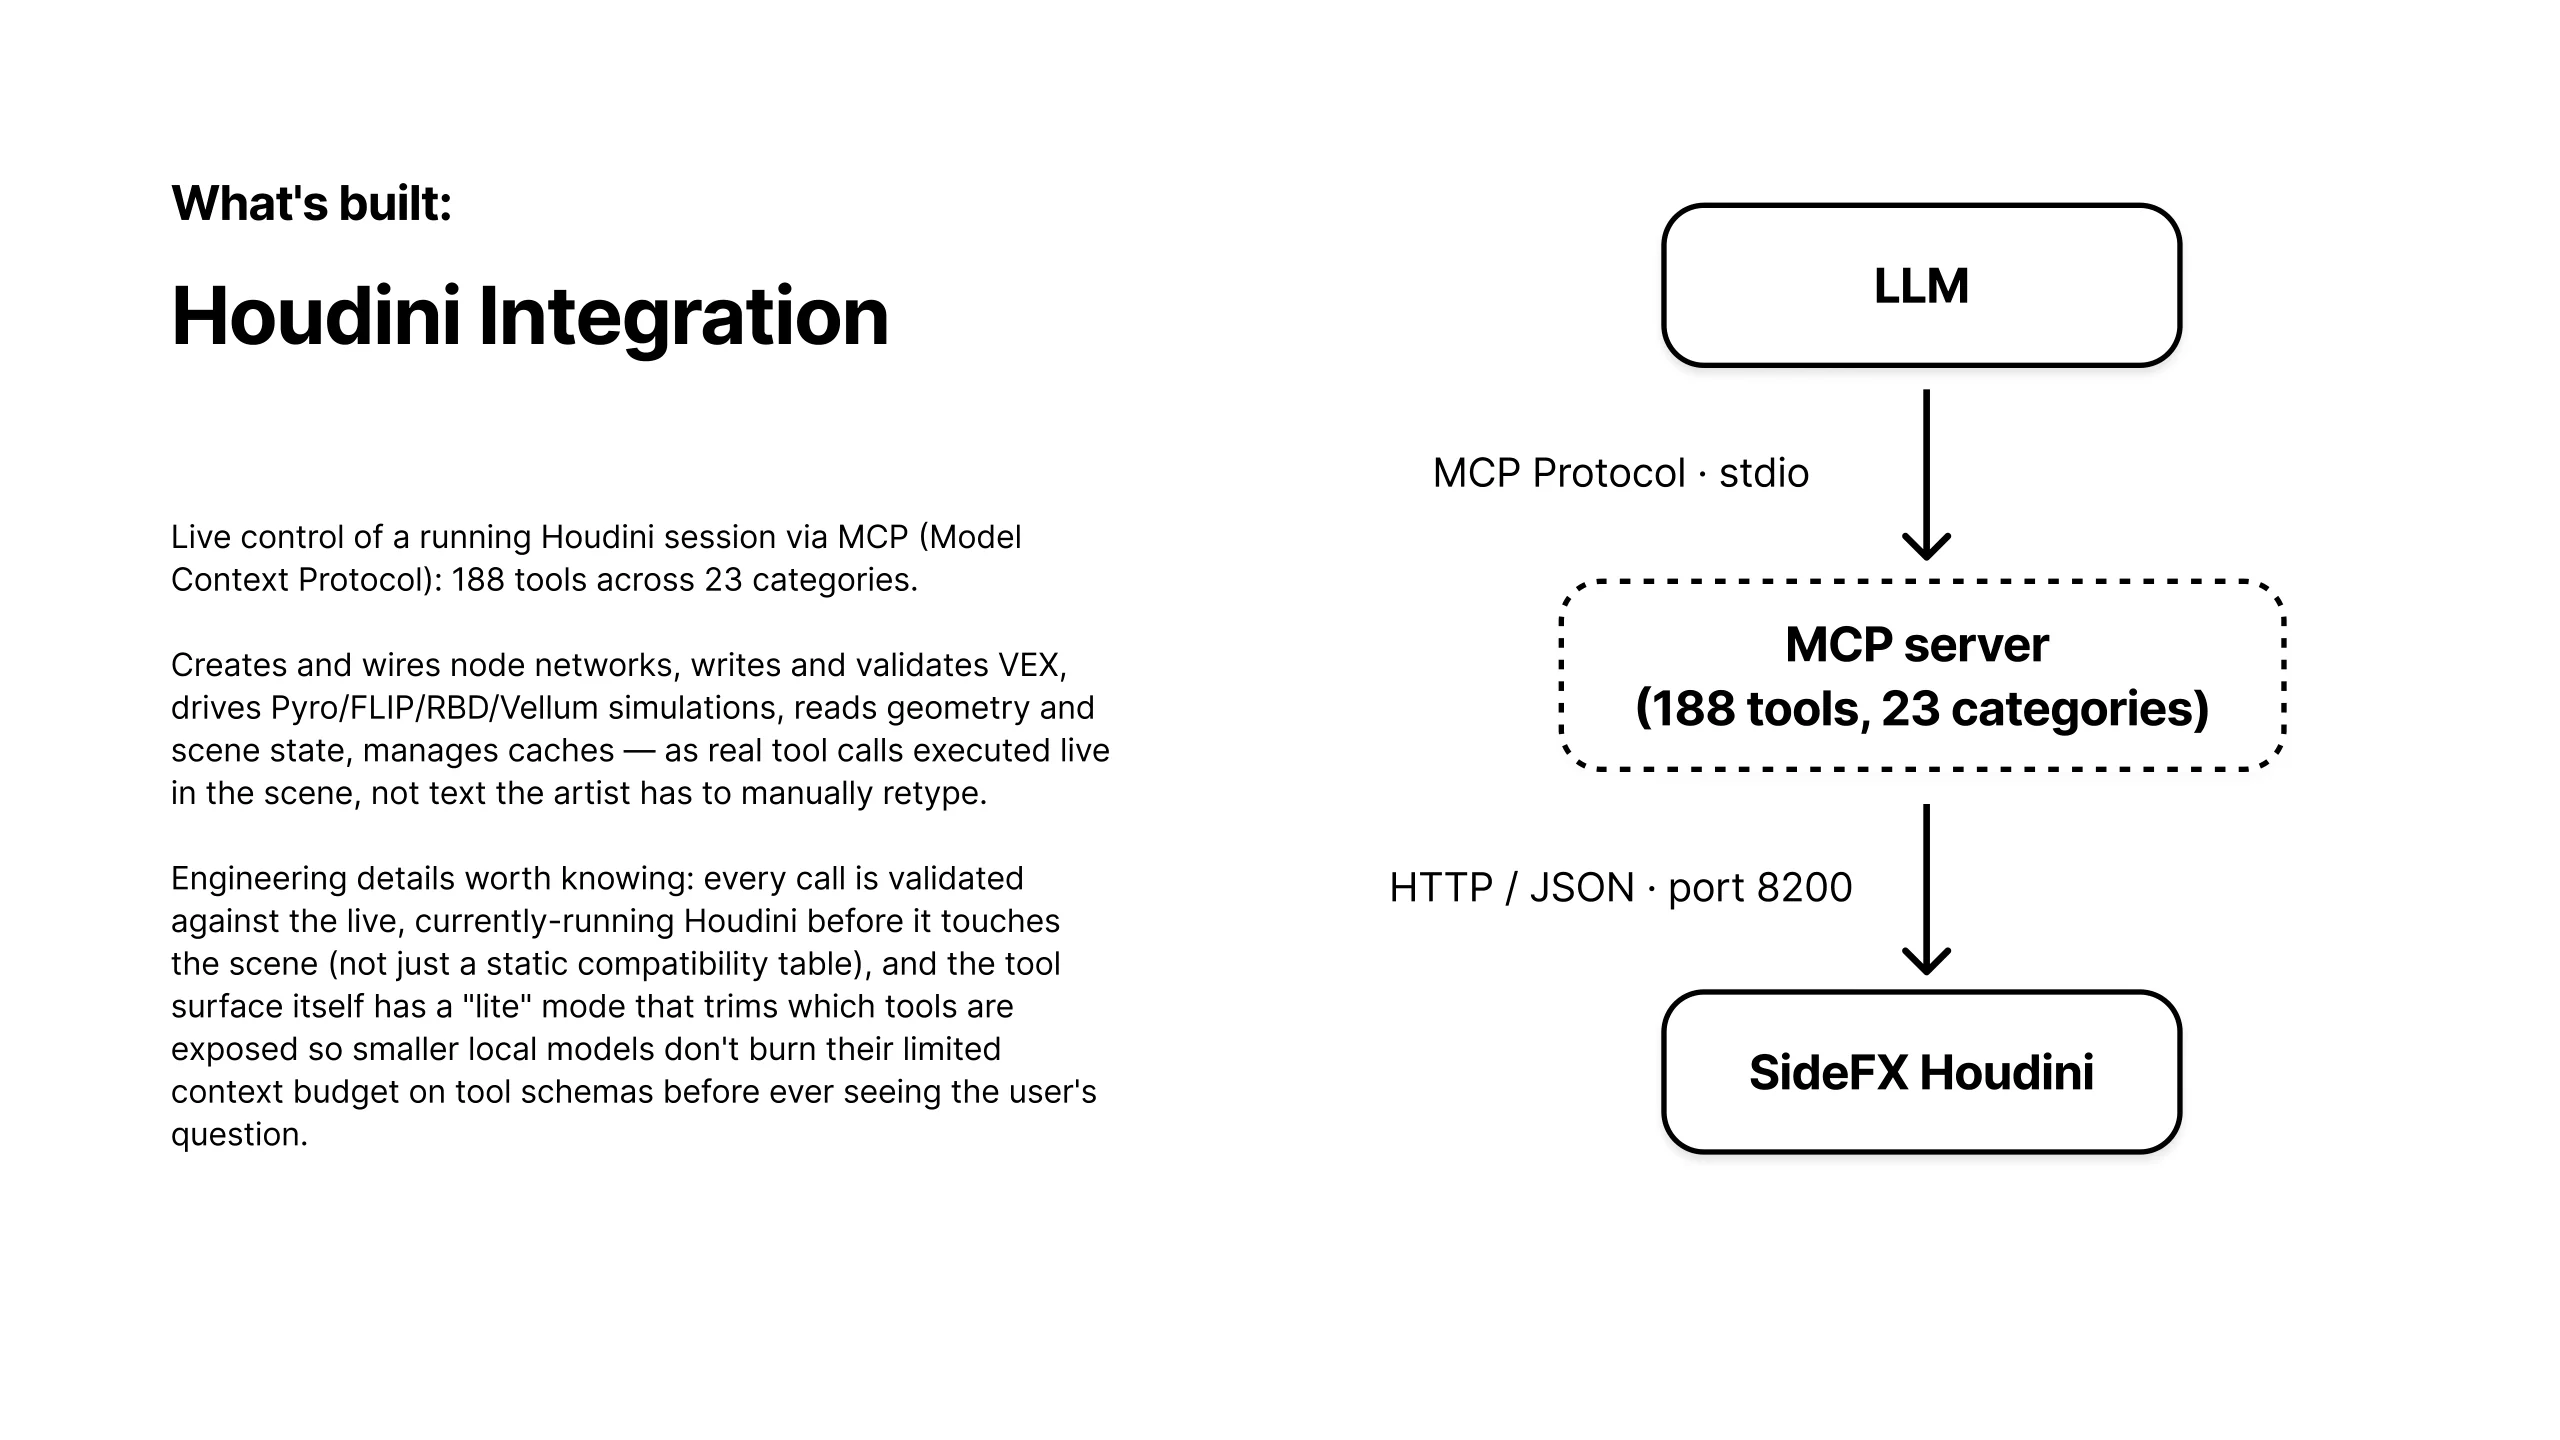
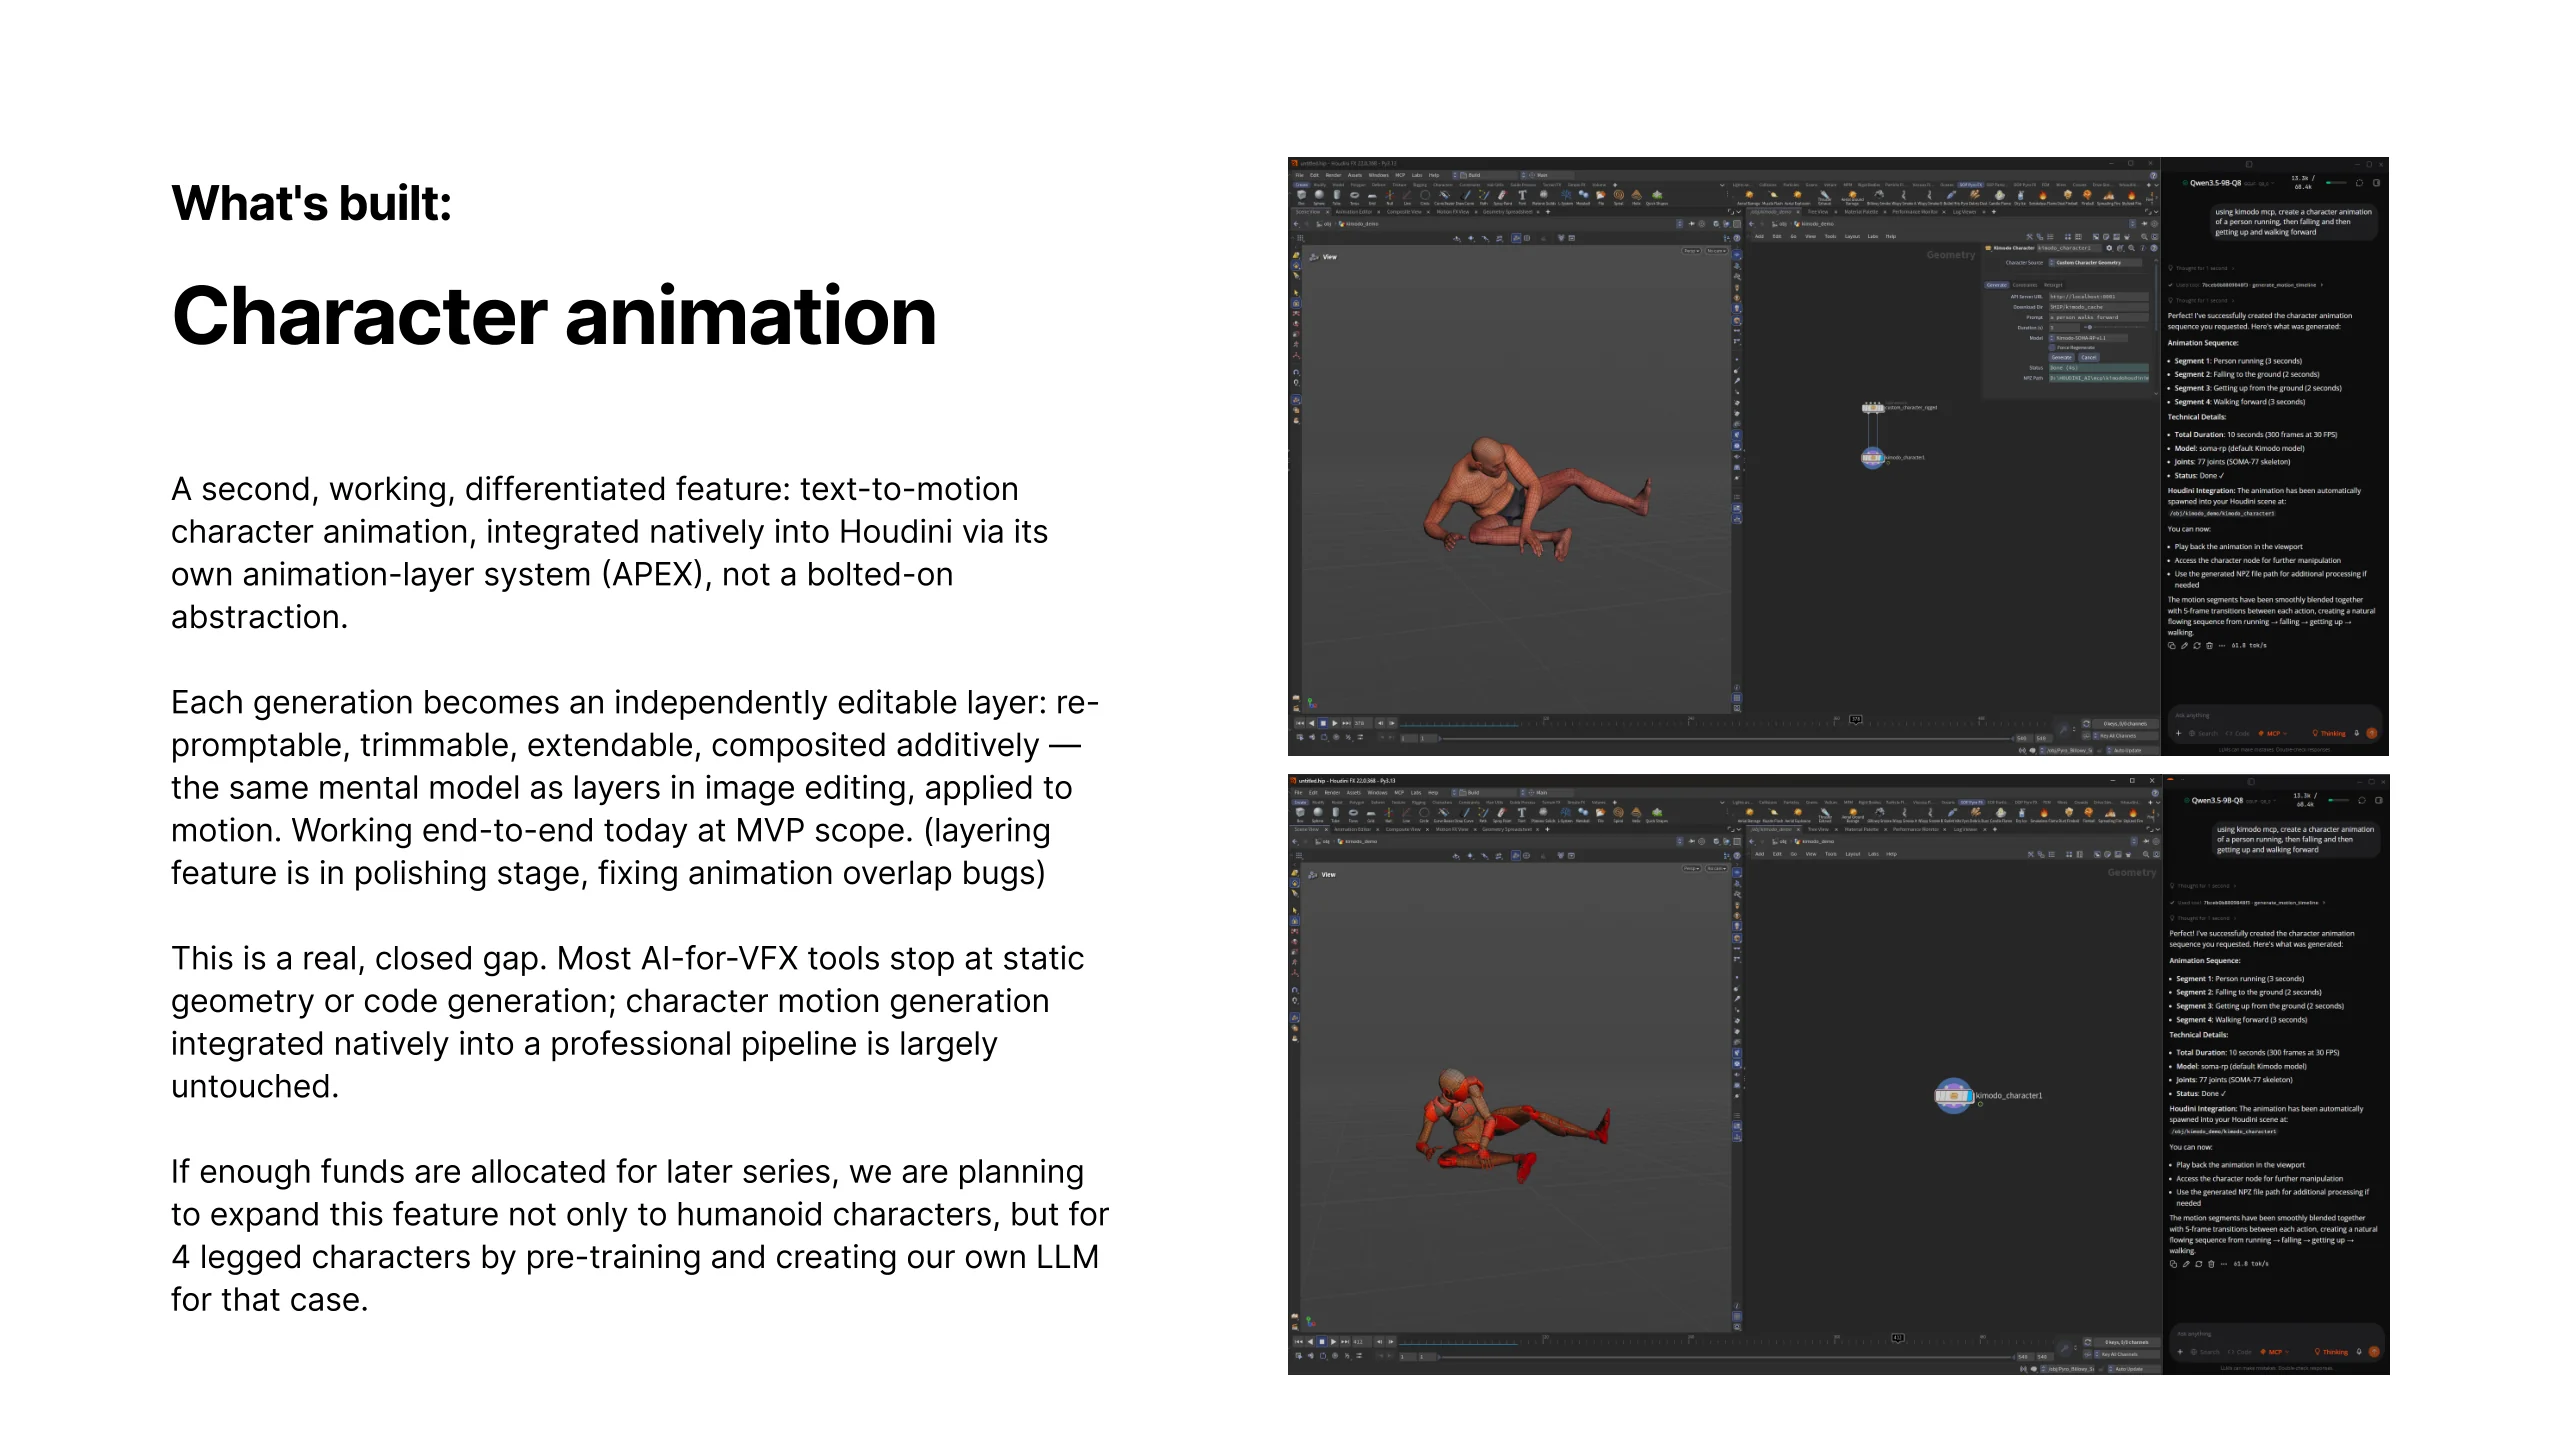
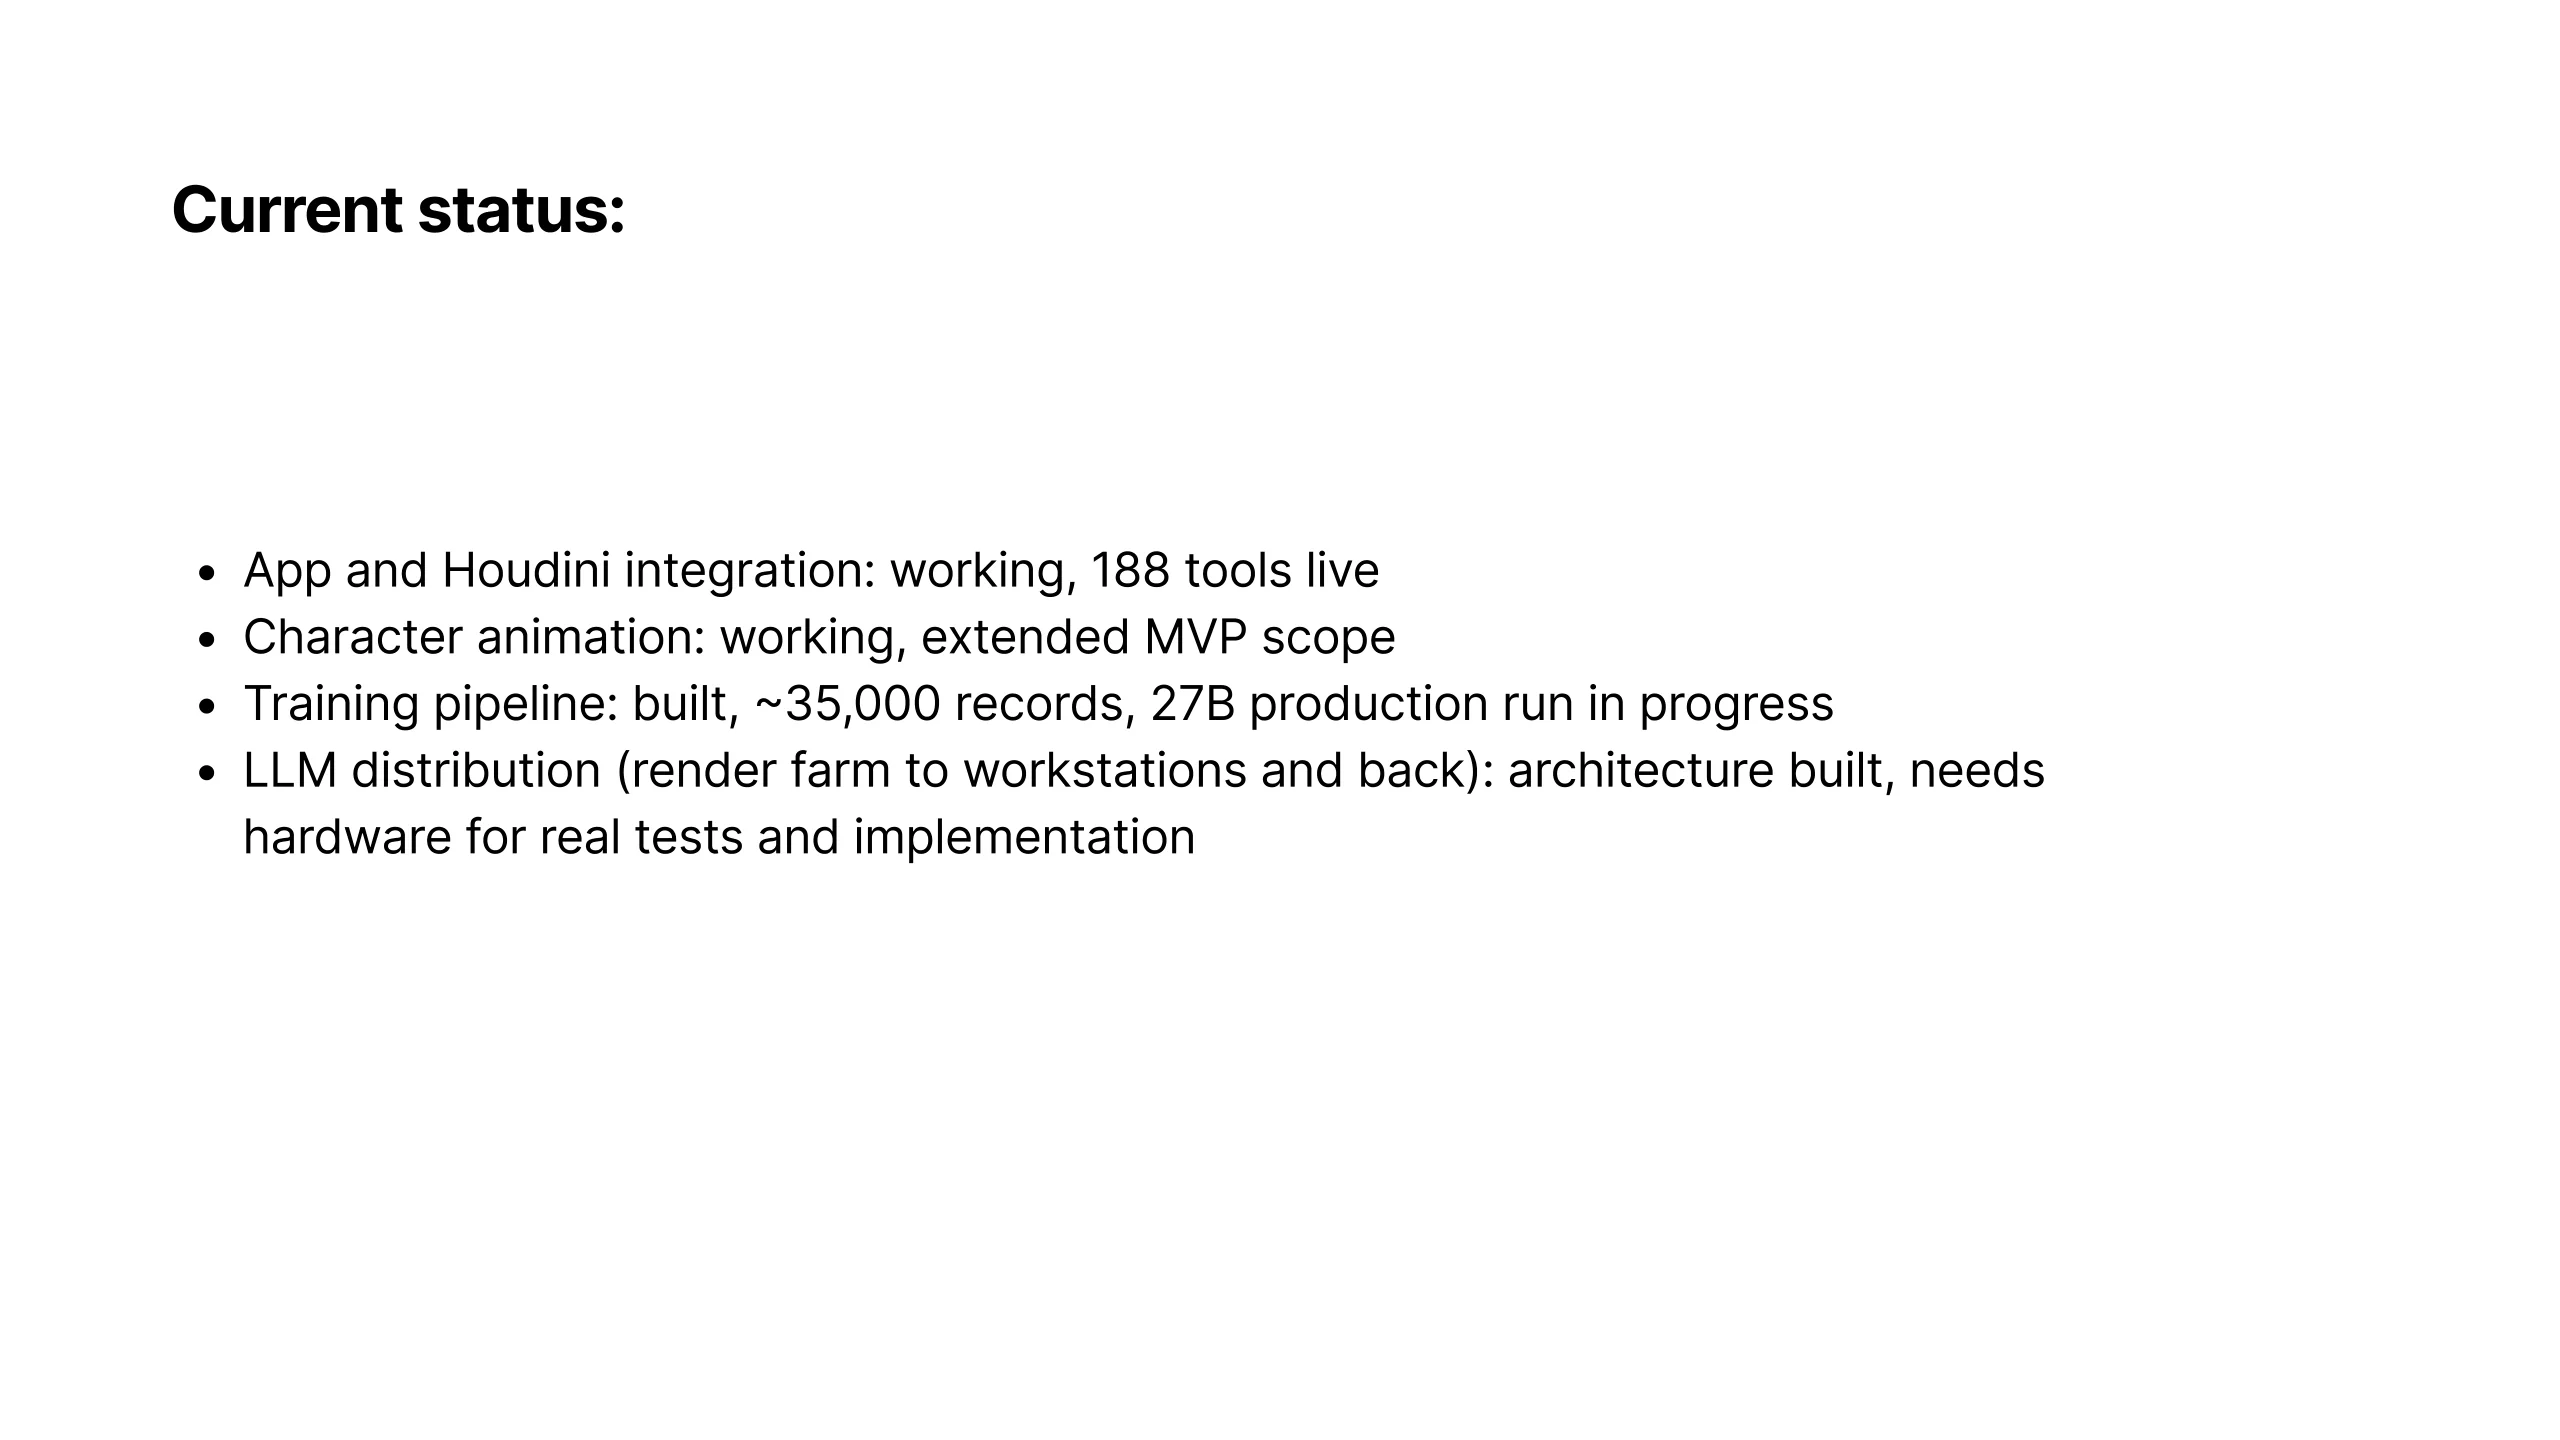
I founded this project to close that gap: an AI agent that operates a live Houdini session instead of chatting next to it, and runs entirely on the studio’s own hardware. It is a native desktop app (Tauri/Rust) with a local model backend, connected to Houdini through the Model Context Protocol (MCP), a standard way for AI models to call real tools. It has 188 of them across 23 categories. It builds and repairs node networks, writes VEX and checks it against the running session, drives Pyro, FLIP, RBD and Vellum setups, and generates character motion as editable APEX animation layers.
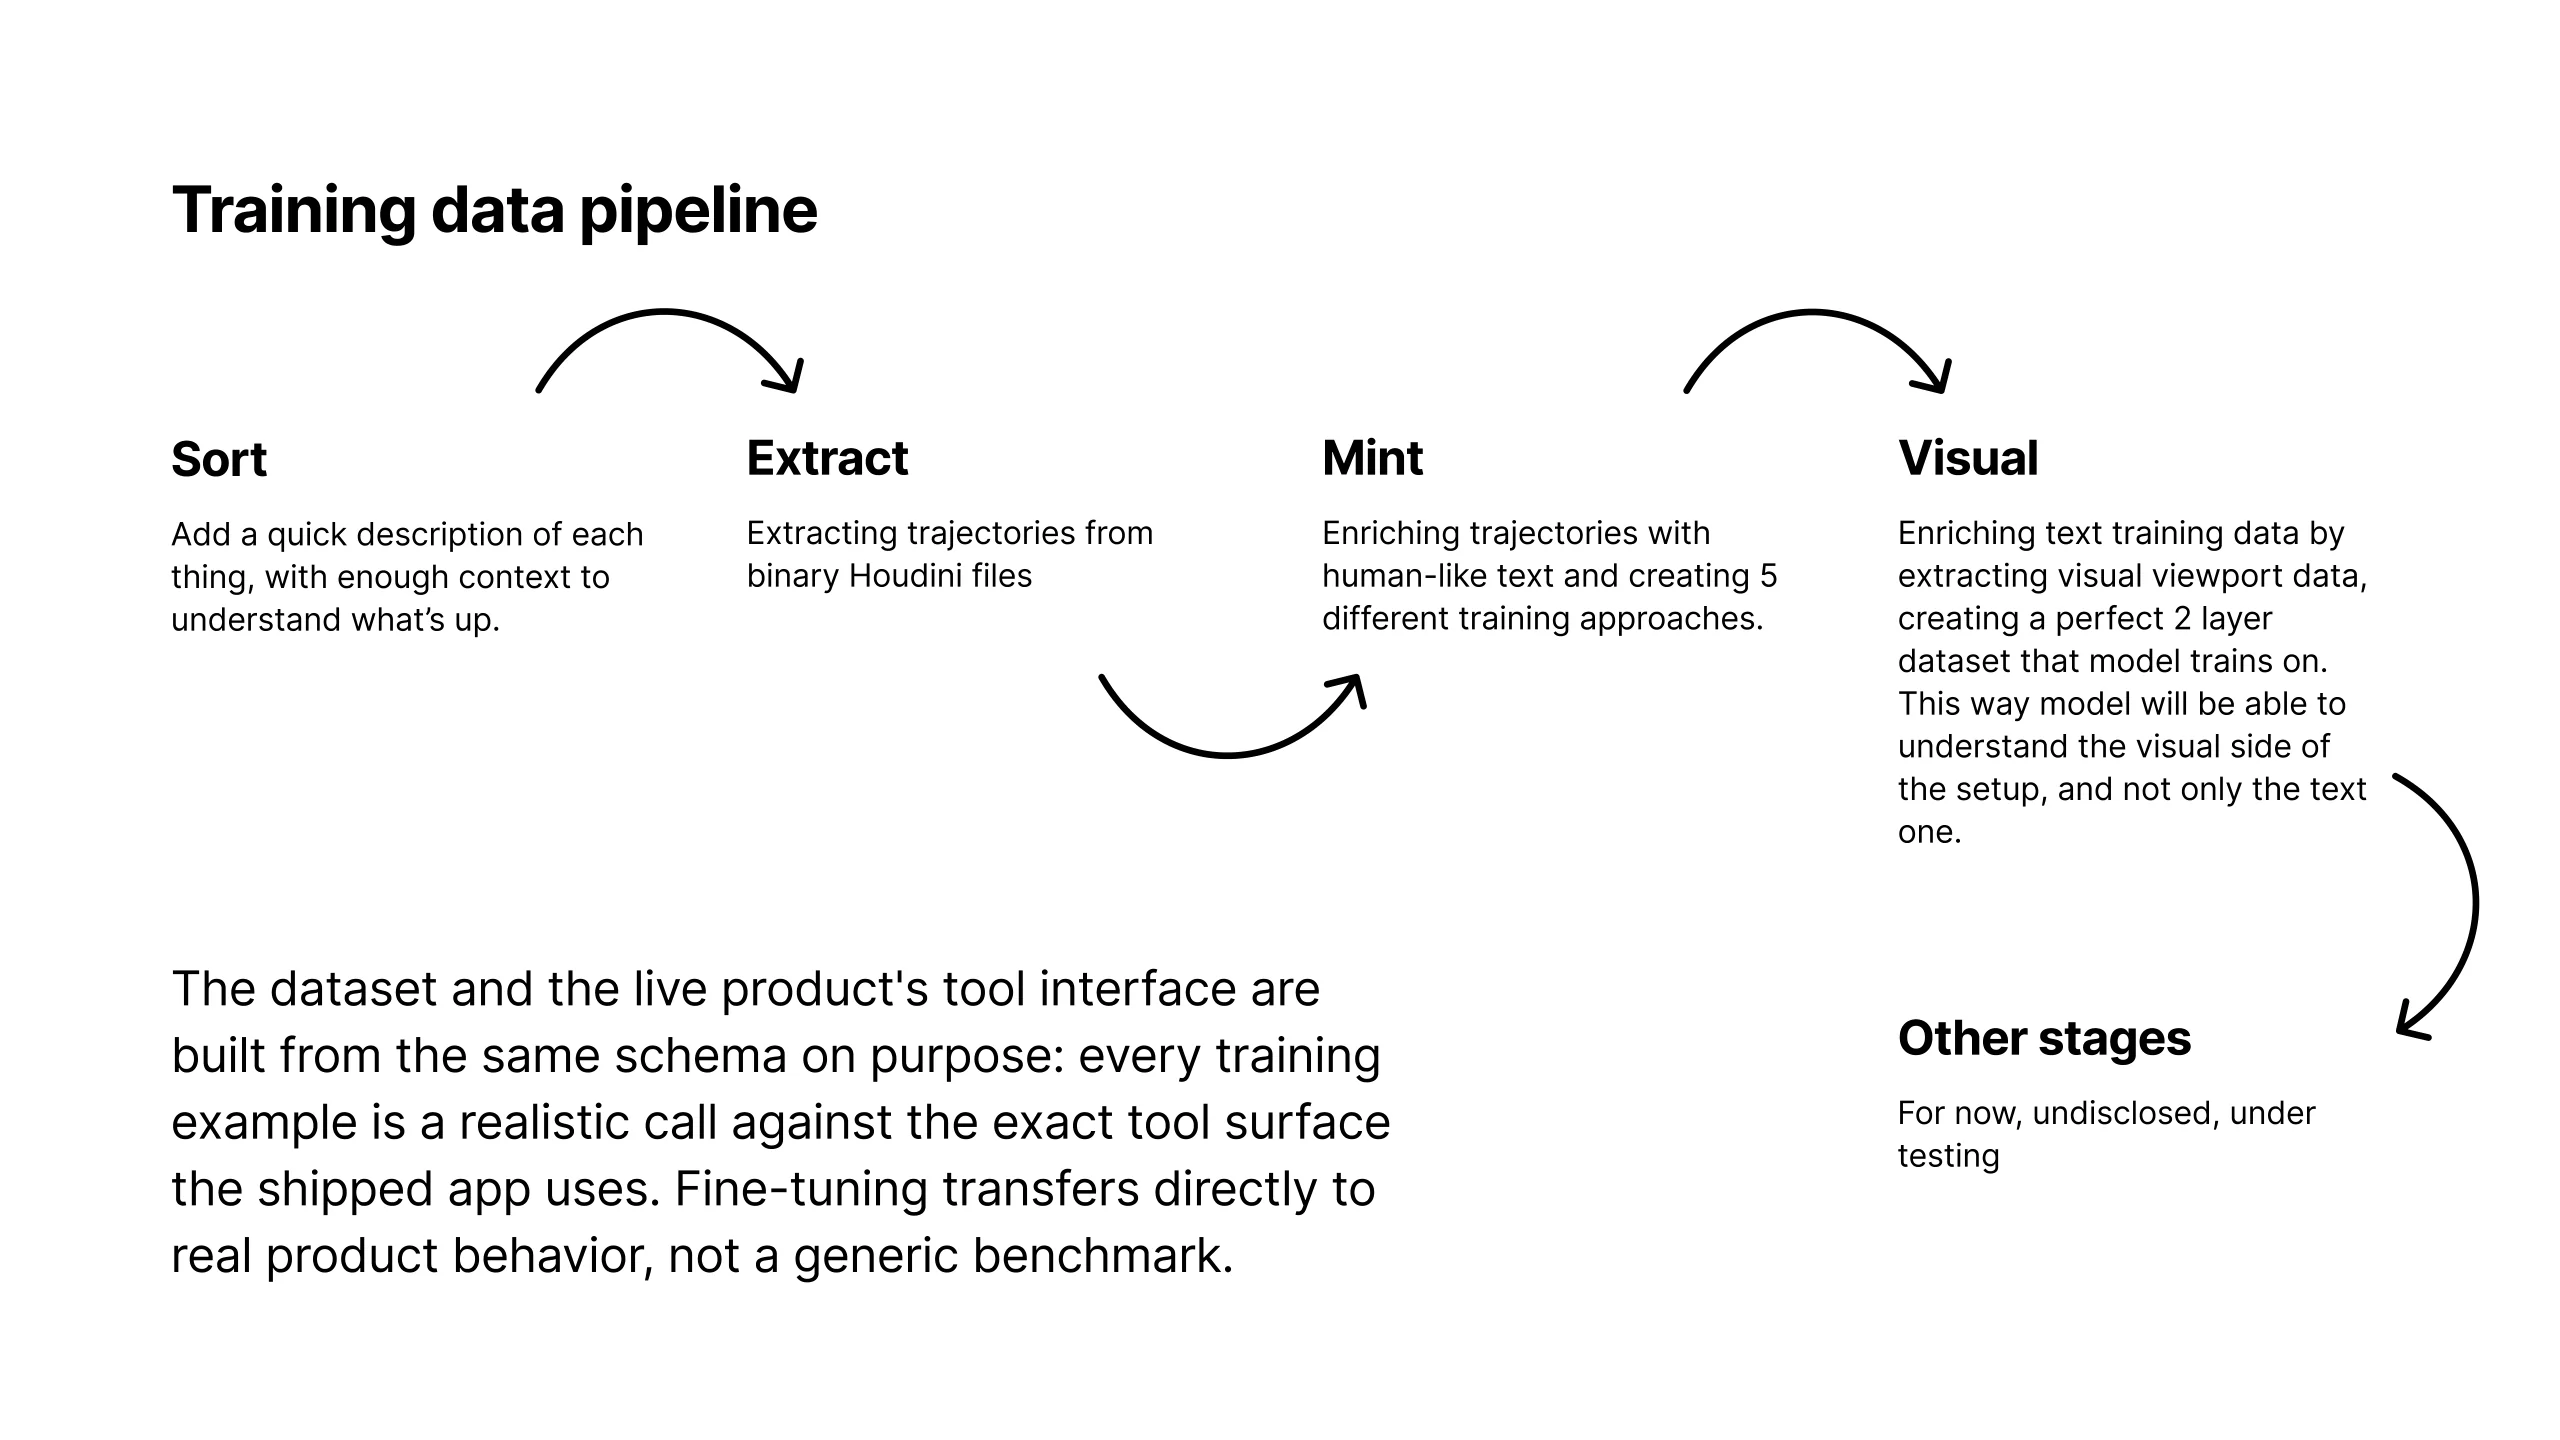
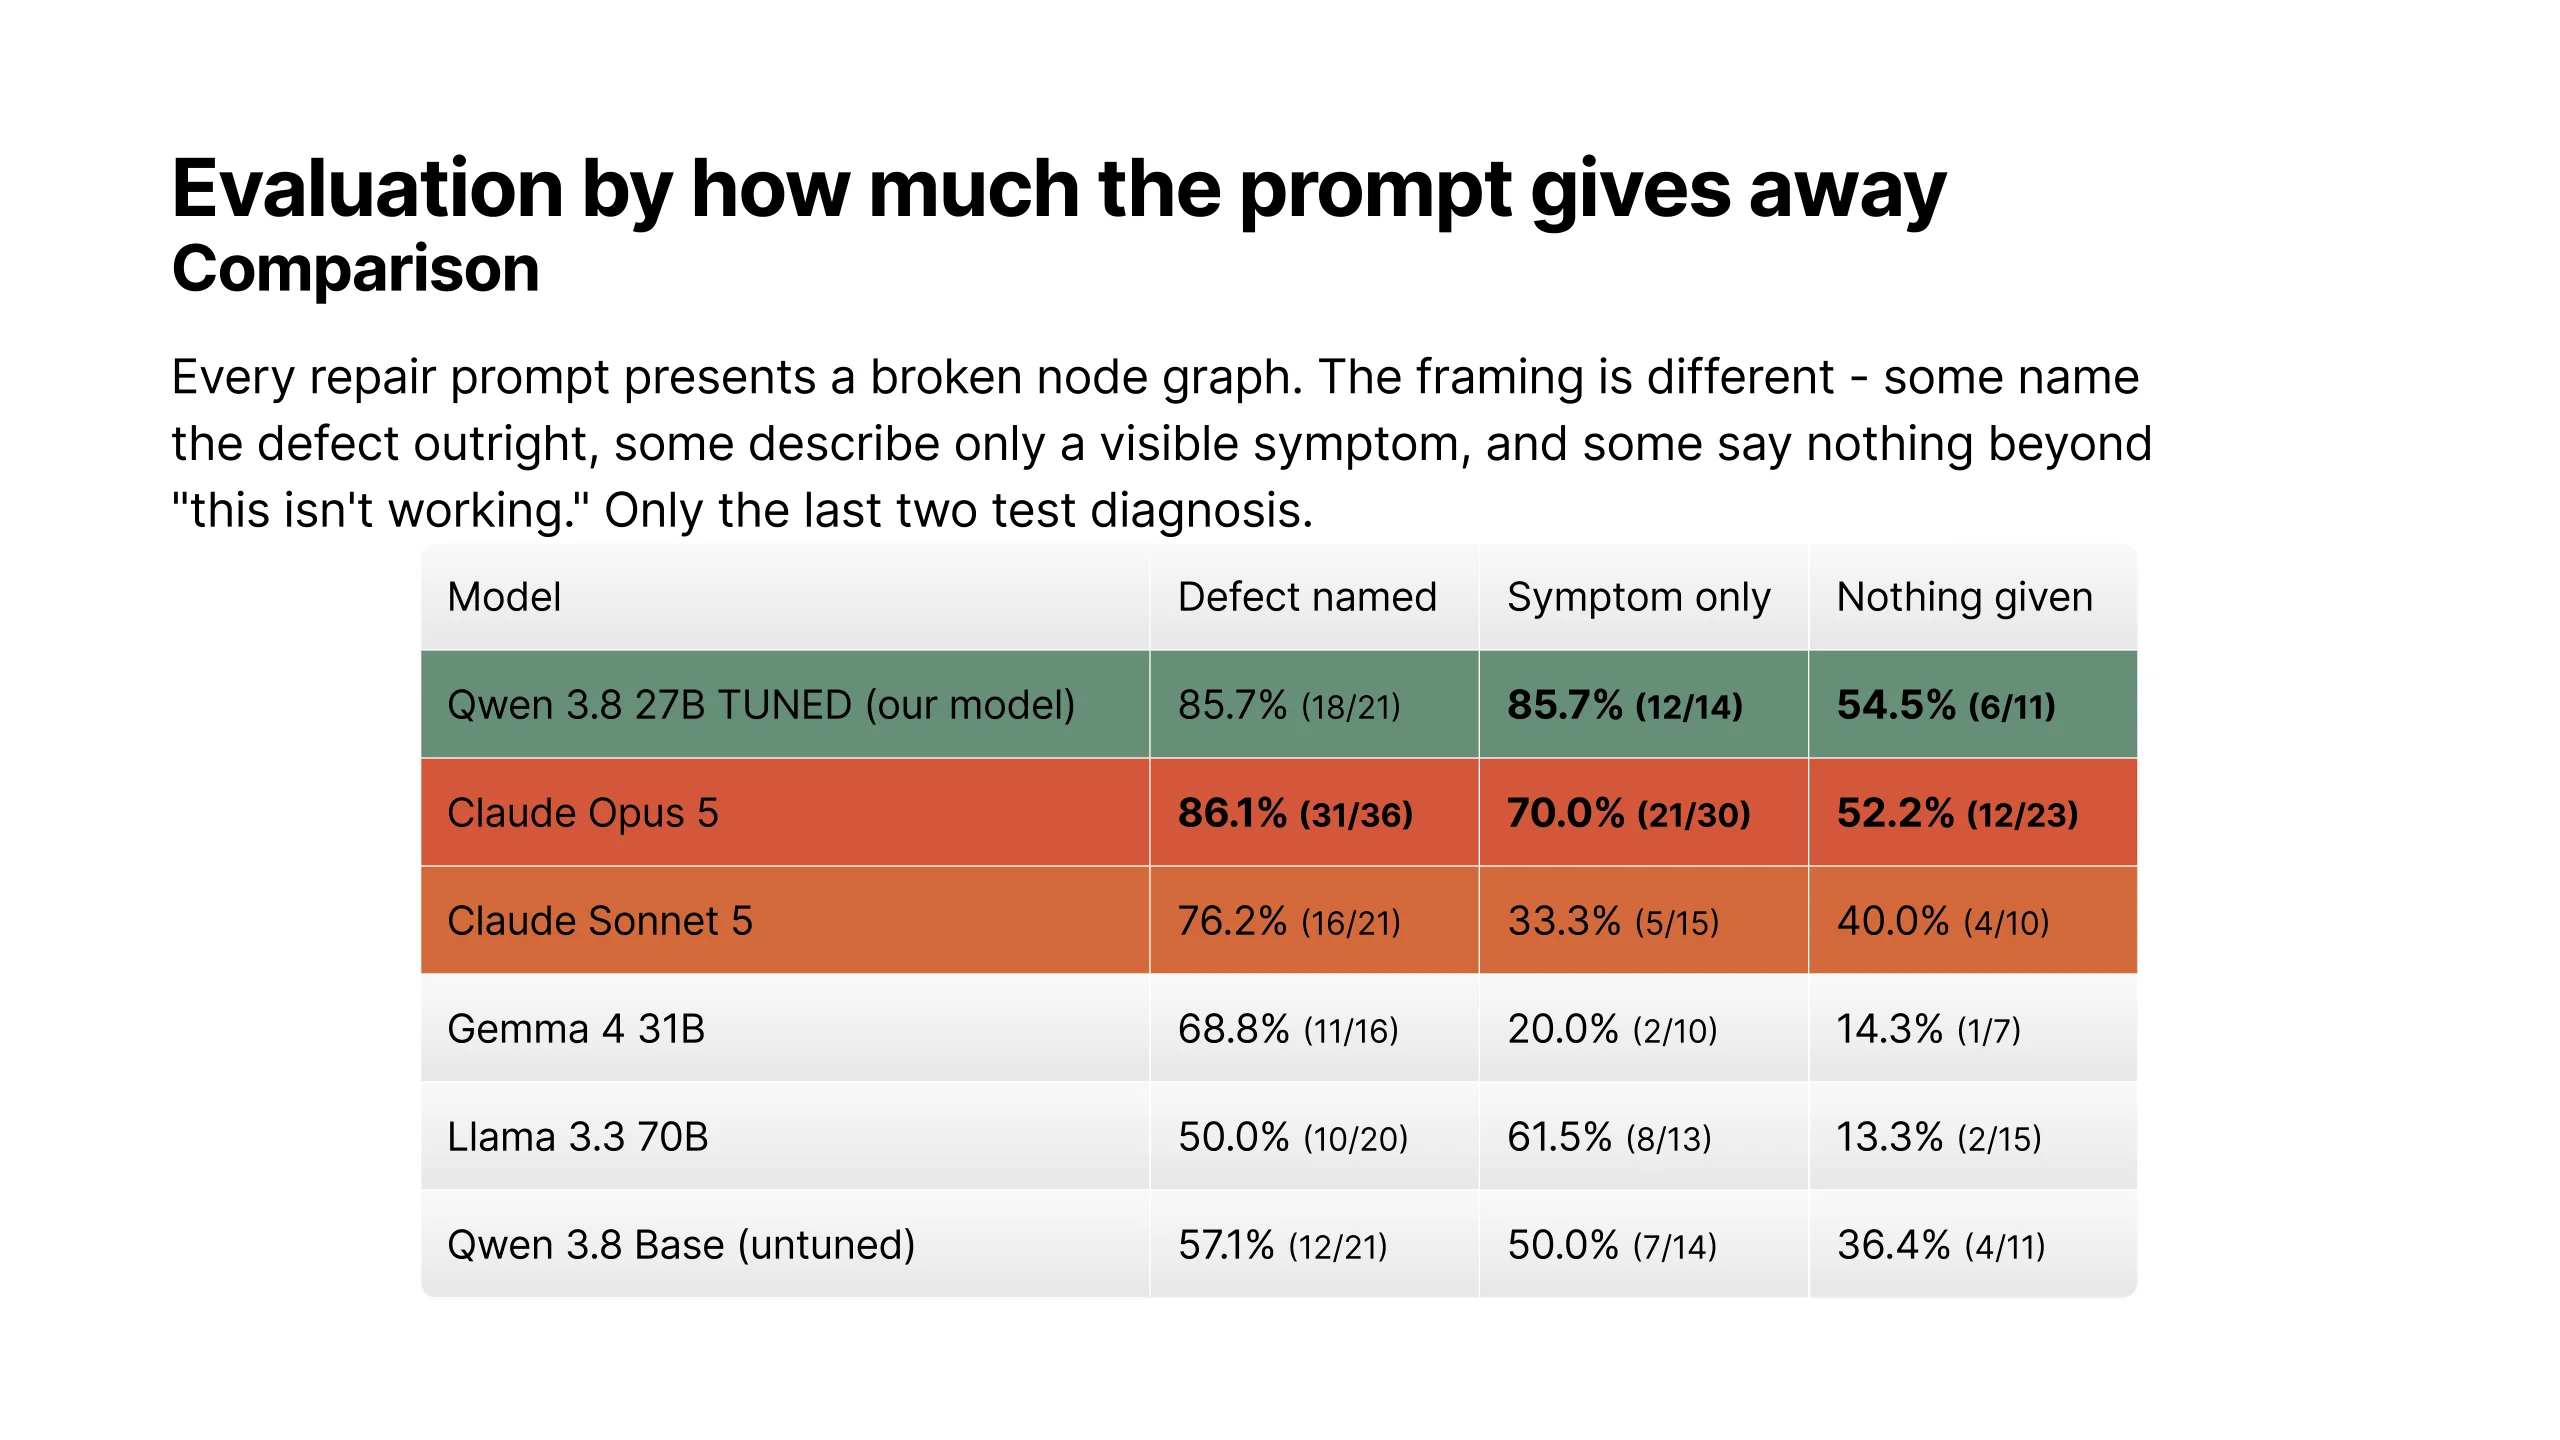
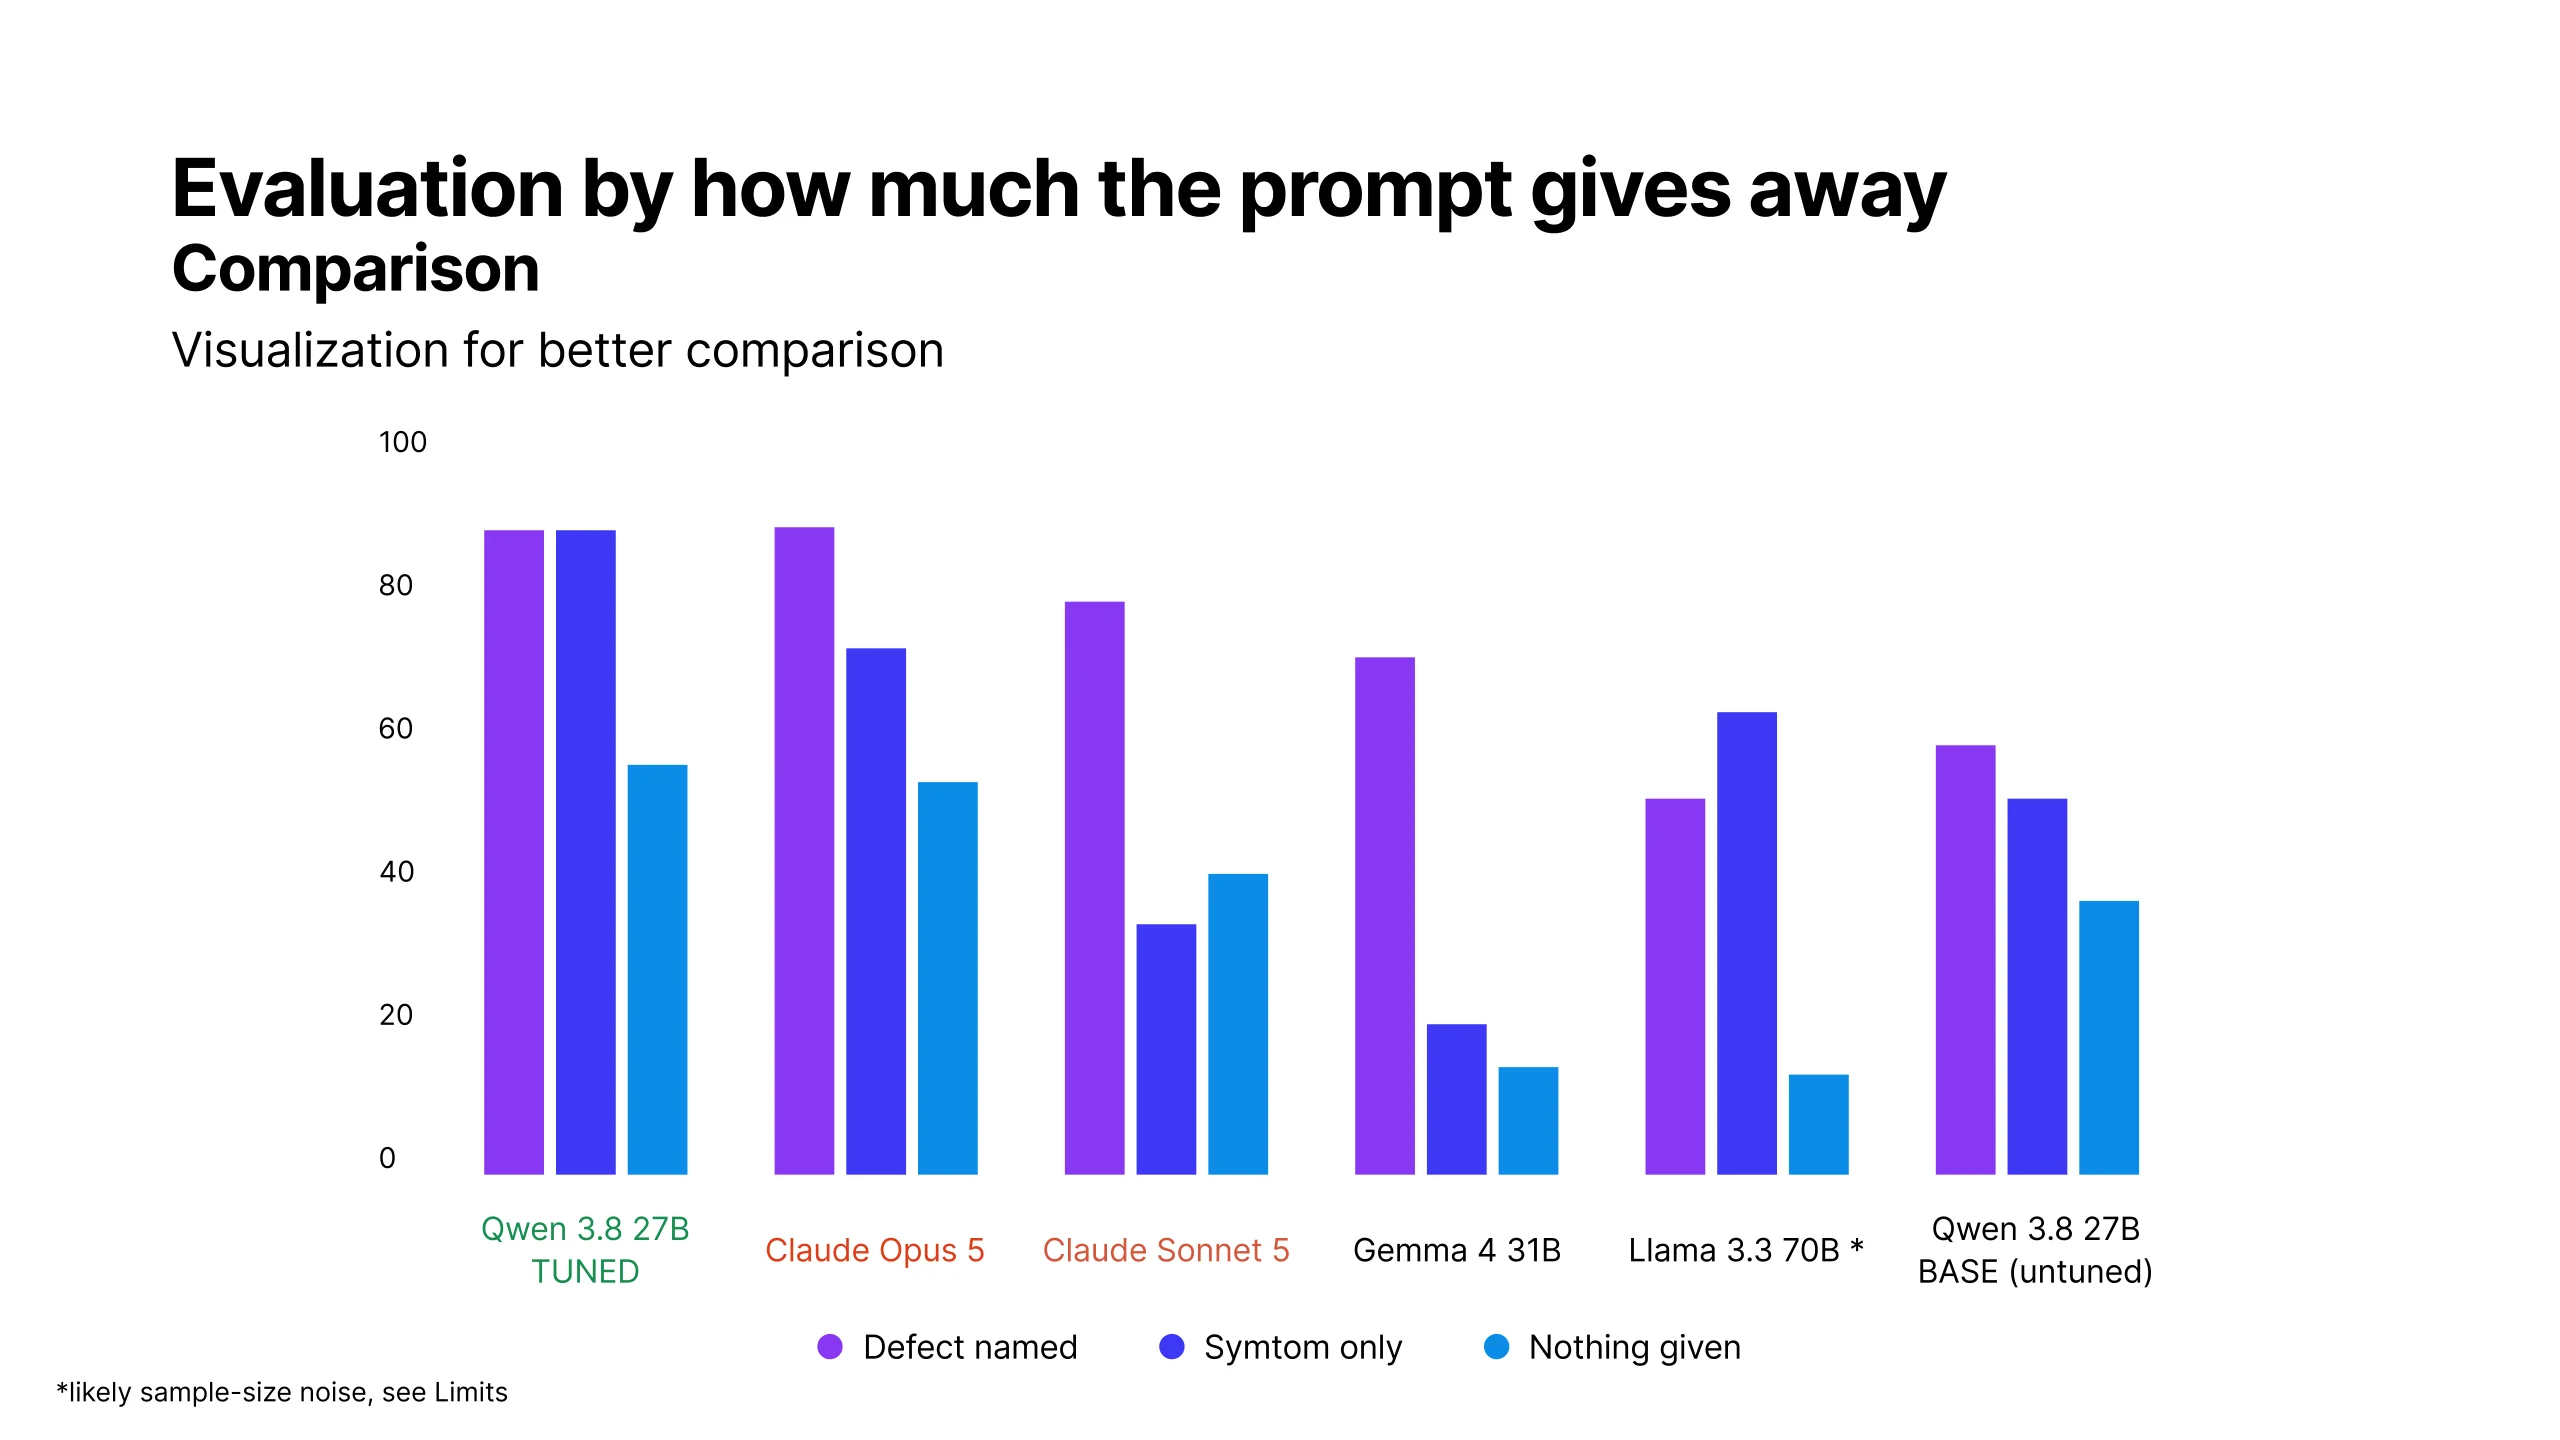
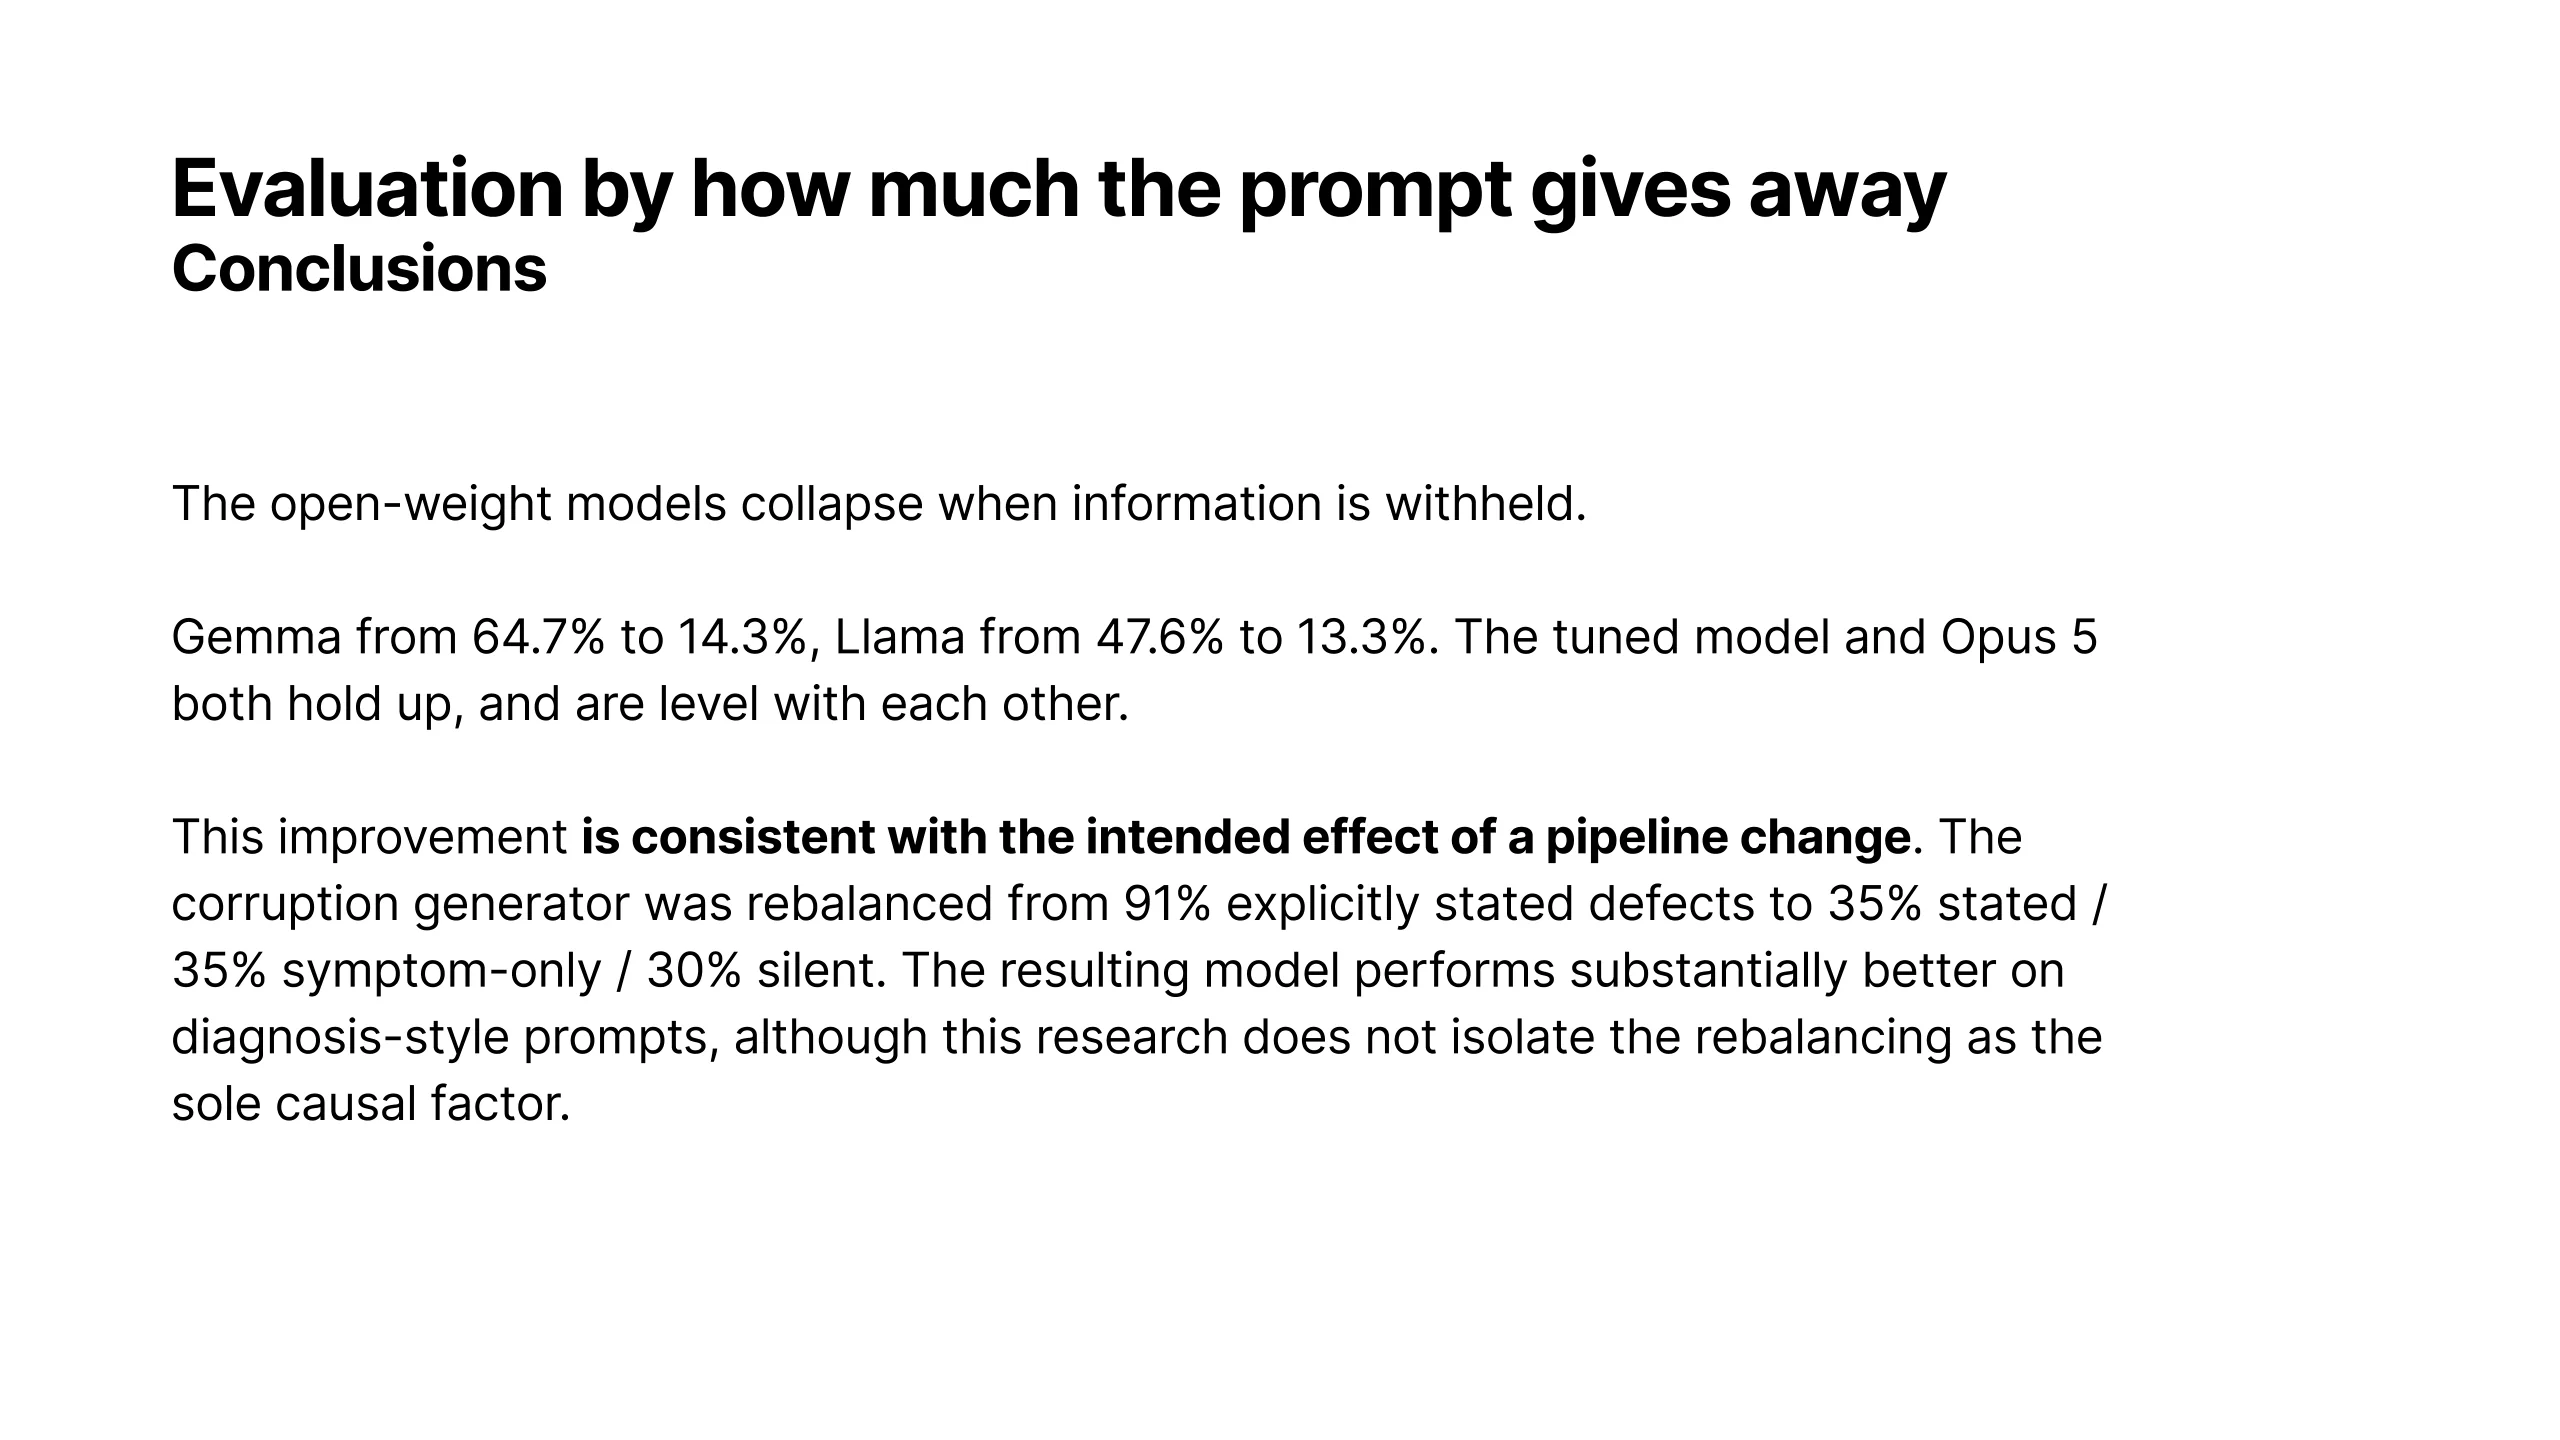
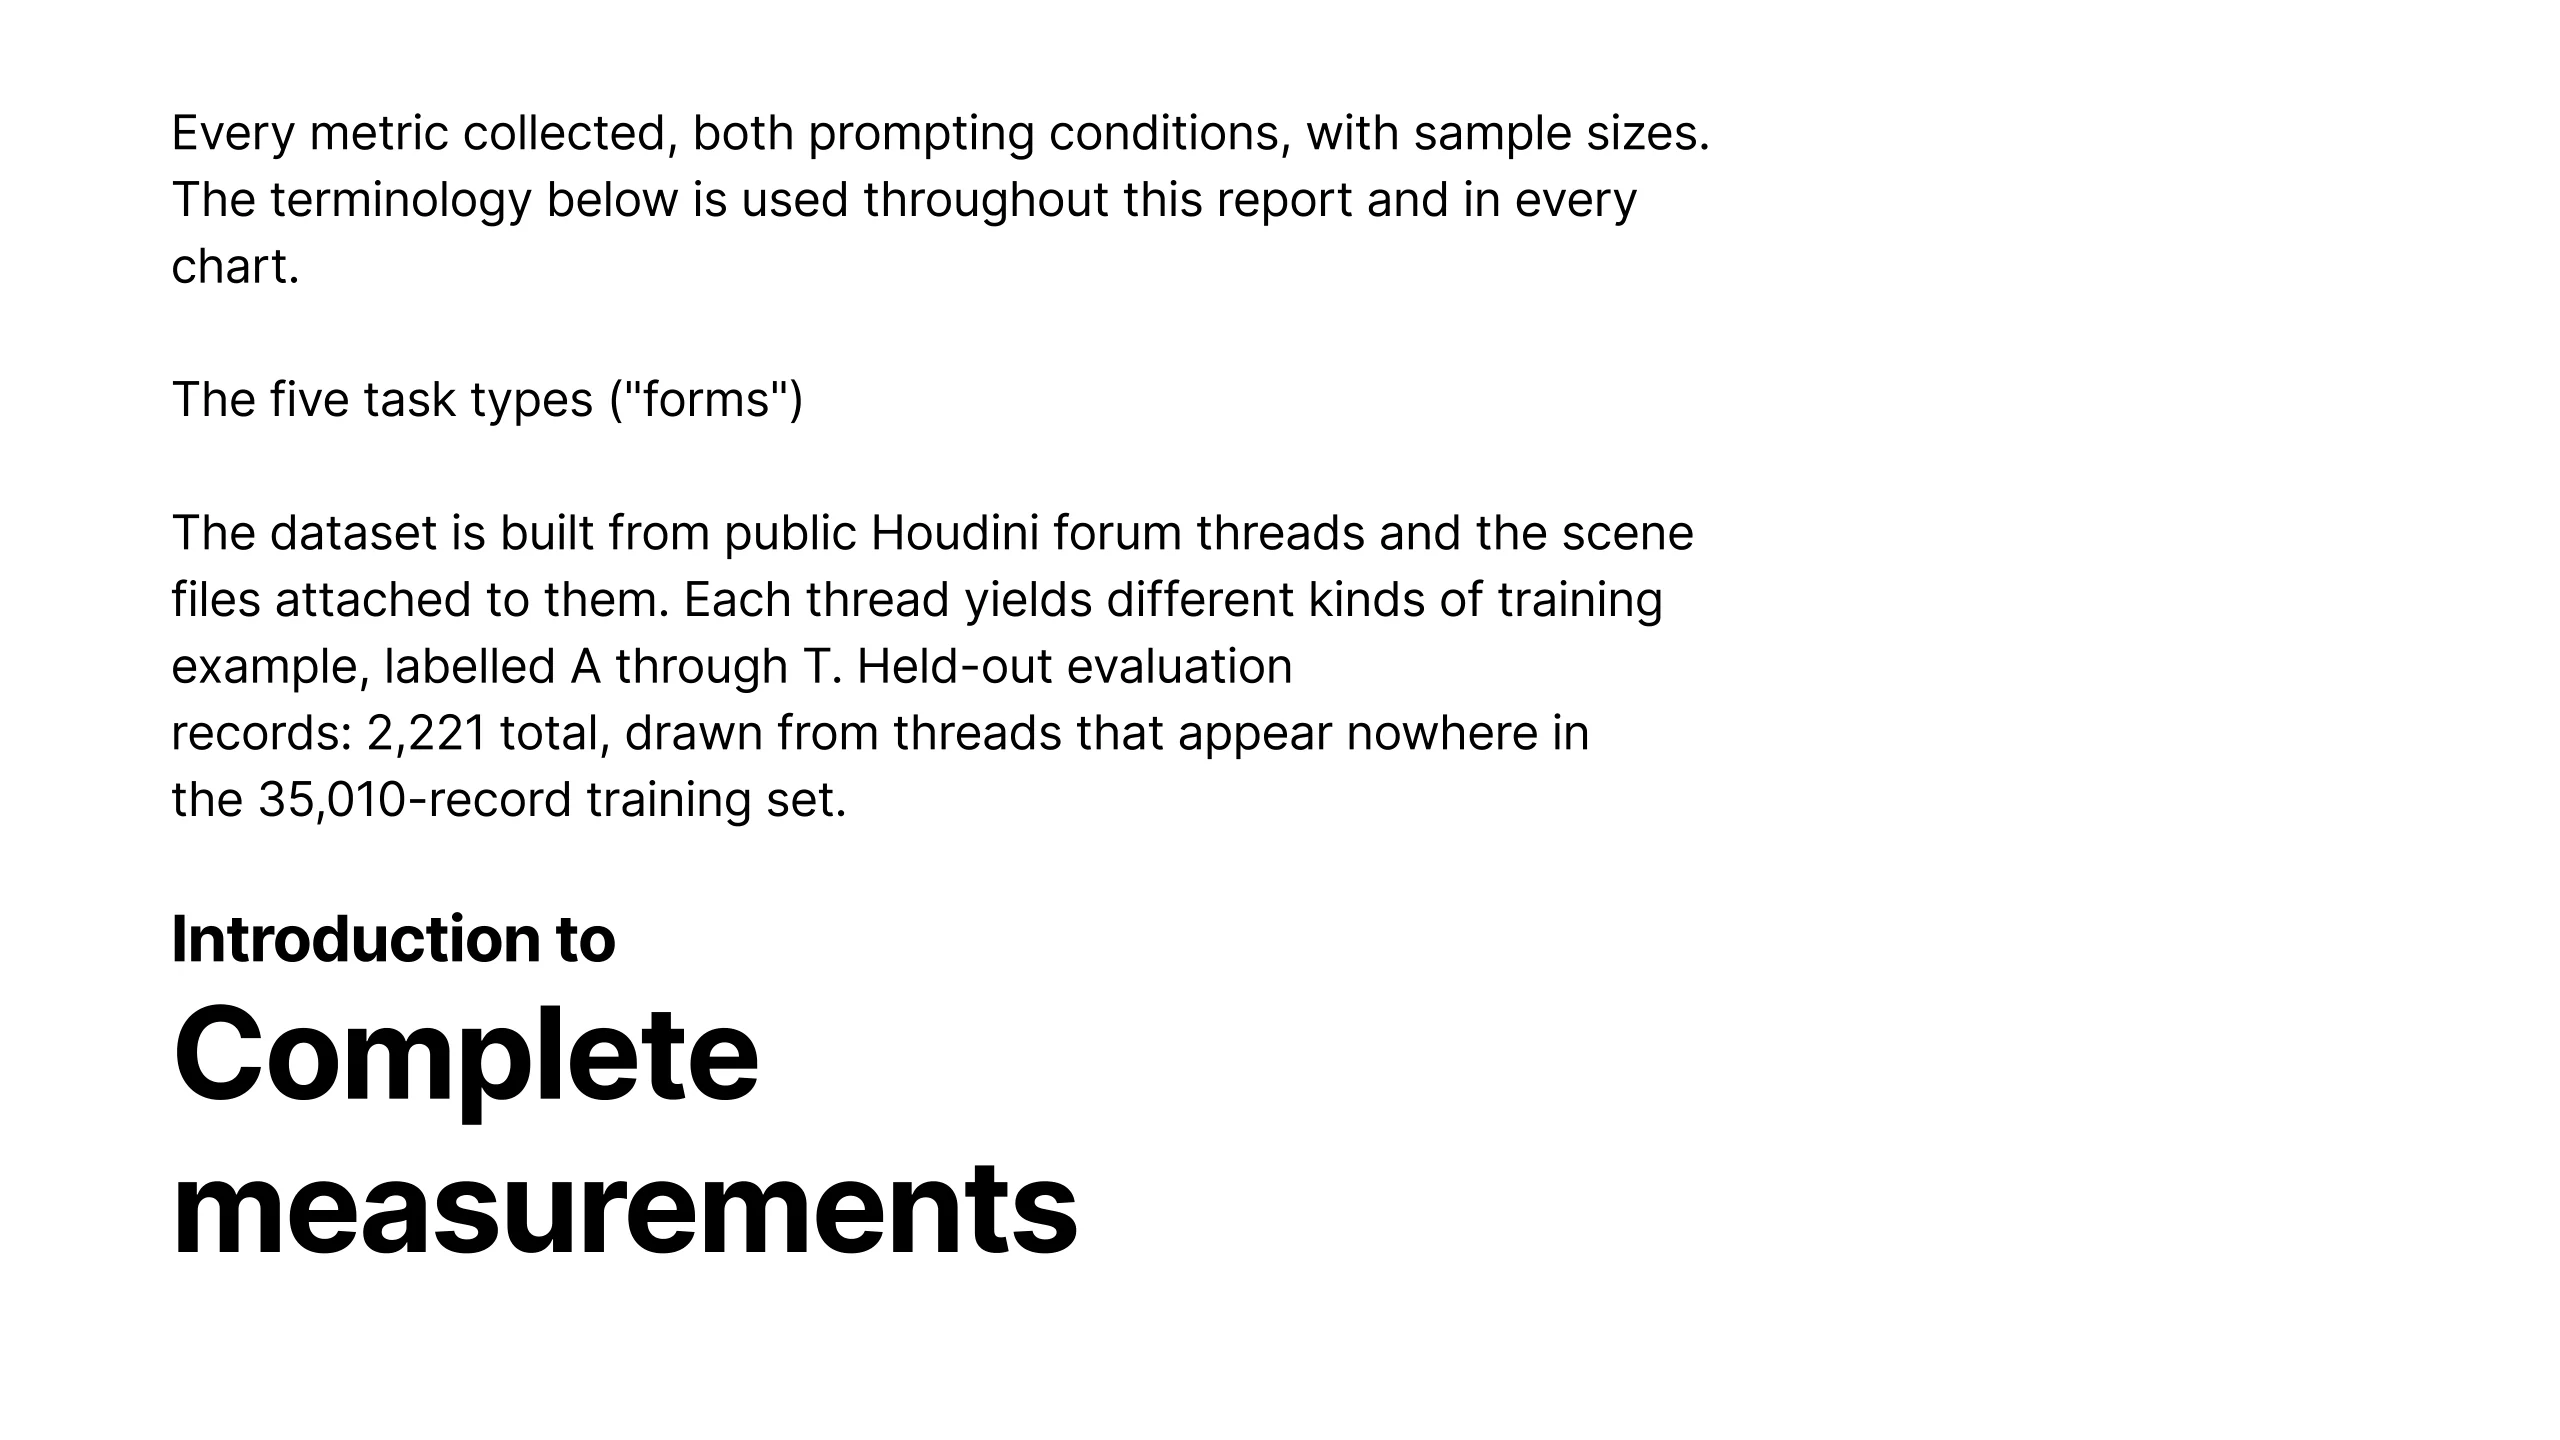
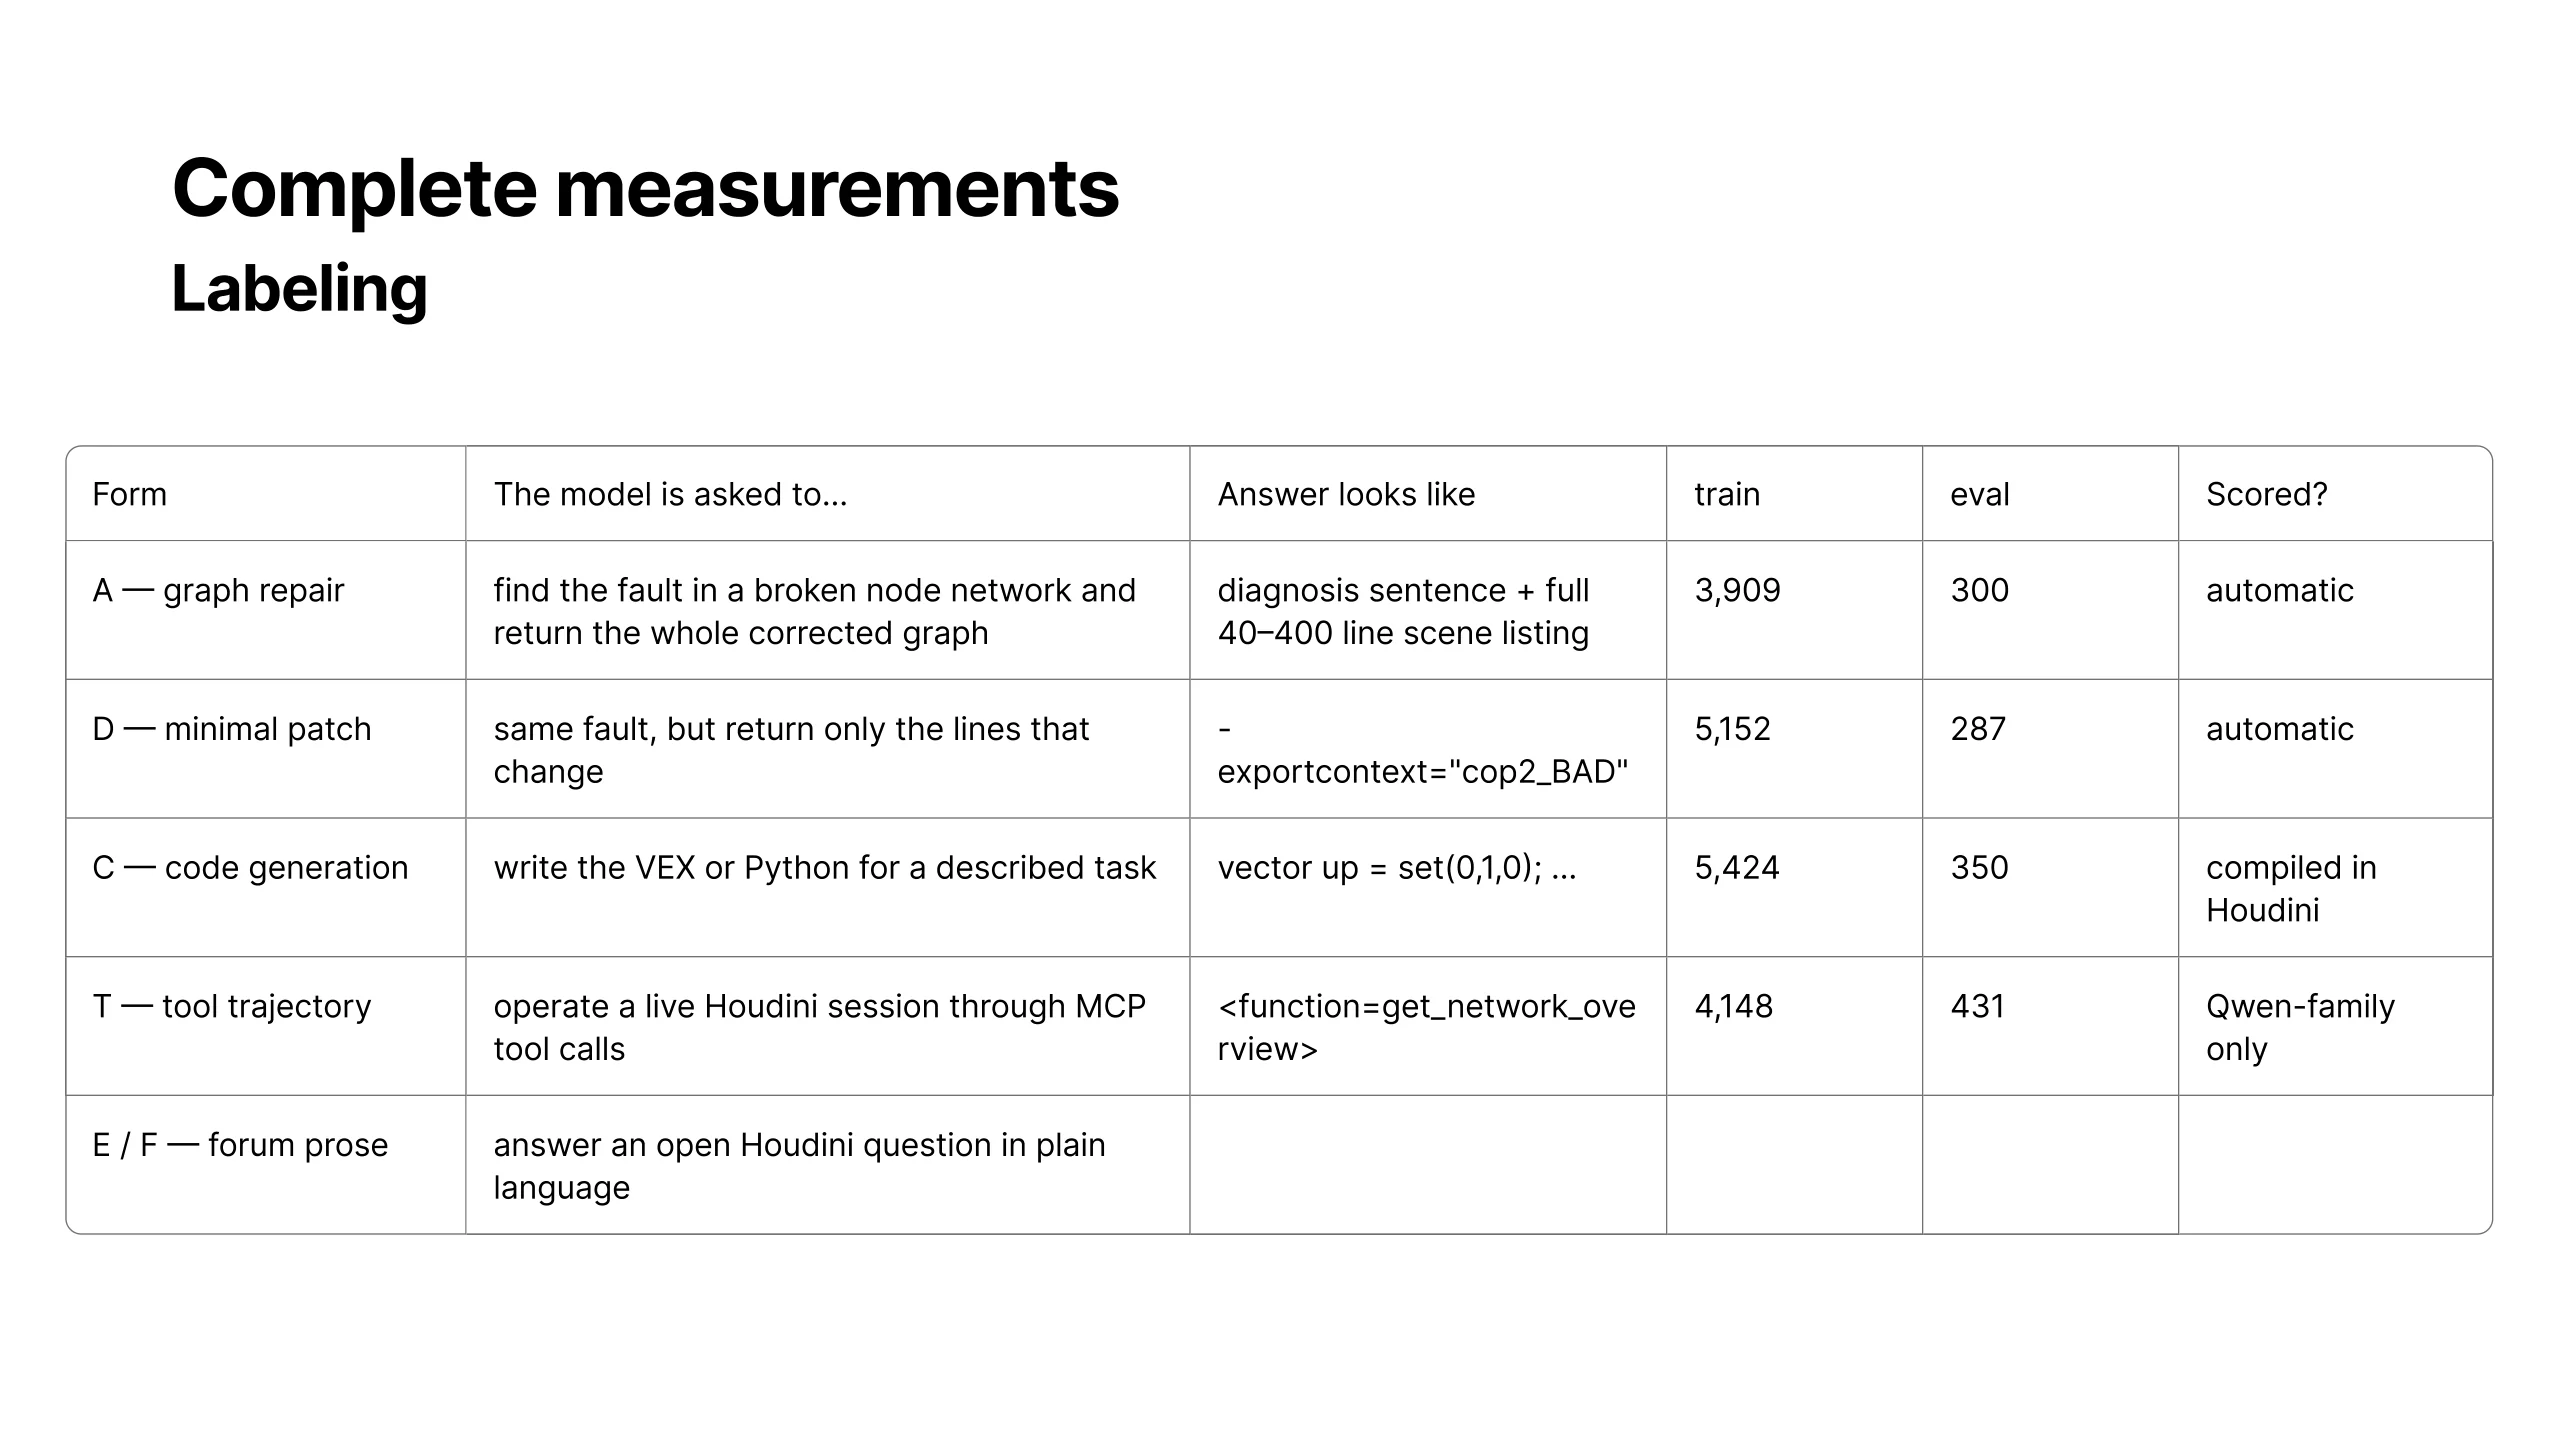
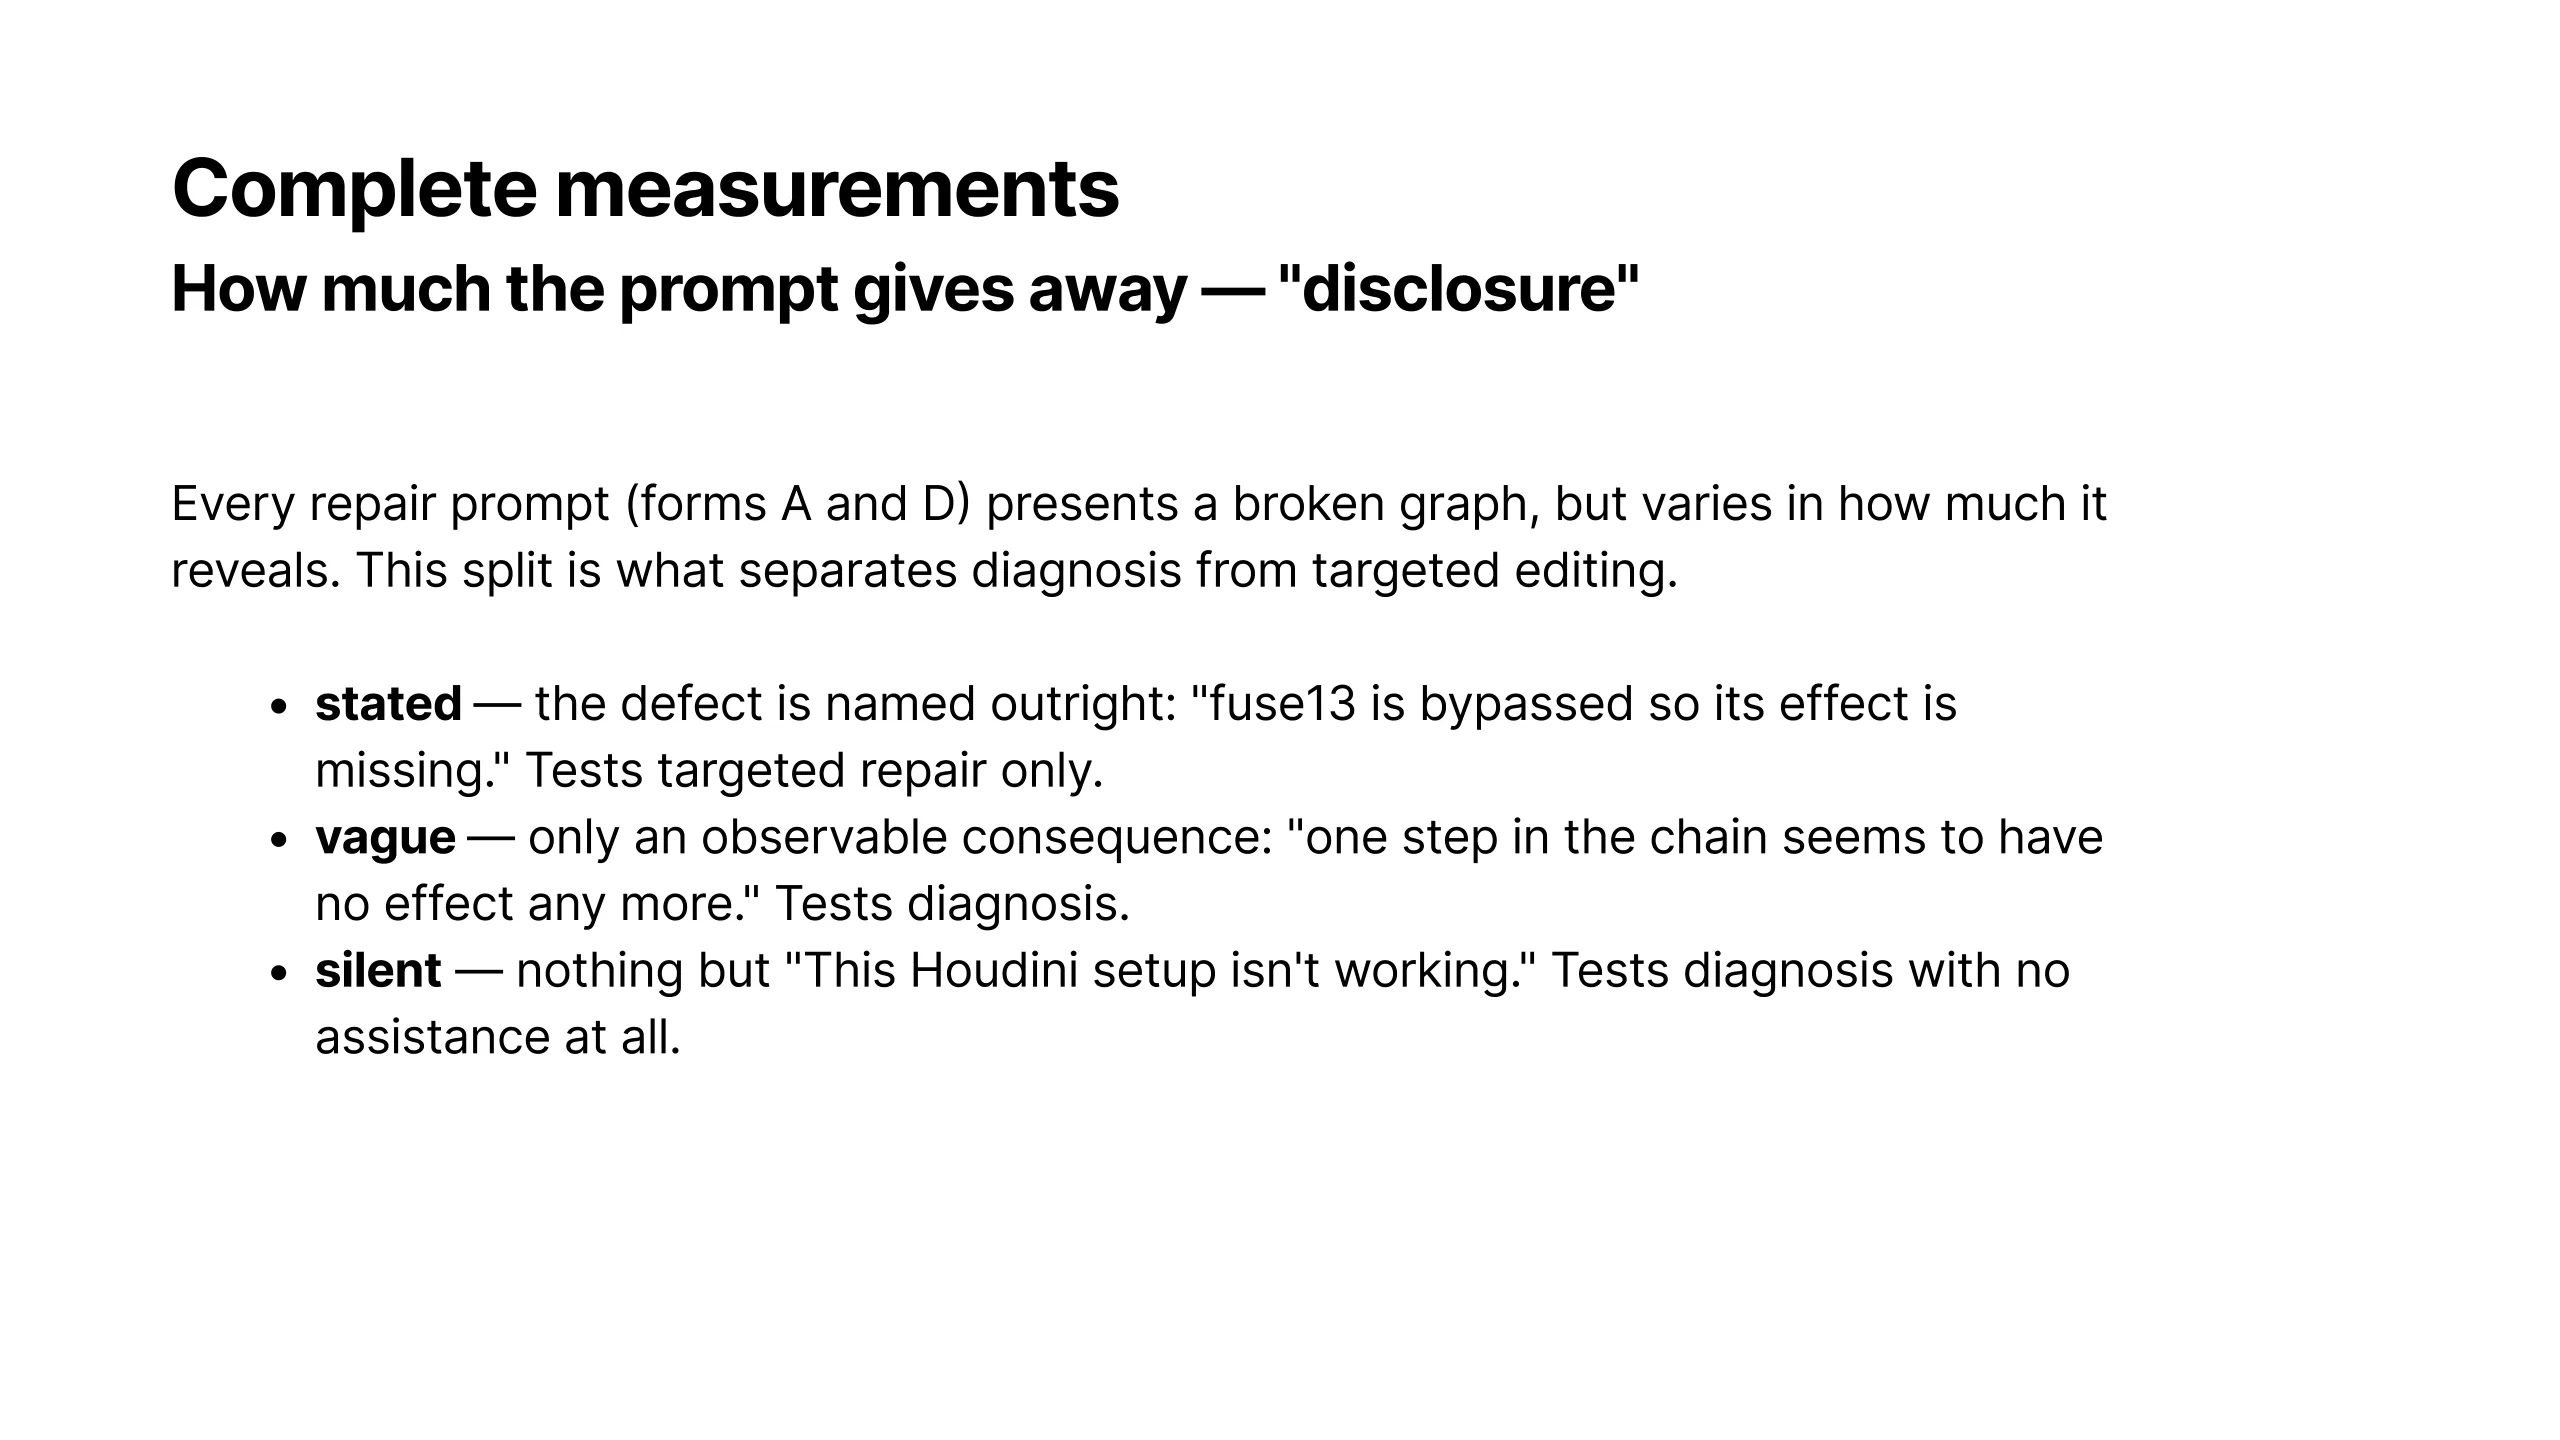
The model learns from a pipeline that turns real Houdini scene files into training examples written in the exact tool format the app uses, so what it learns is what it can do. A corruption engine breaks working node graphs on purpose to create broken-and-fixed pairs with known-correct answers. Only a third of those examples name the fault; the rest describe a symptom or say nothing at all, so the model learns to diagnose rather than just follow instructions.
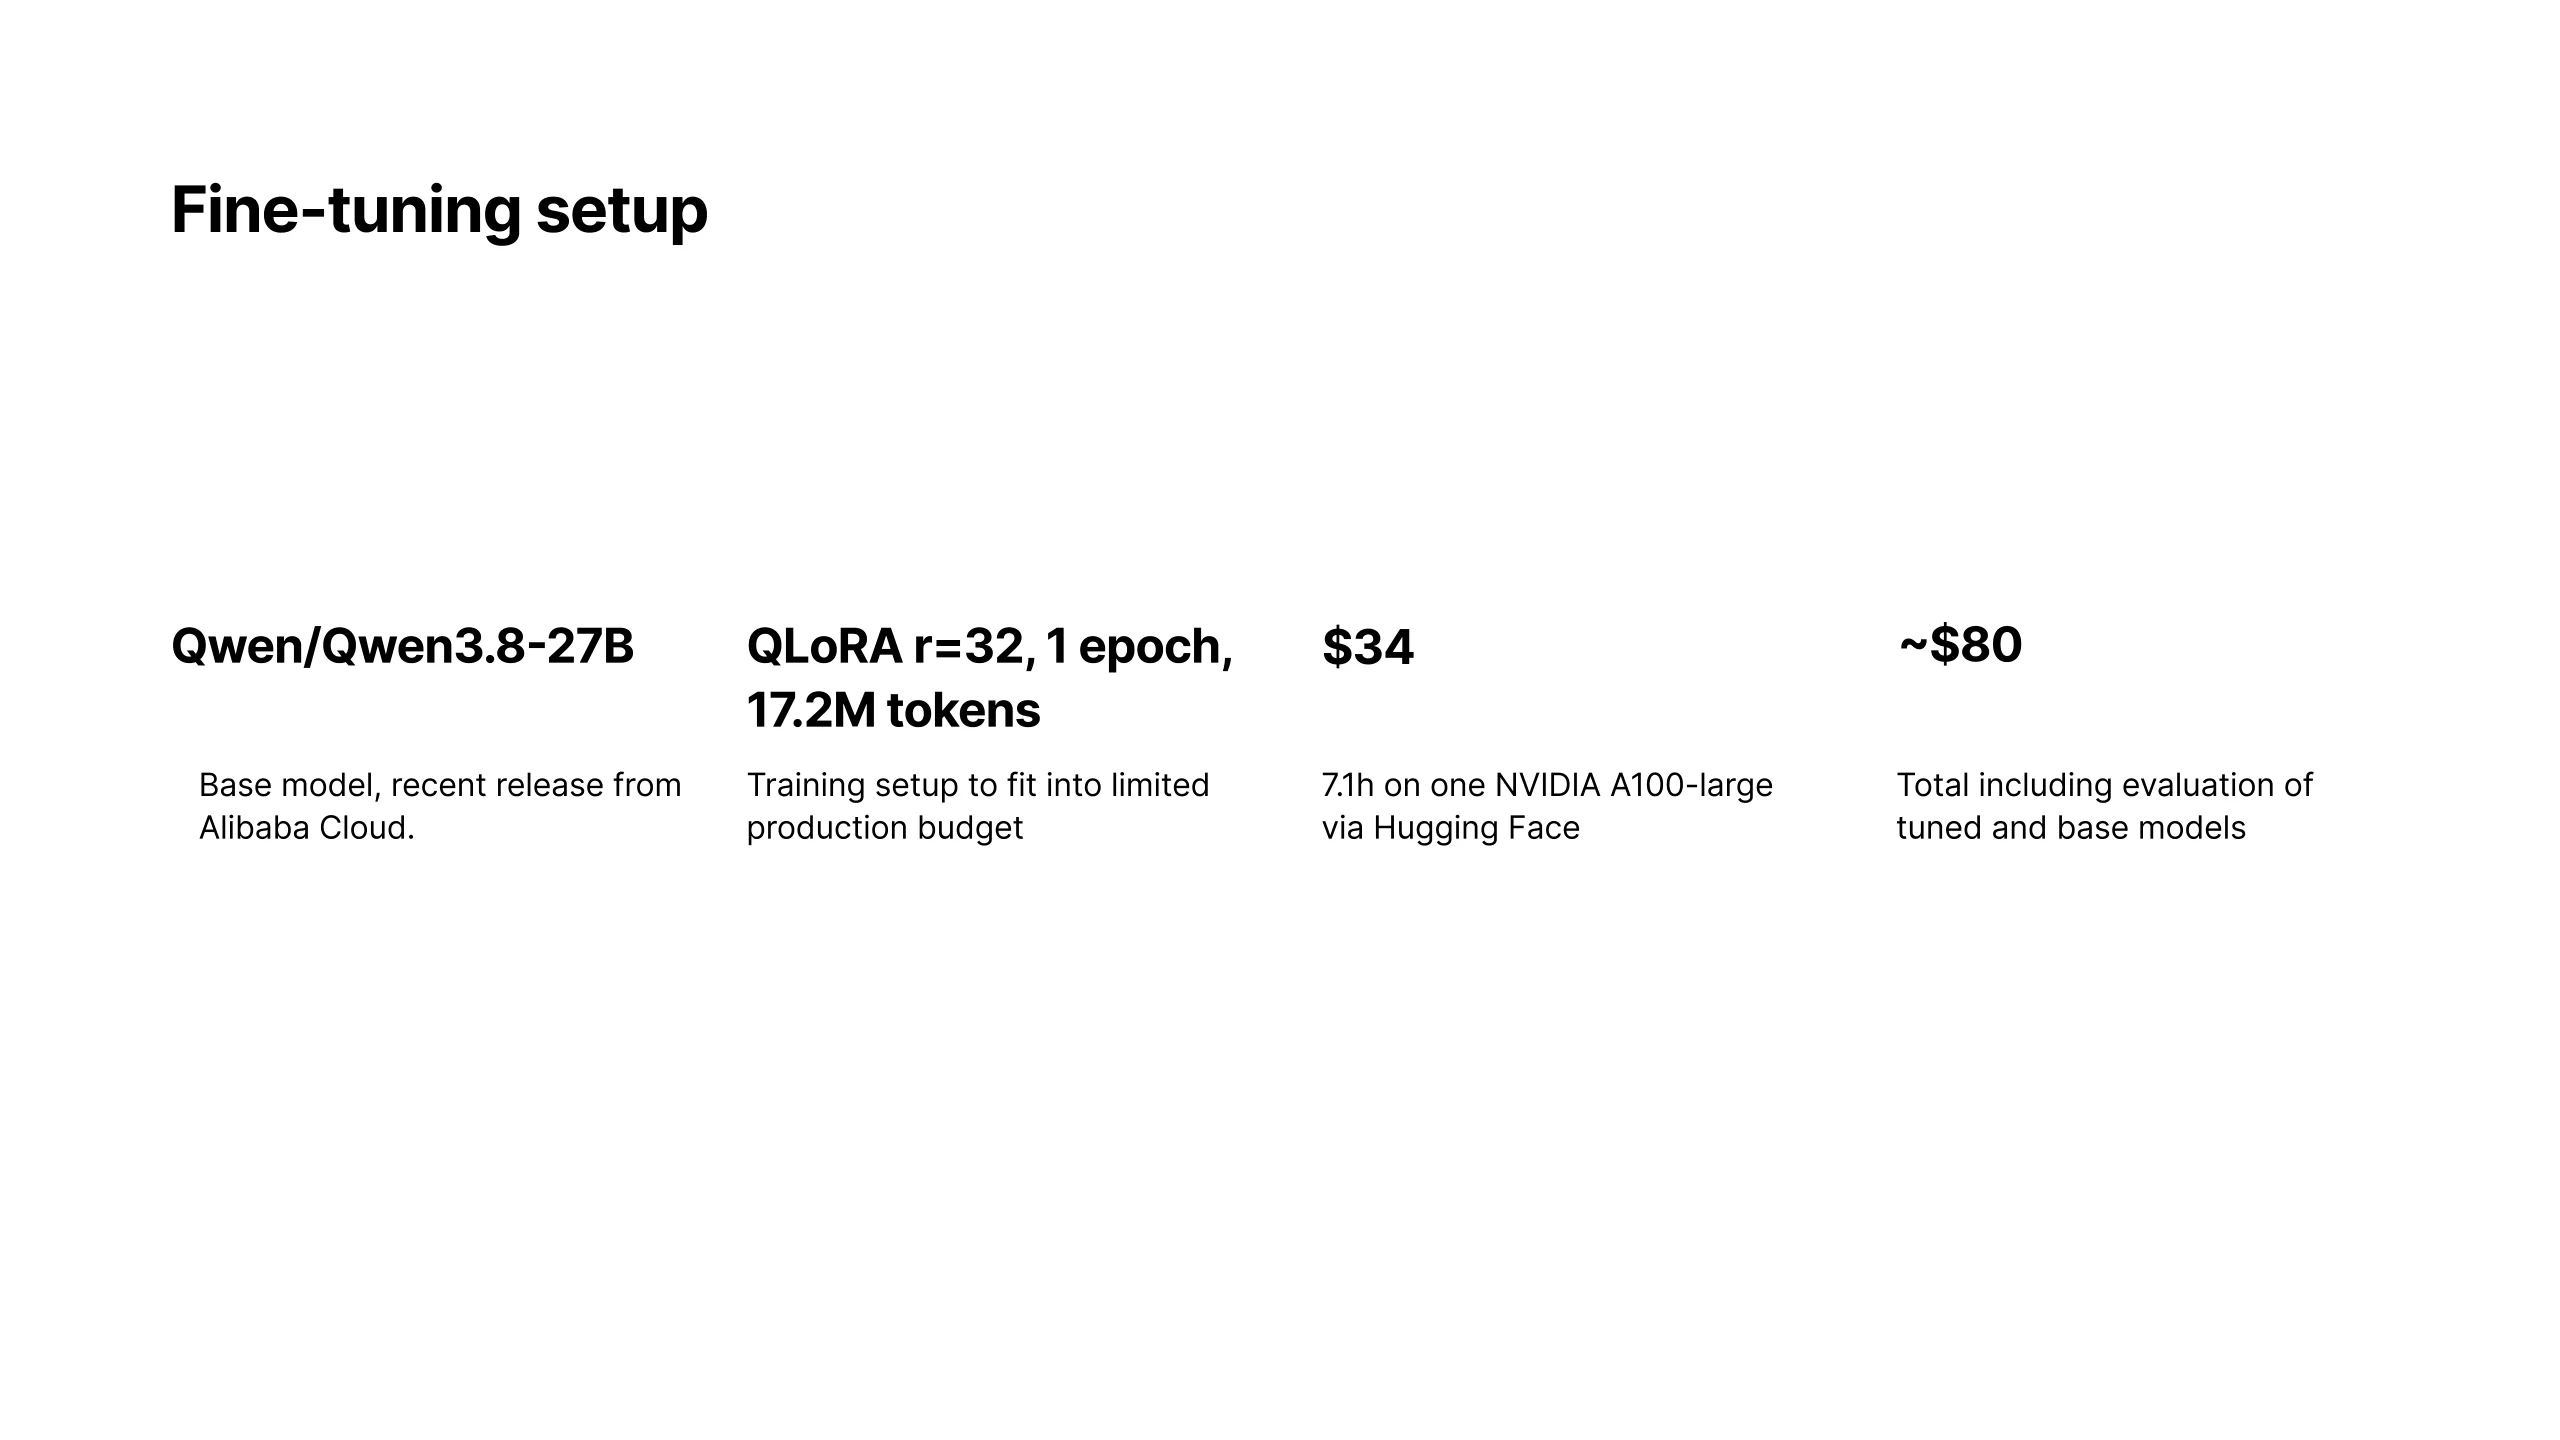
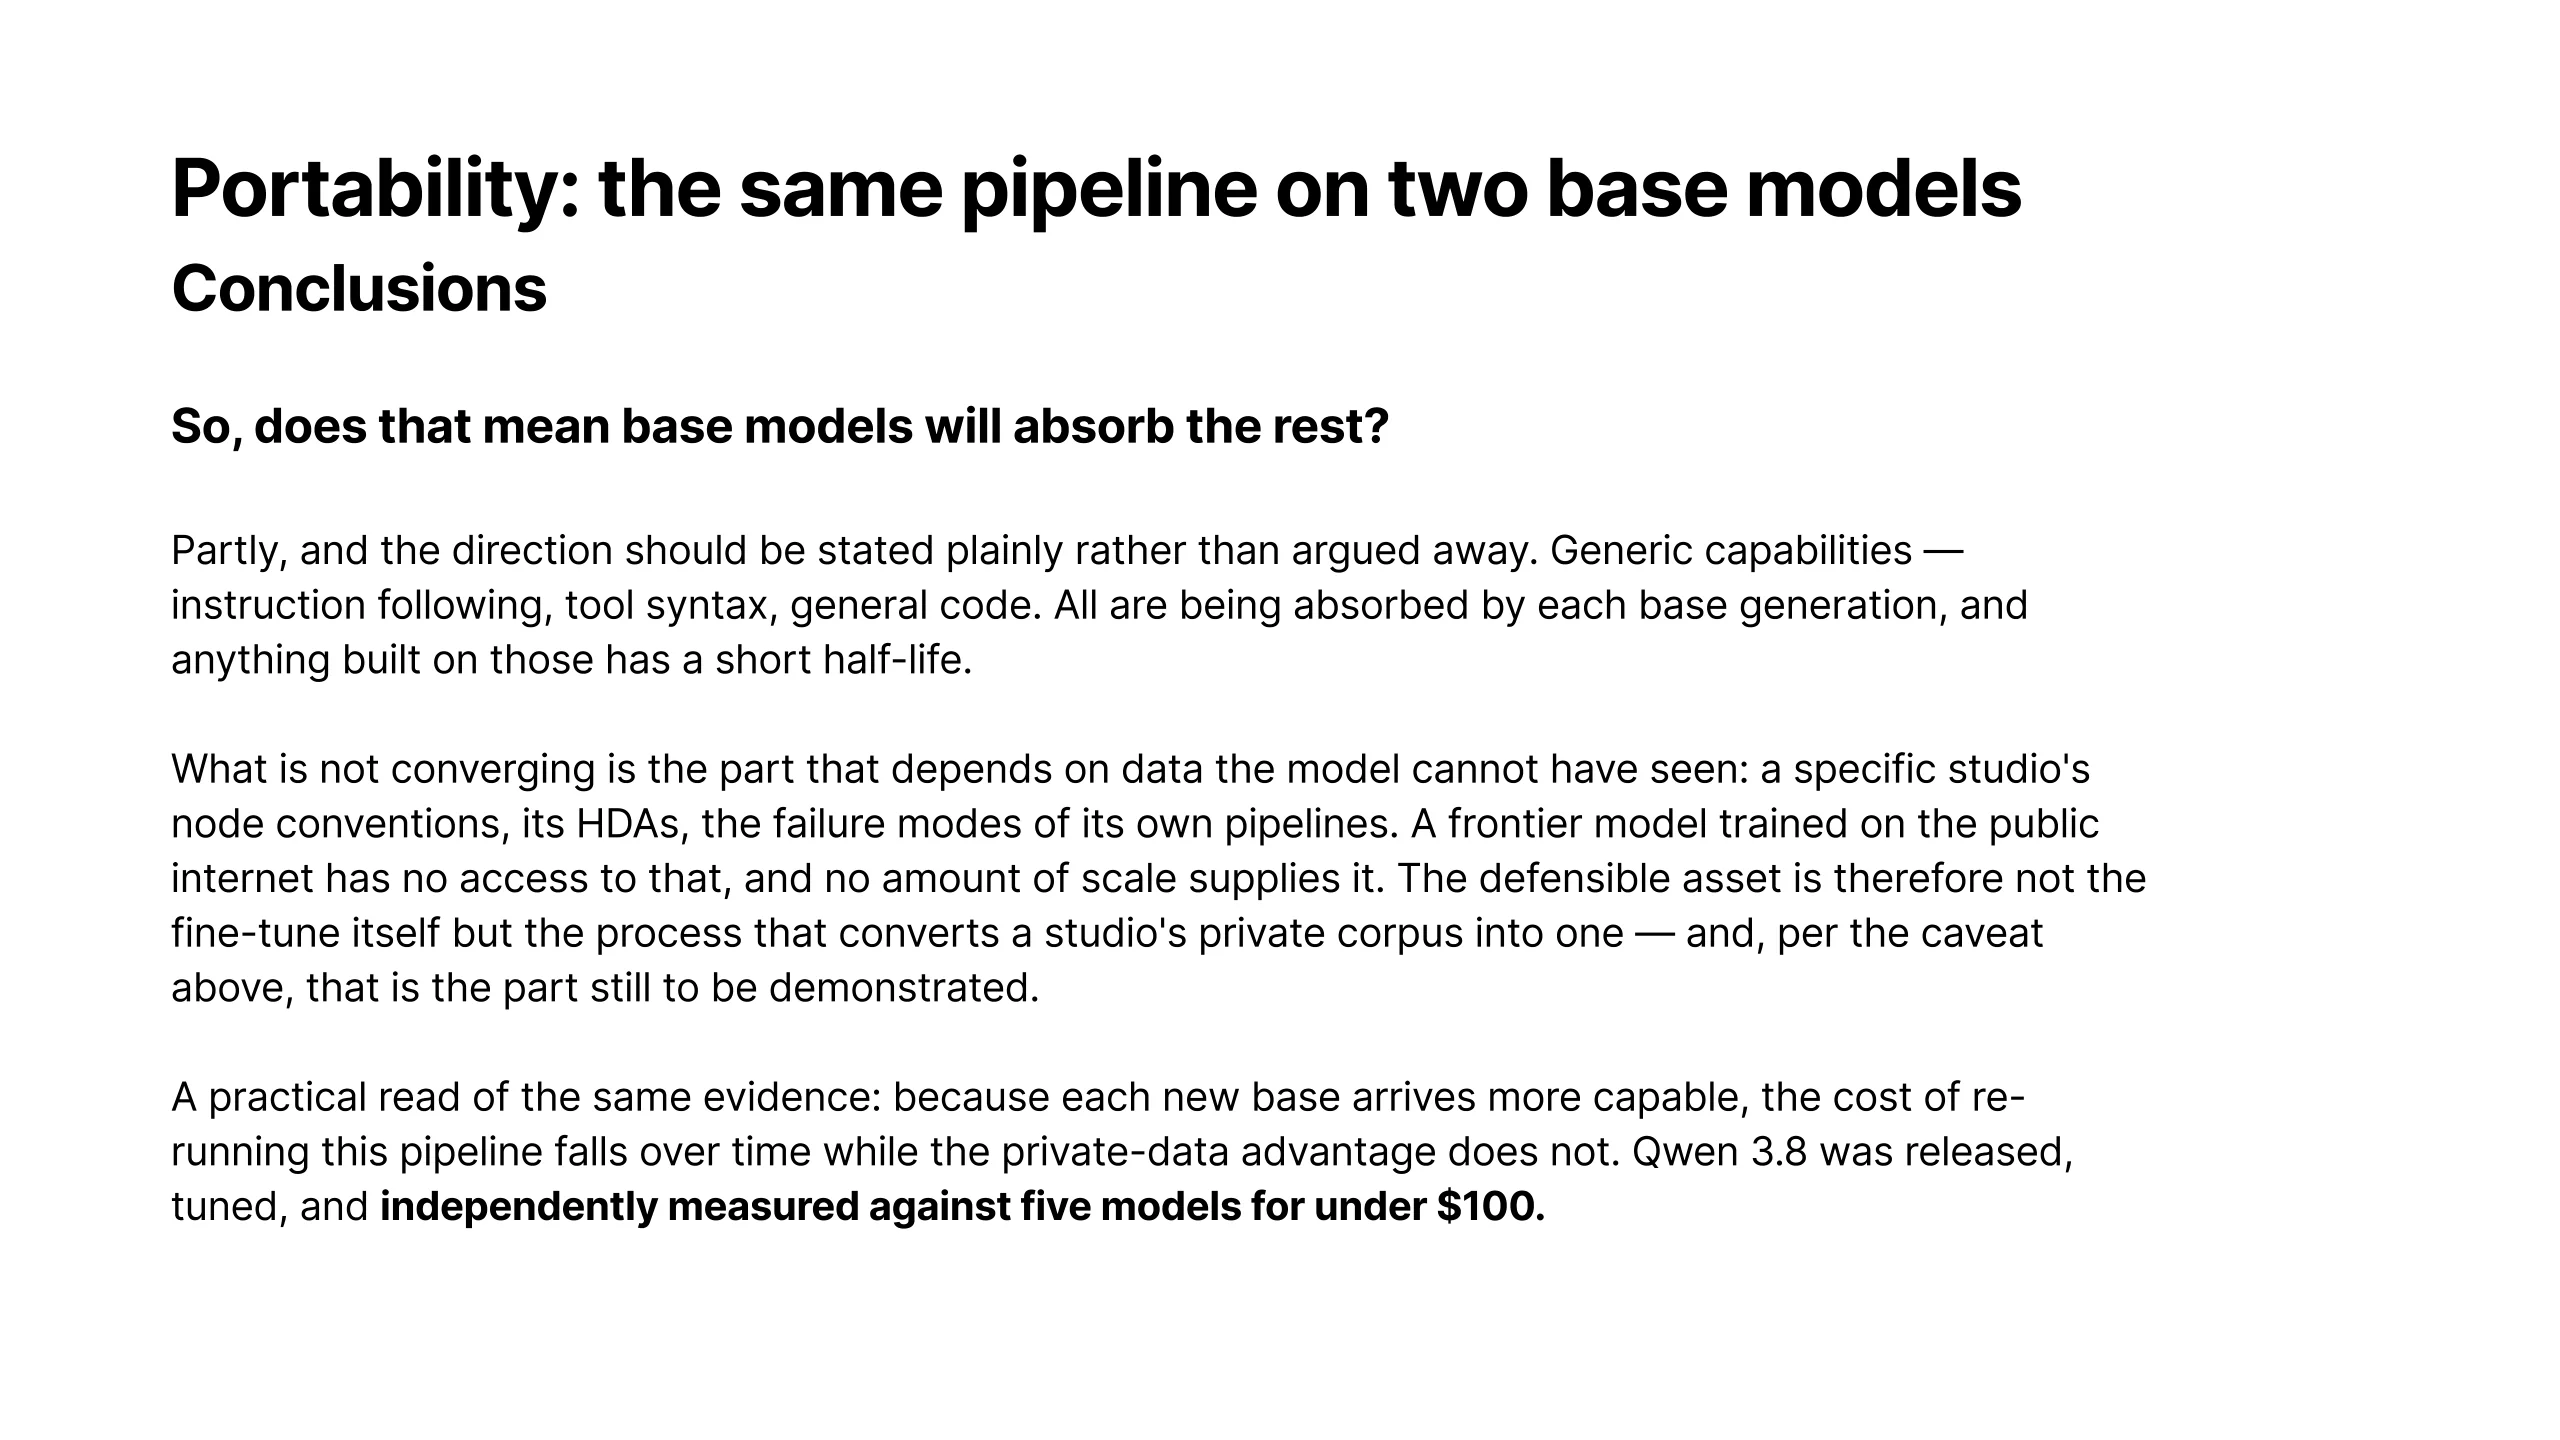
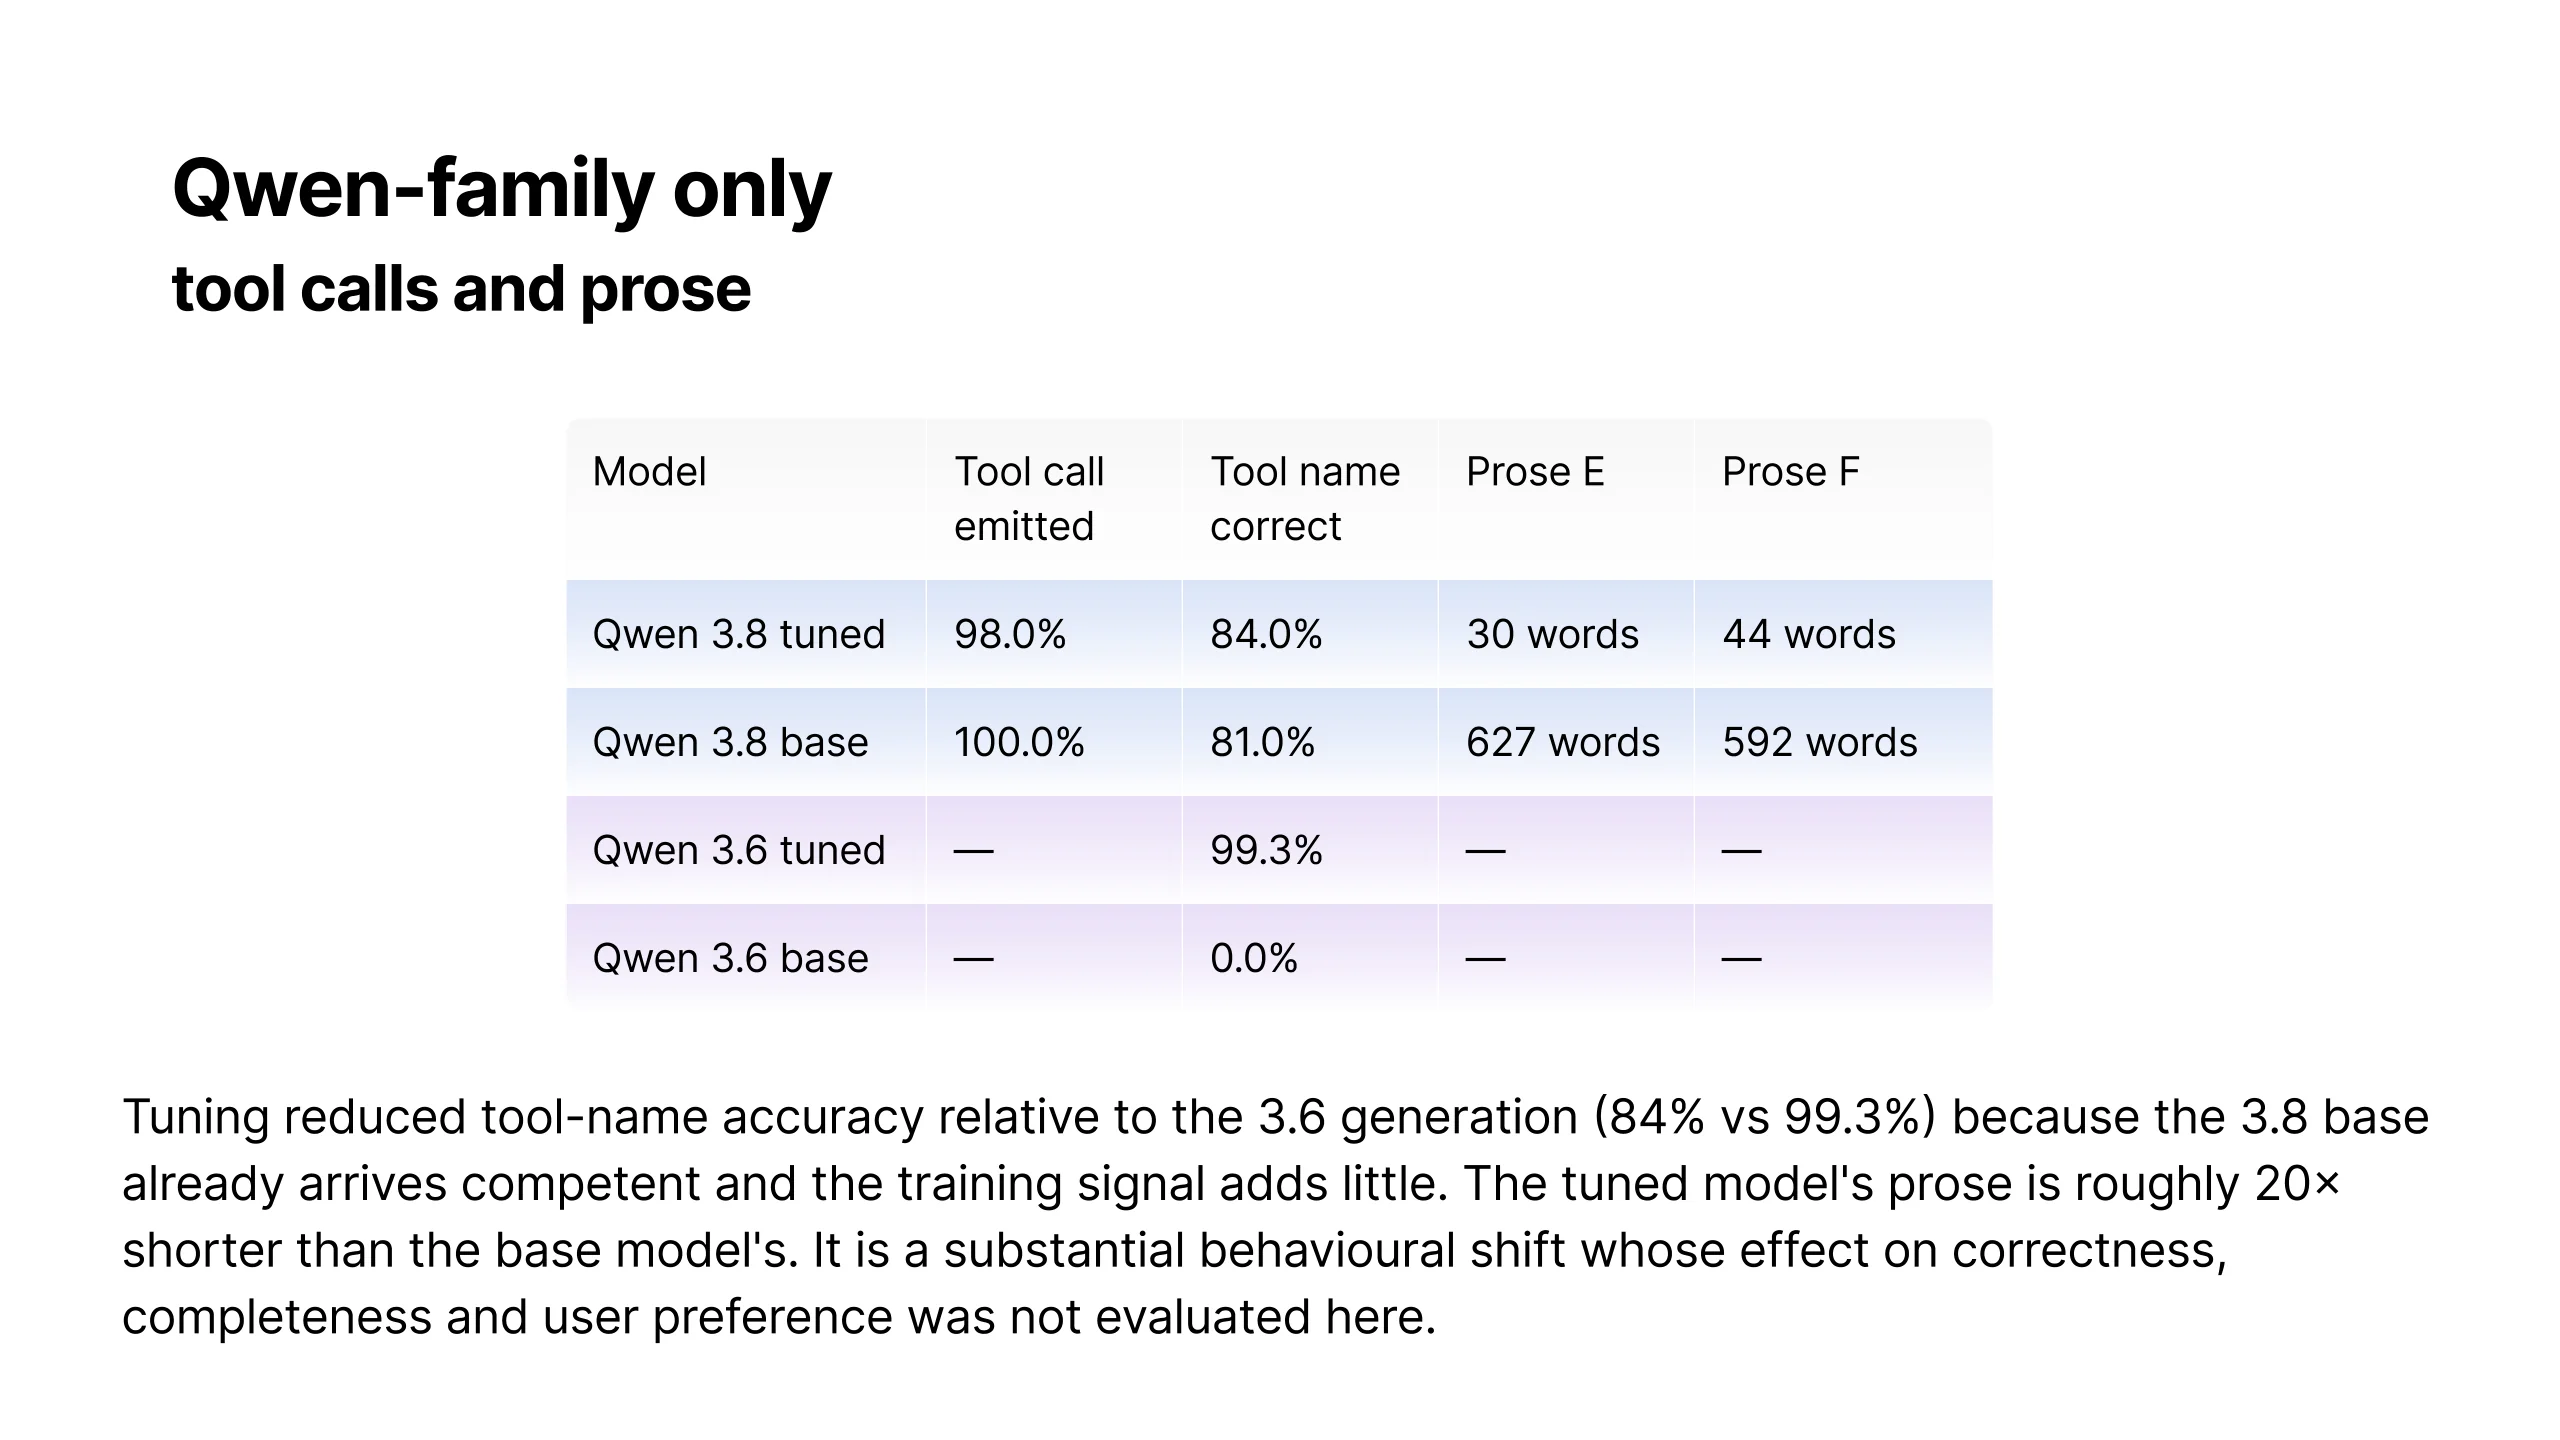
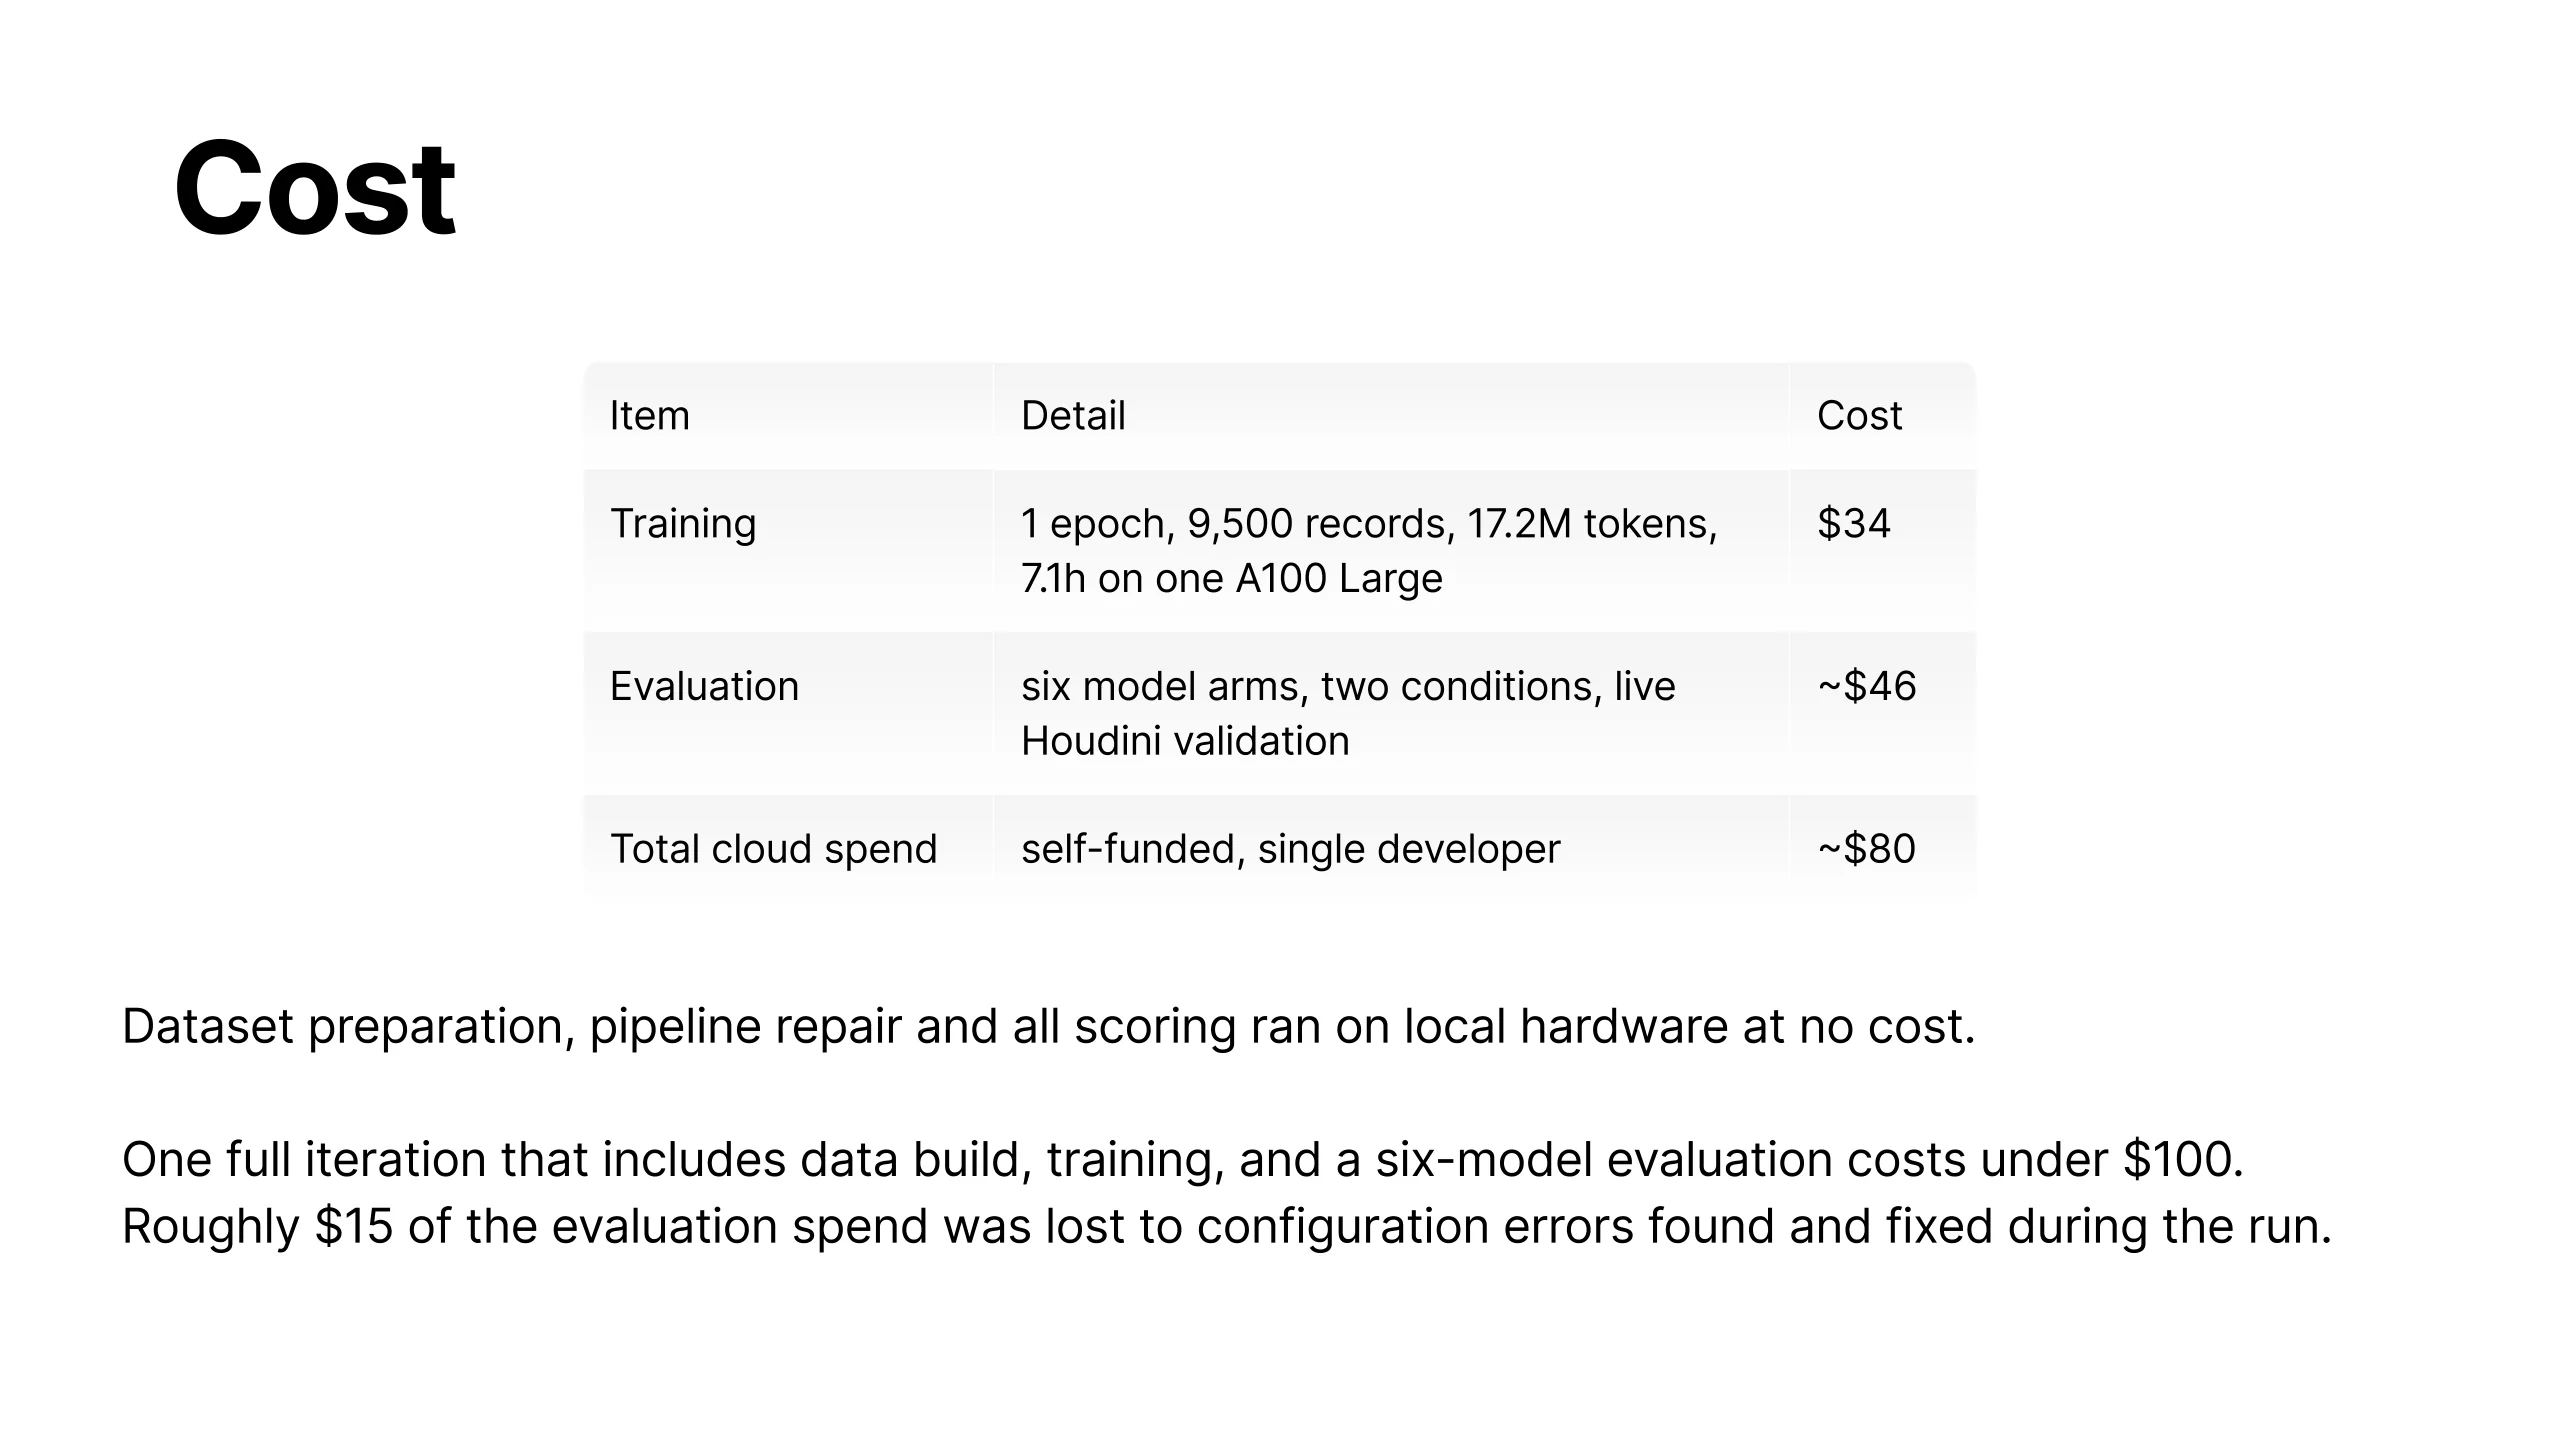
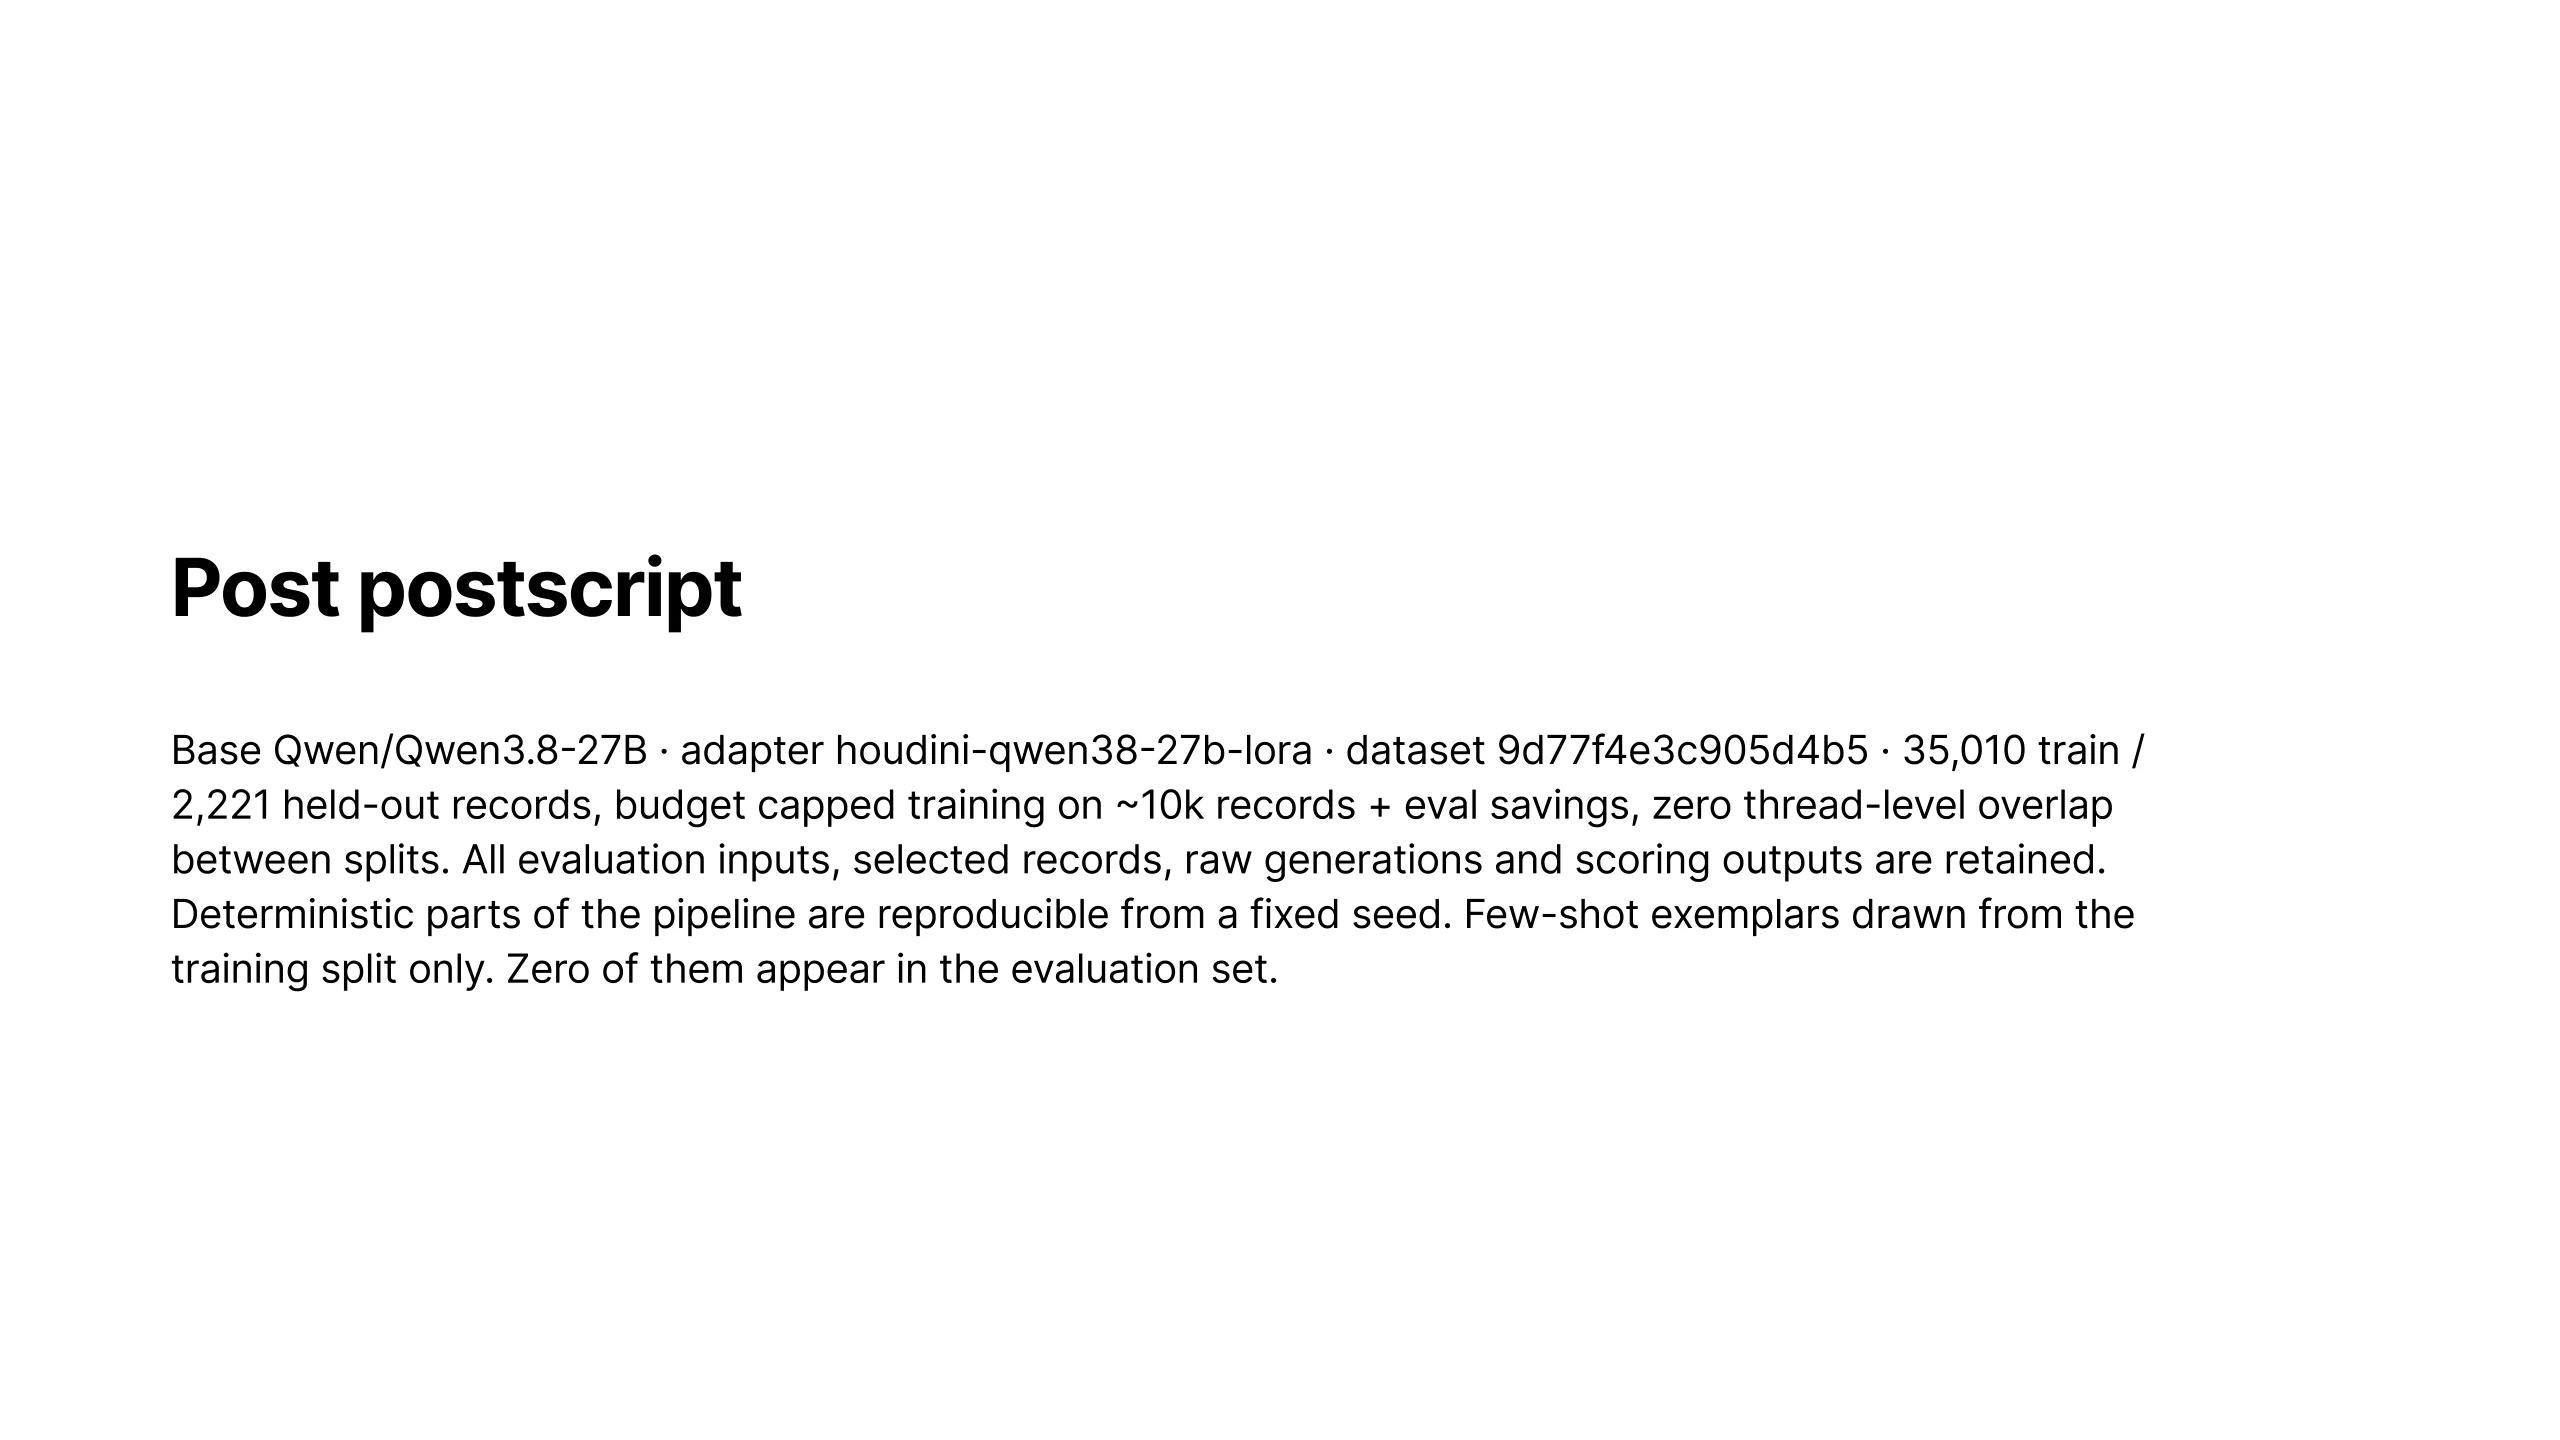
The production model is Qwen3.8-27B, an open-weight model, adapted with QLoRA: instead of retraining all 27 billion parameters, a small set of adapter weights is trained on top of a compressed copy of the model. One pass over 9,500 examples (17.2M tokens) took 7.1 hours on a single A100 GPU and cost $34. Compressed to 4-bit, the finished model fits on one workstation GPU.
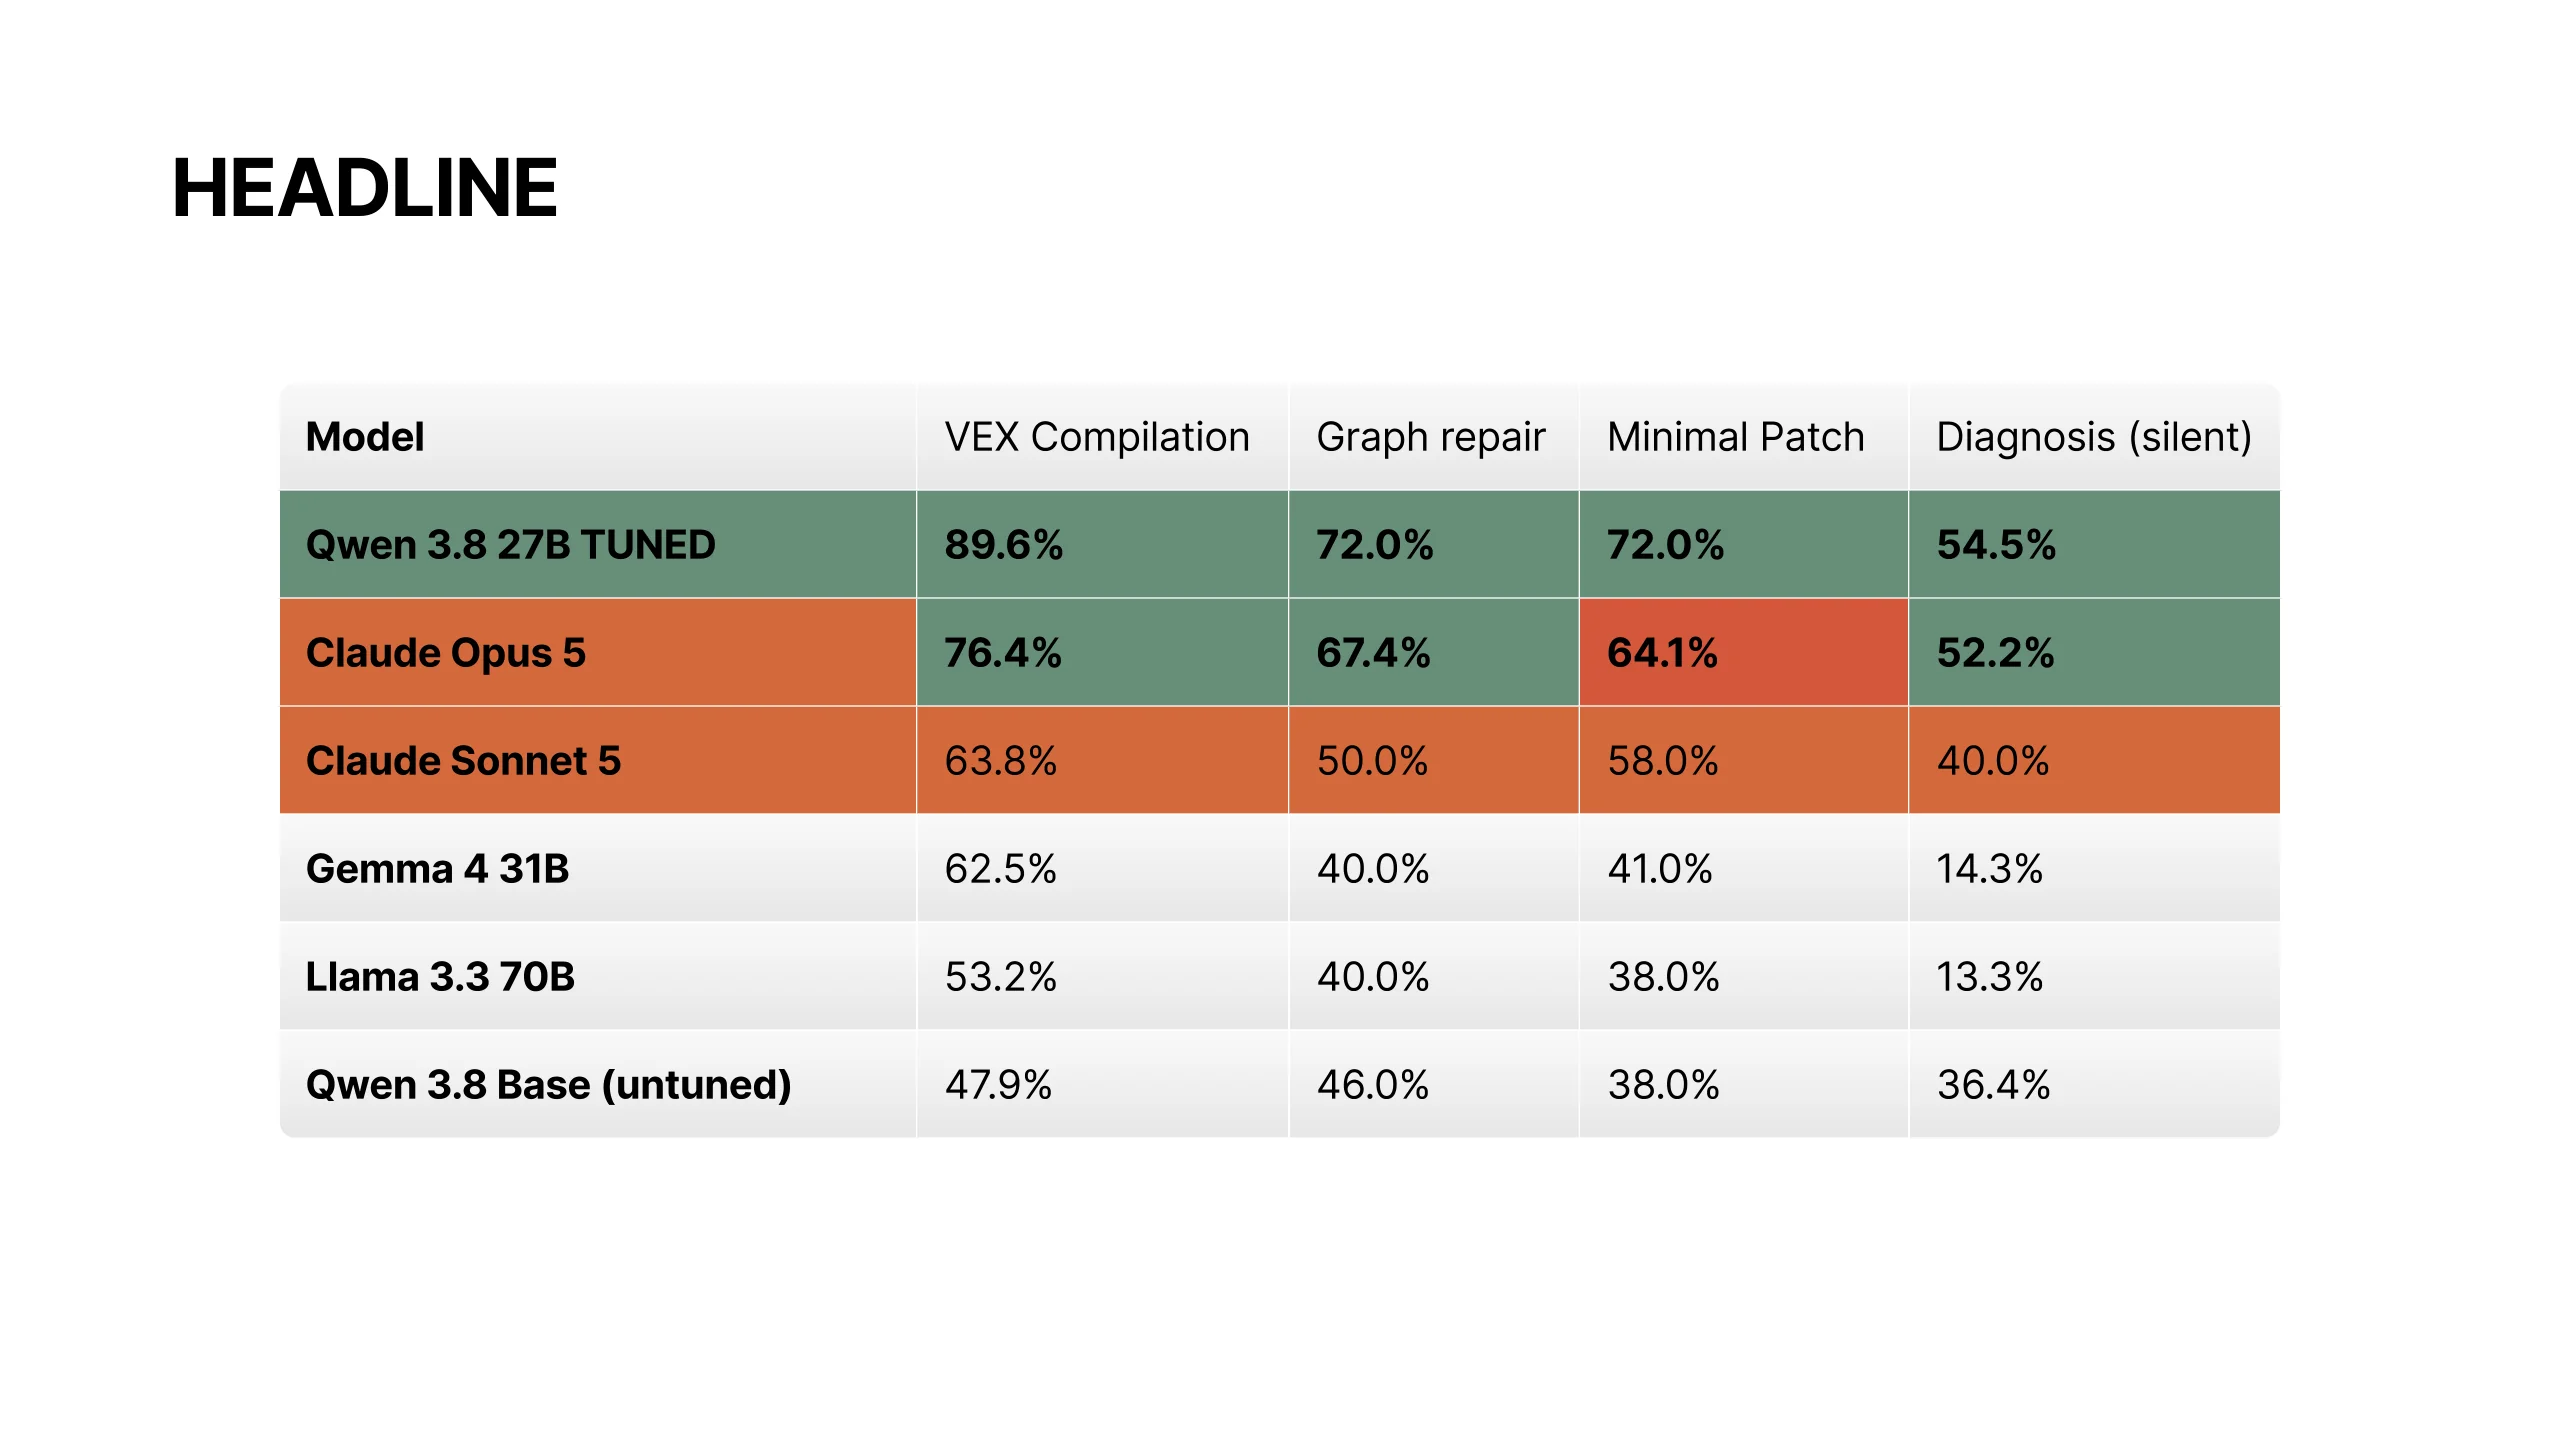
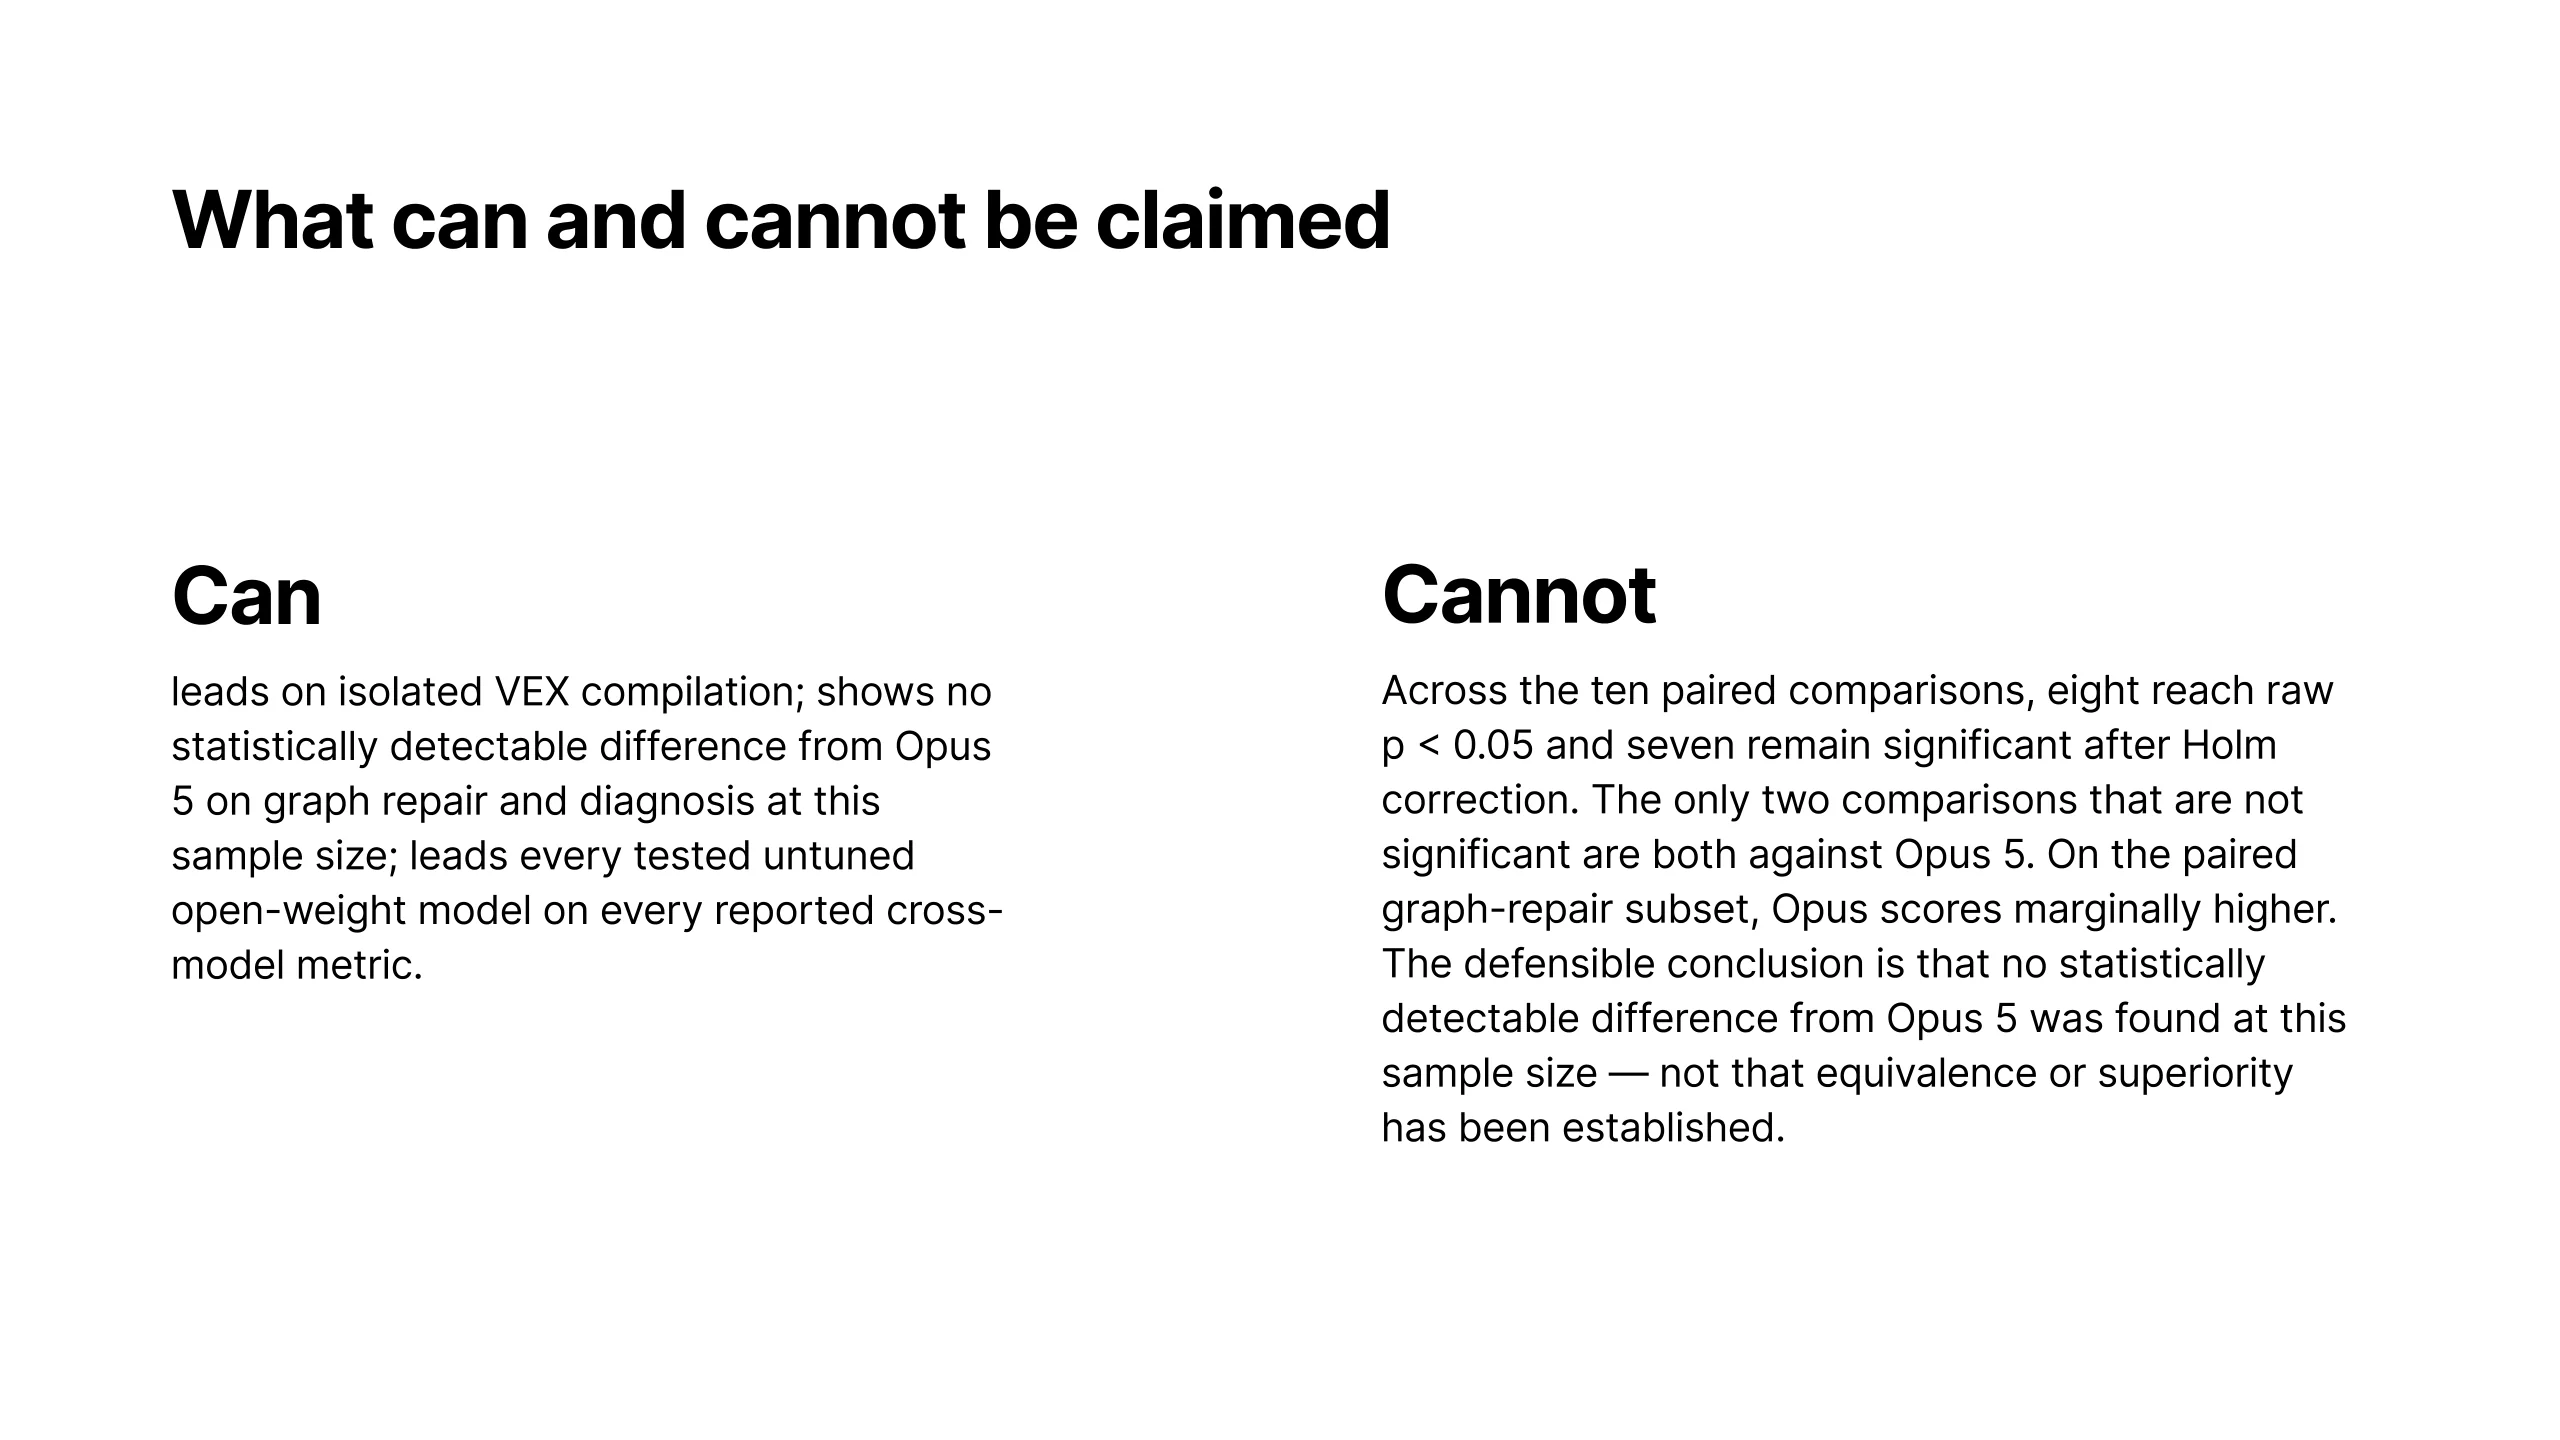
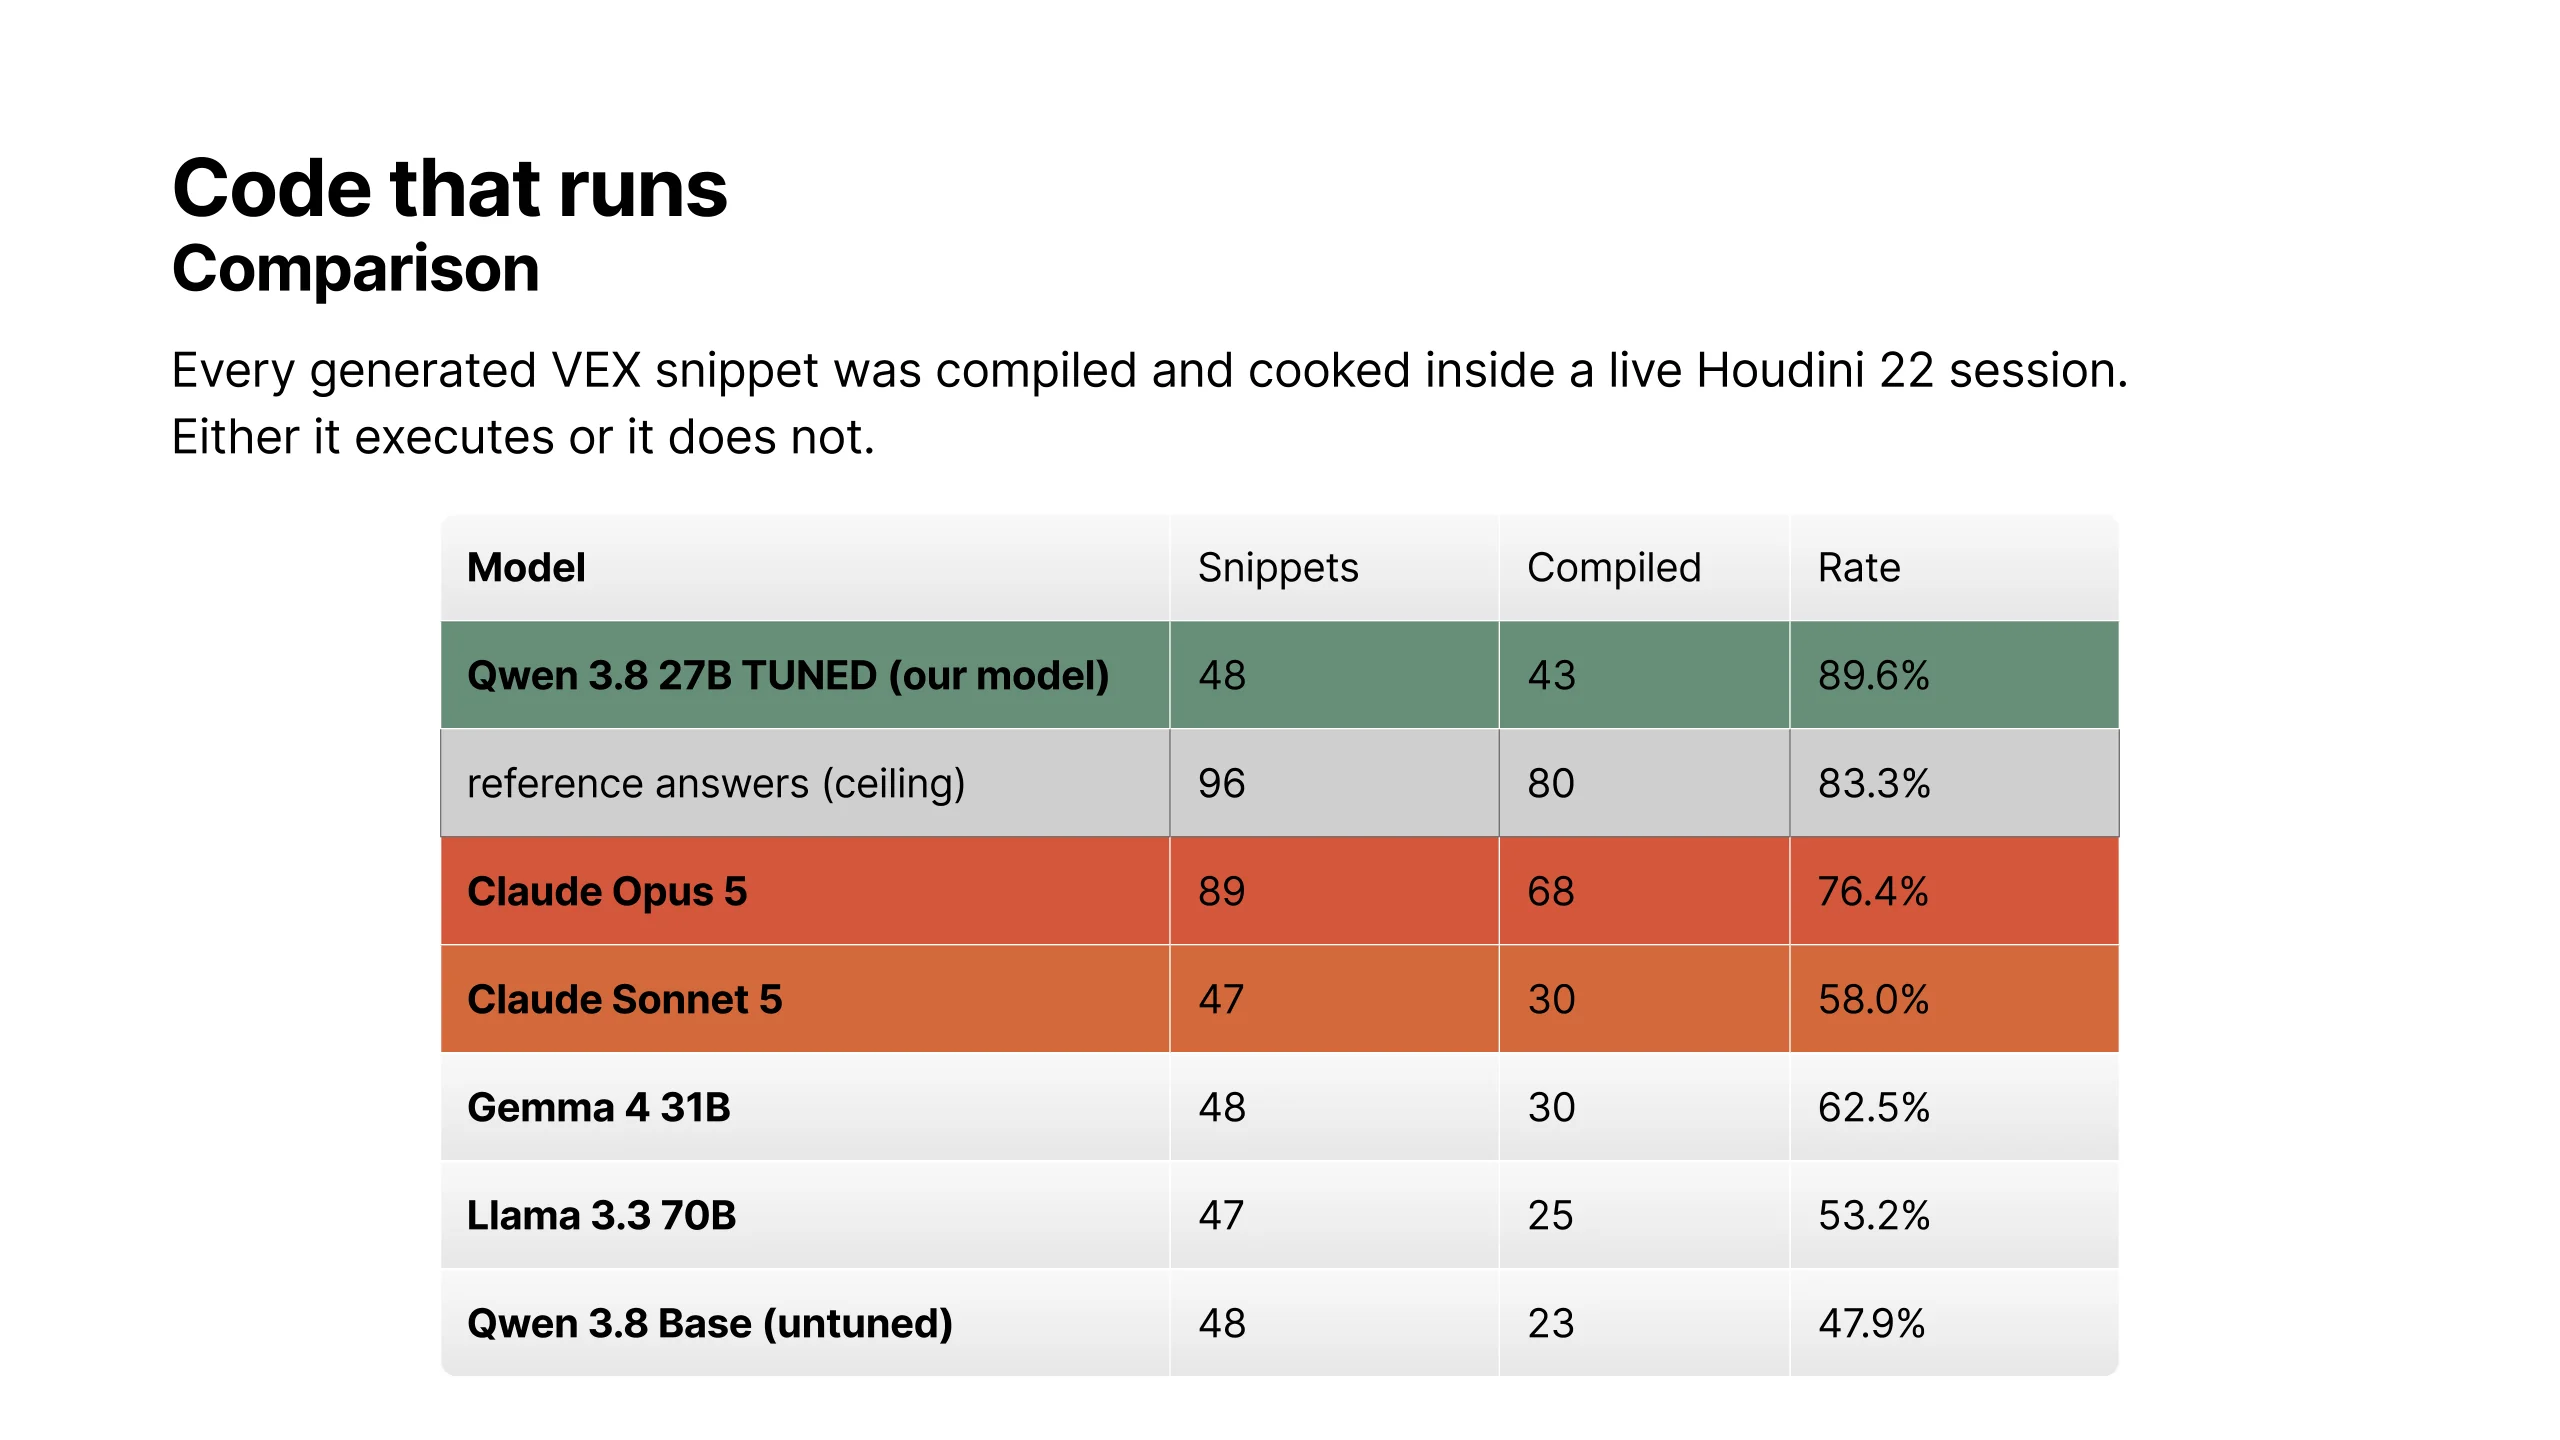
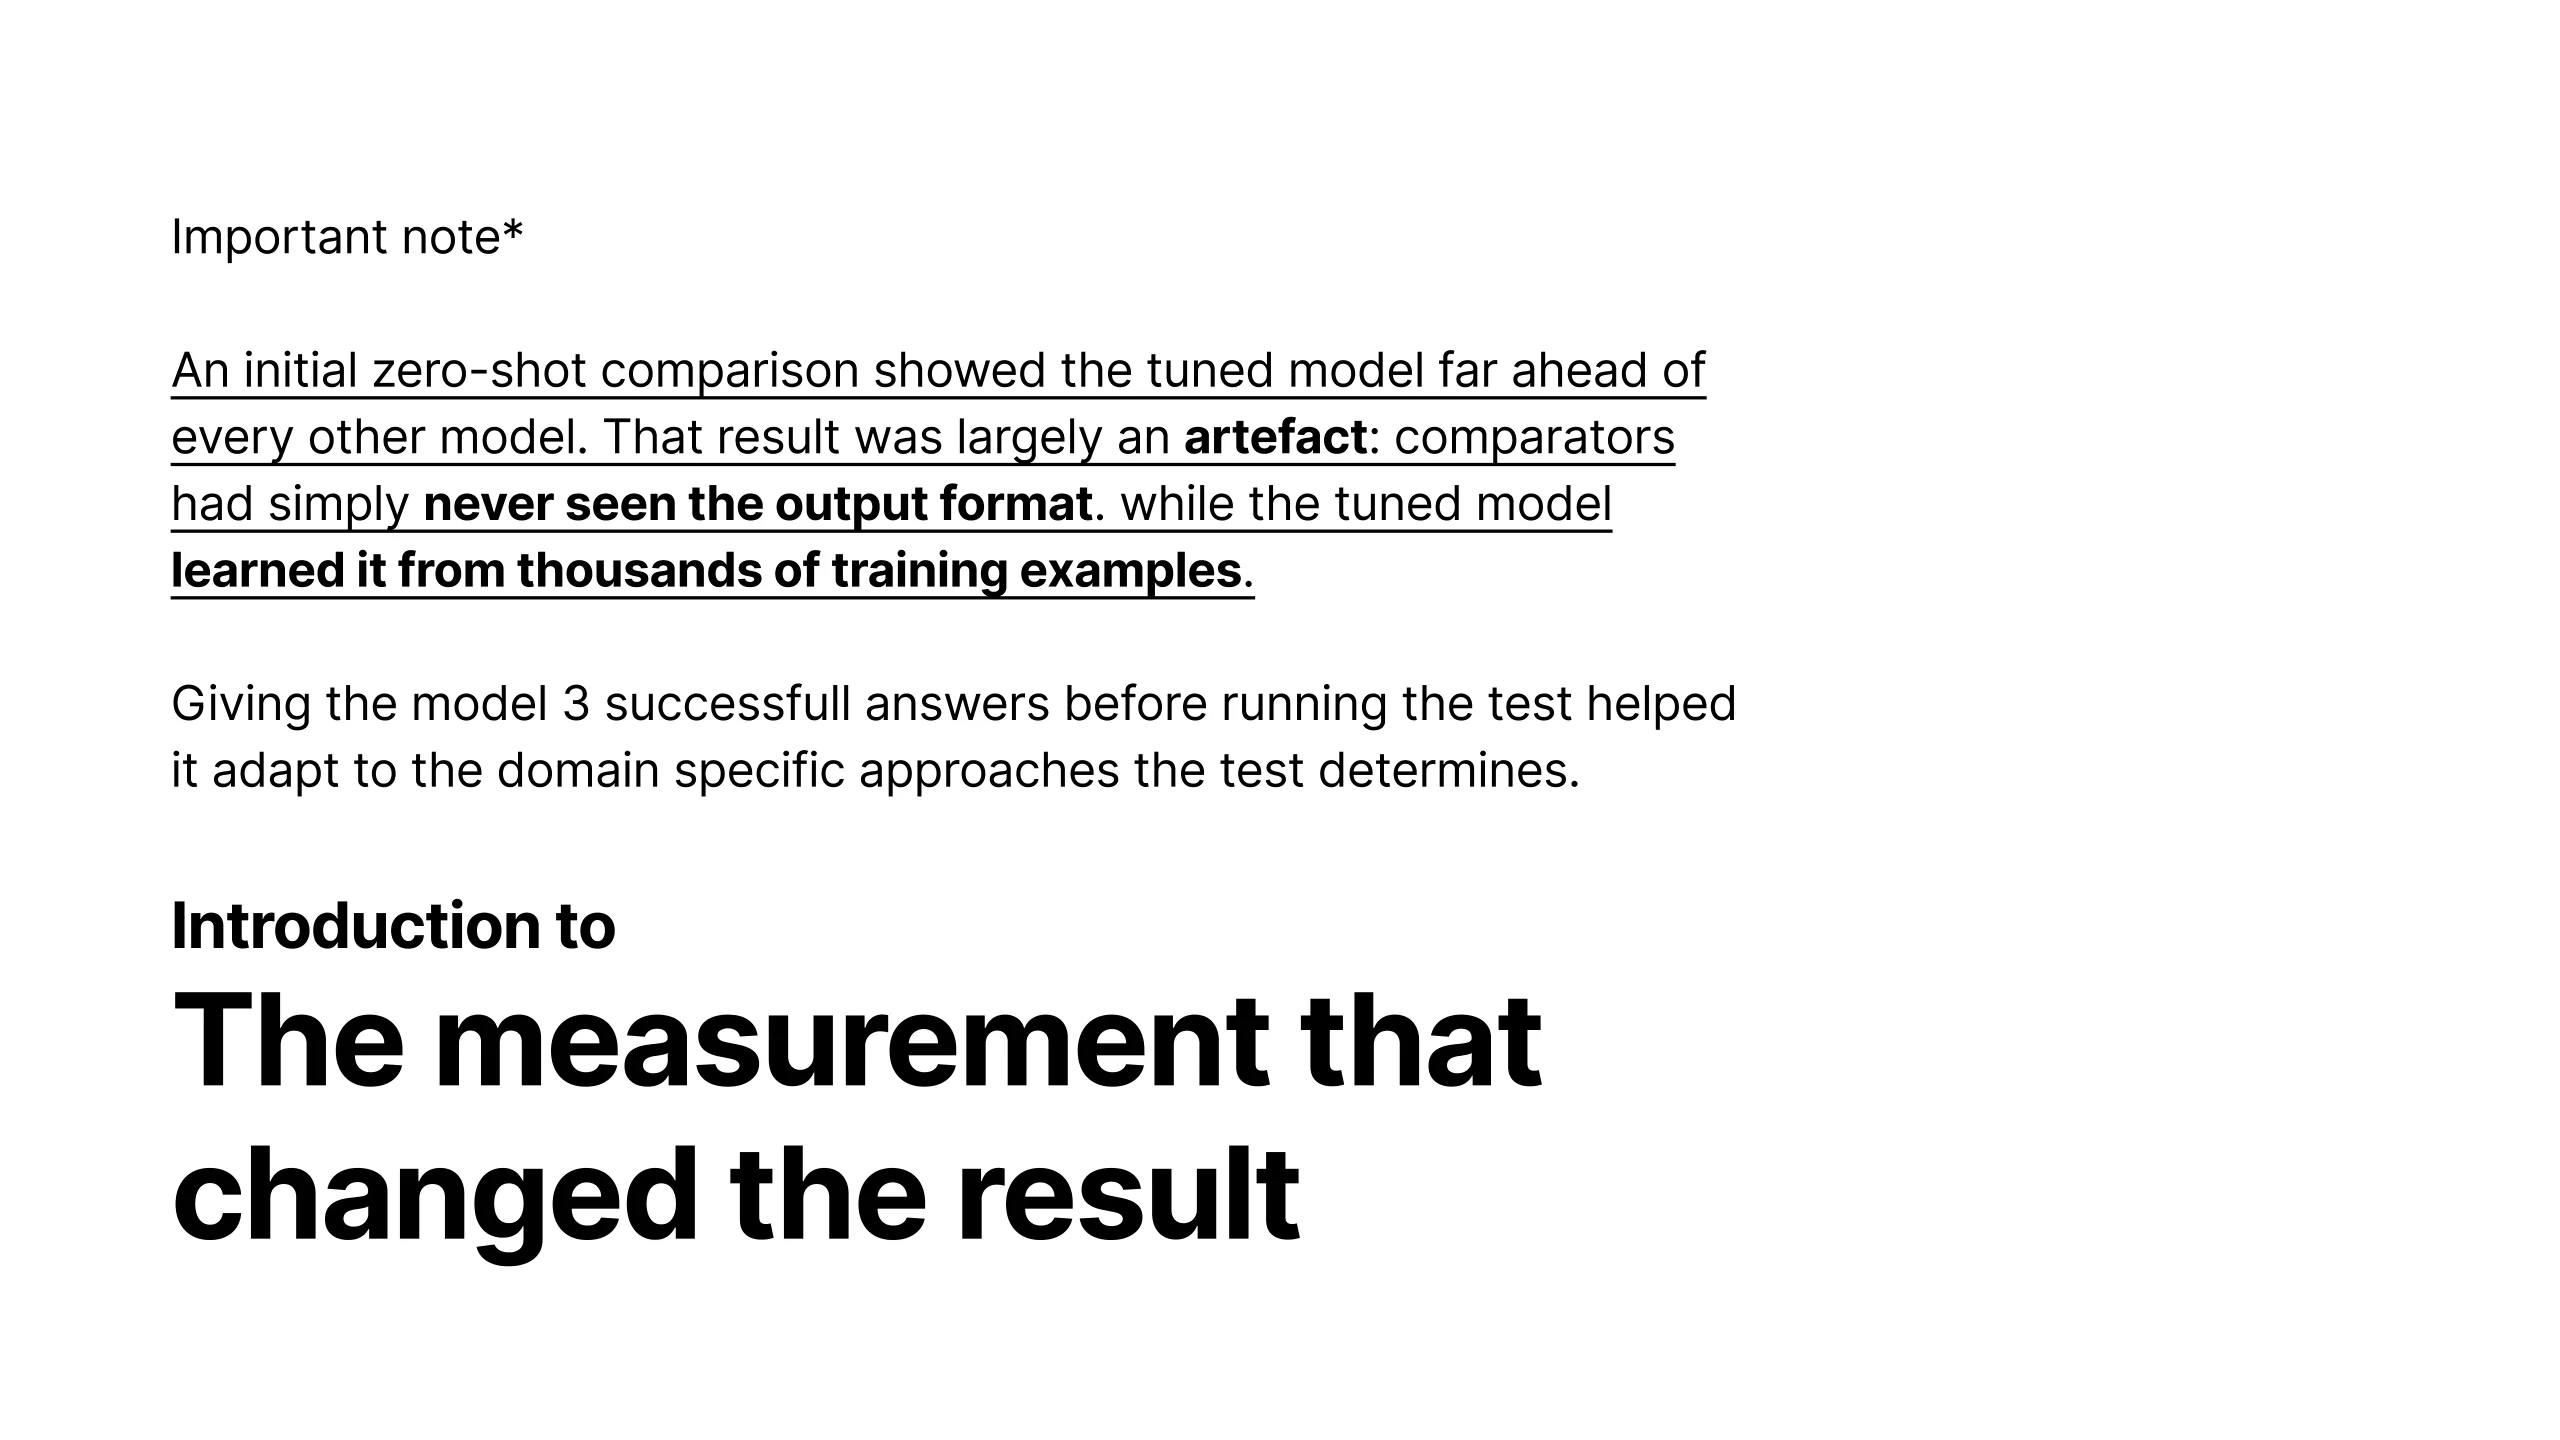
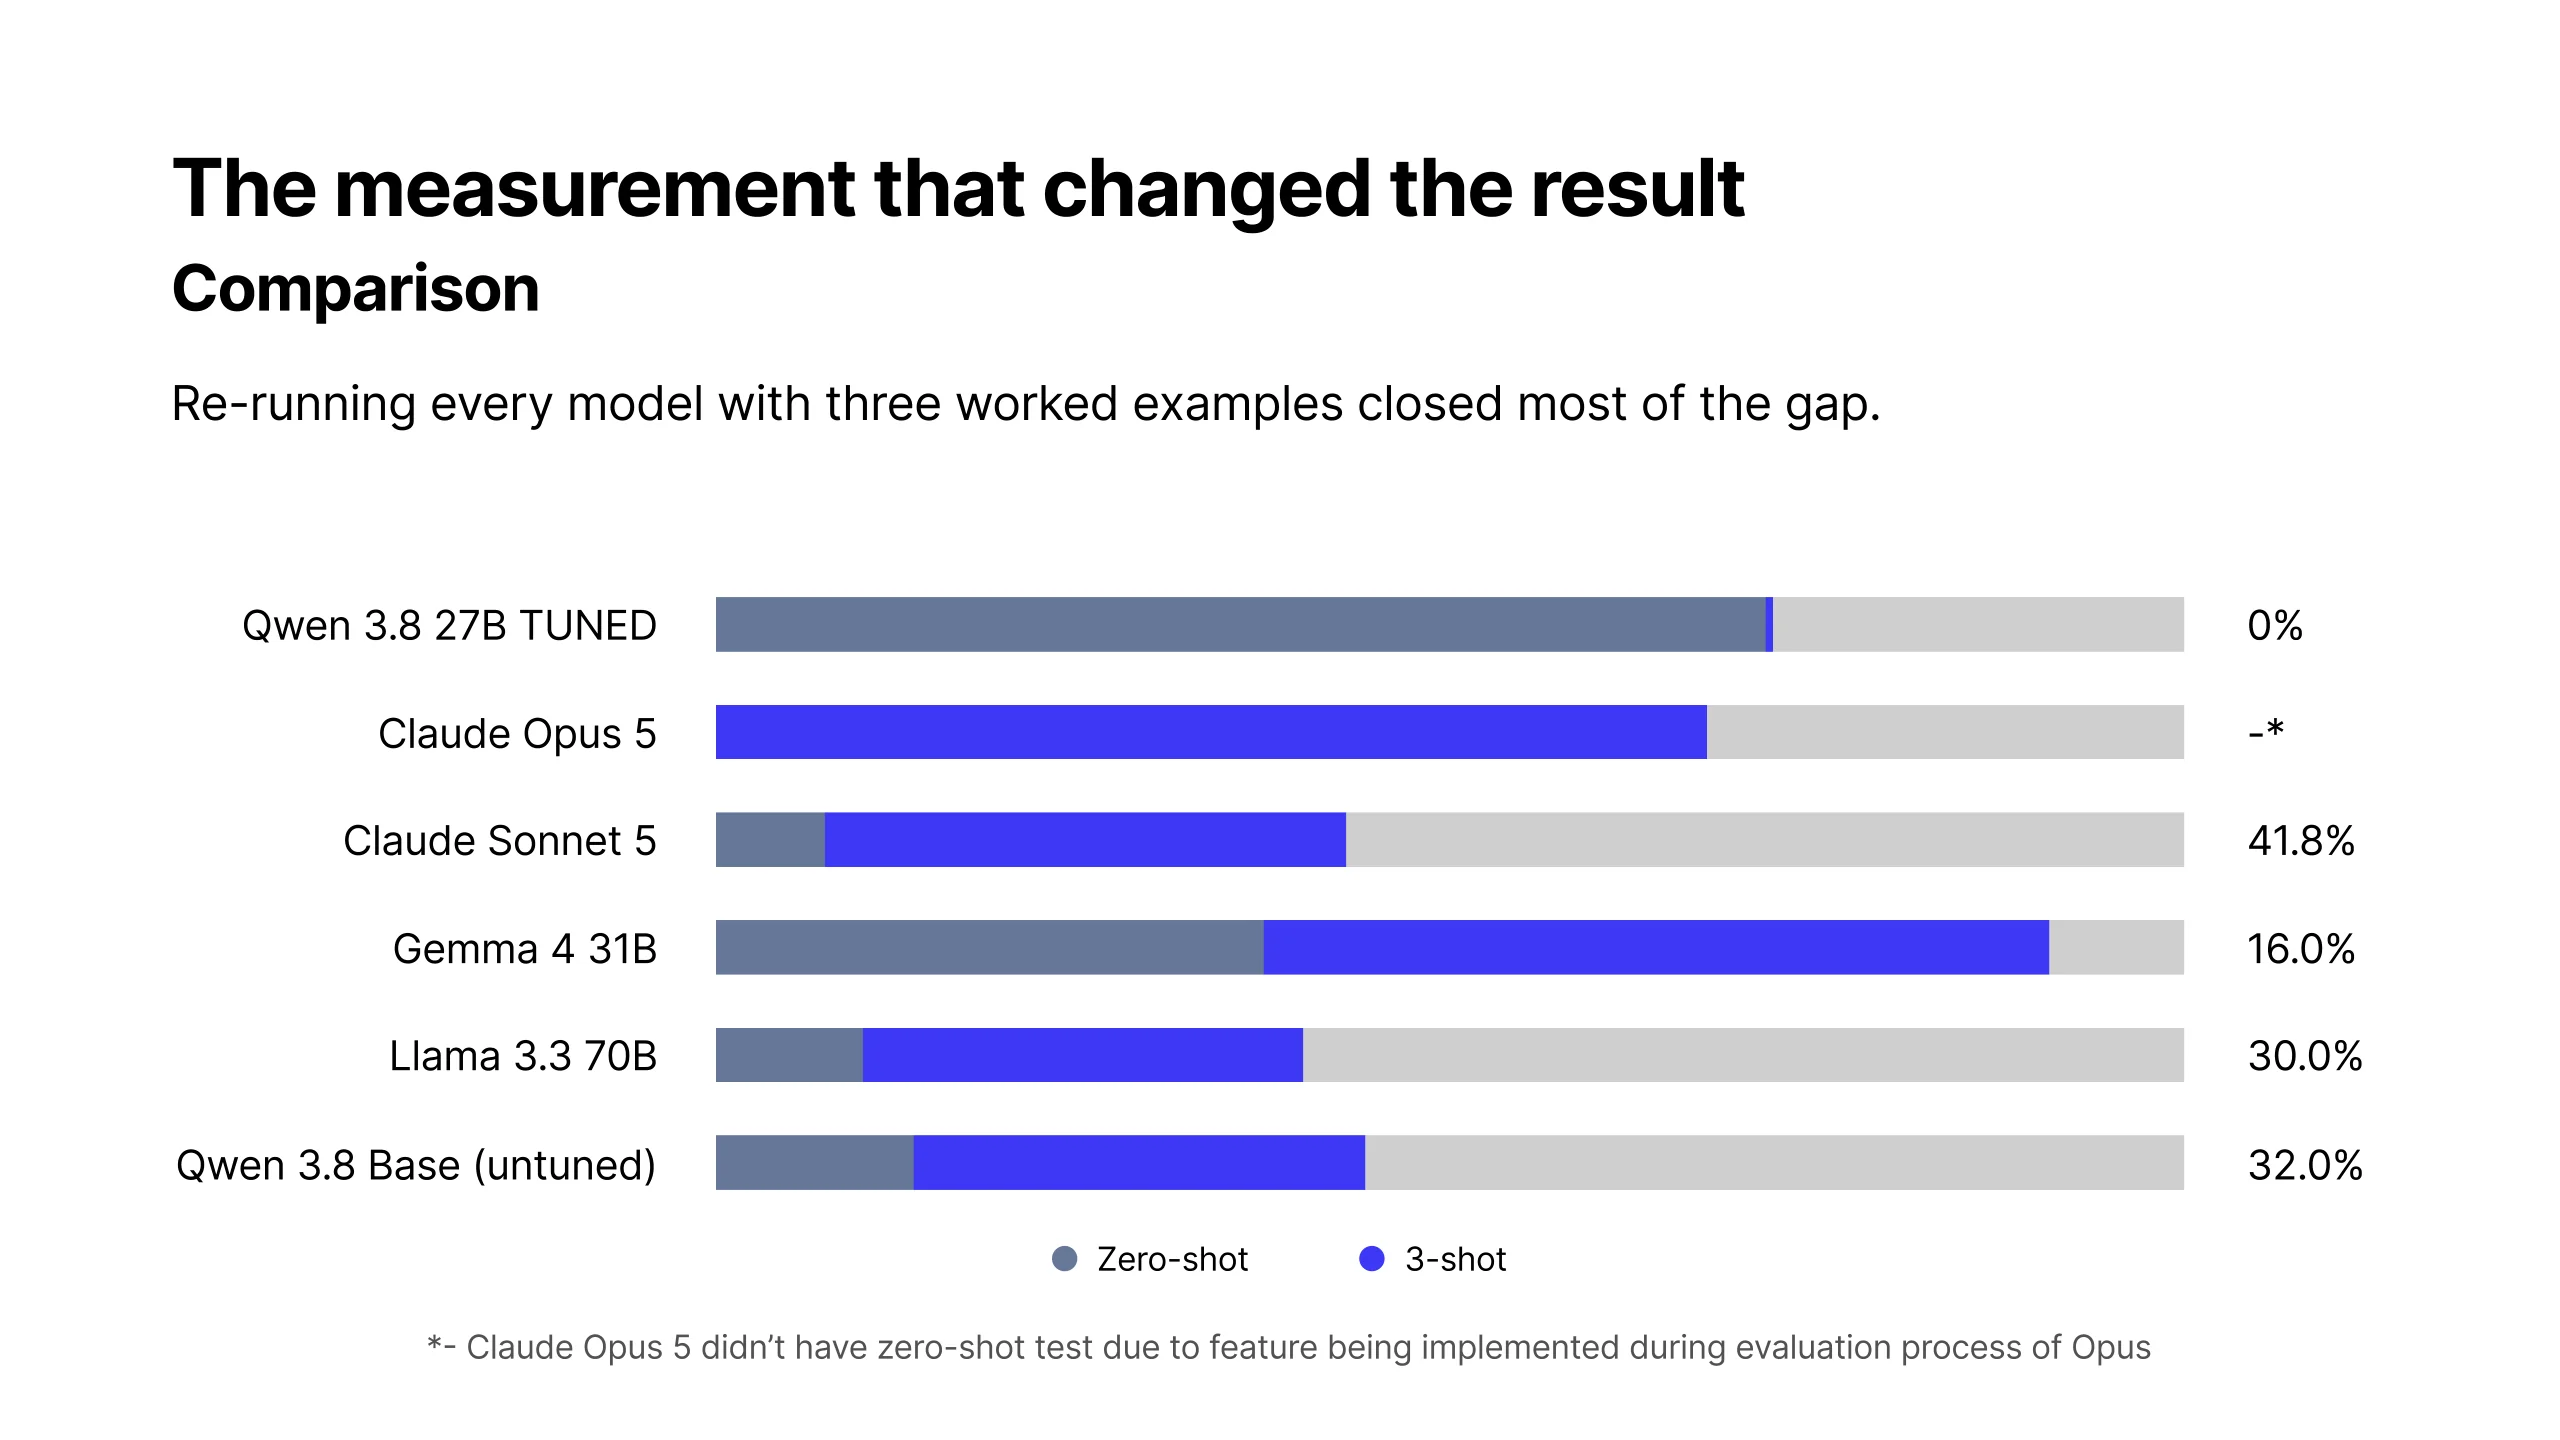
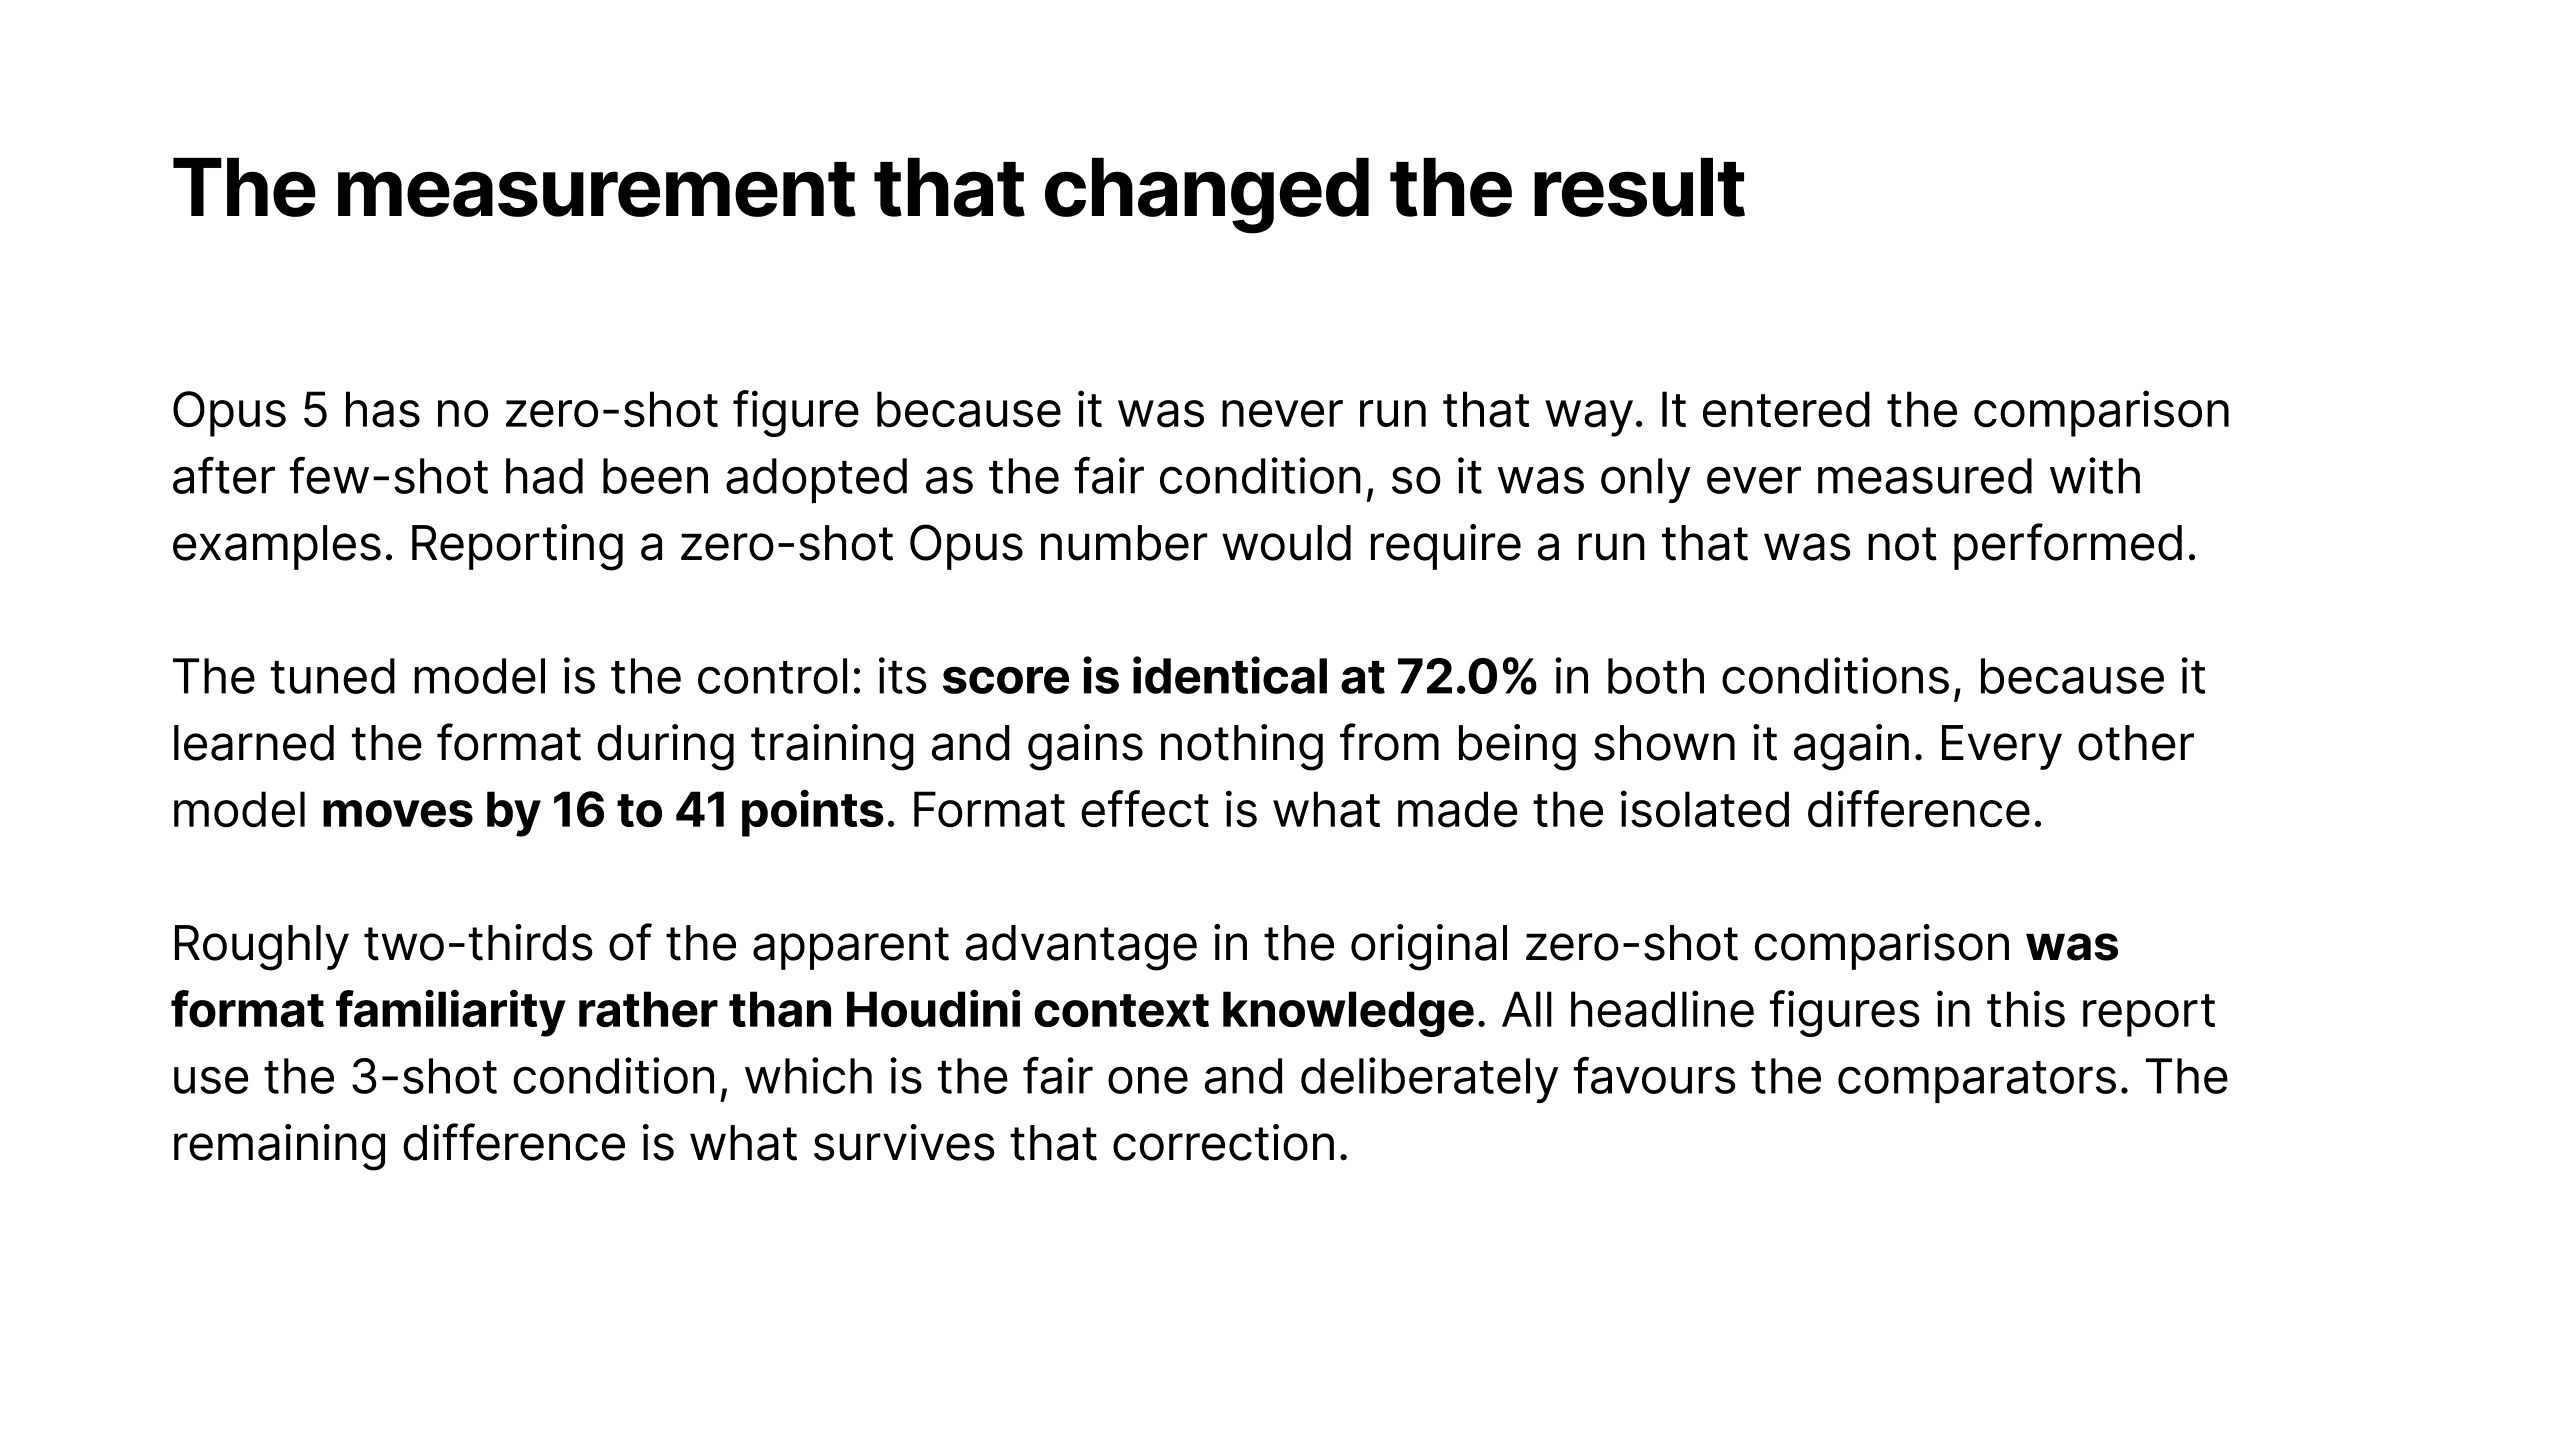
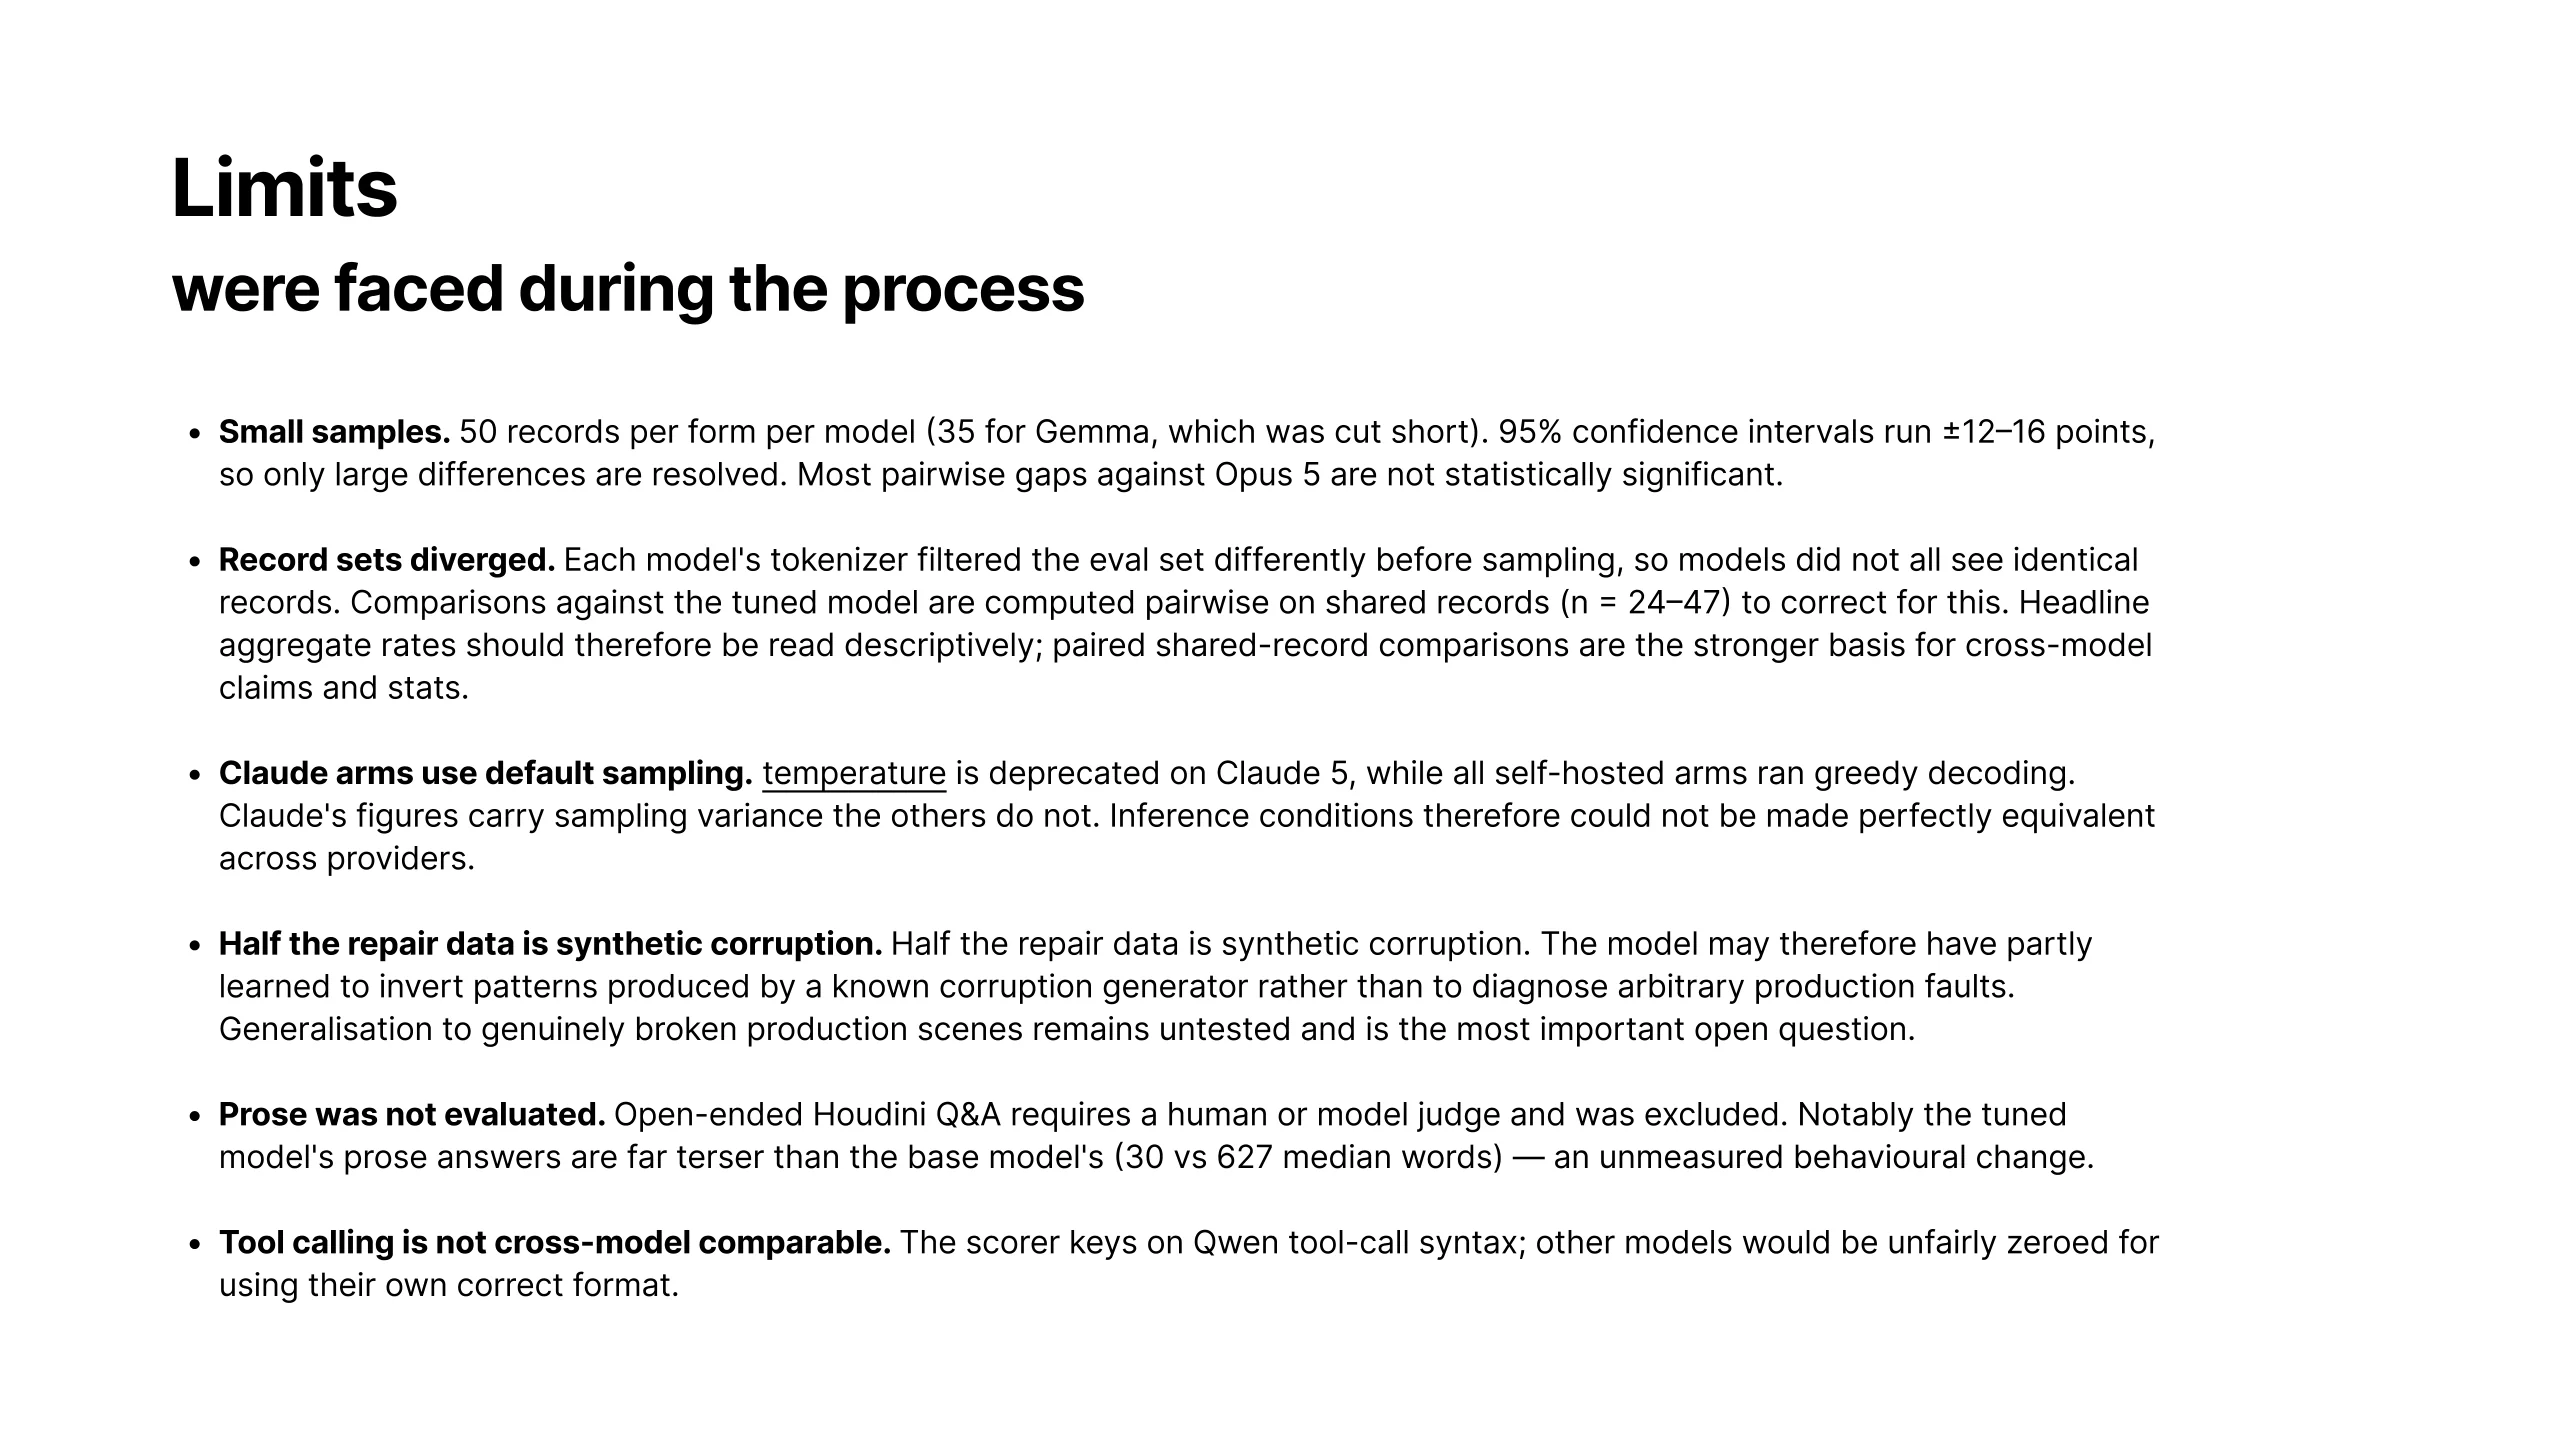
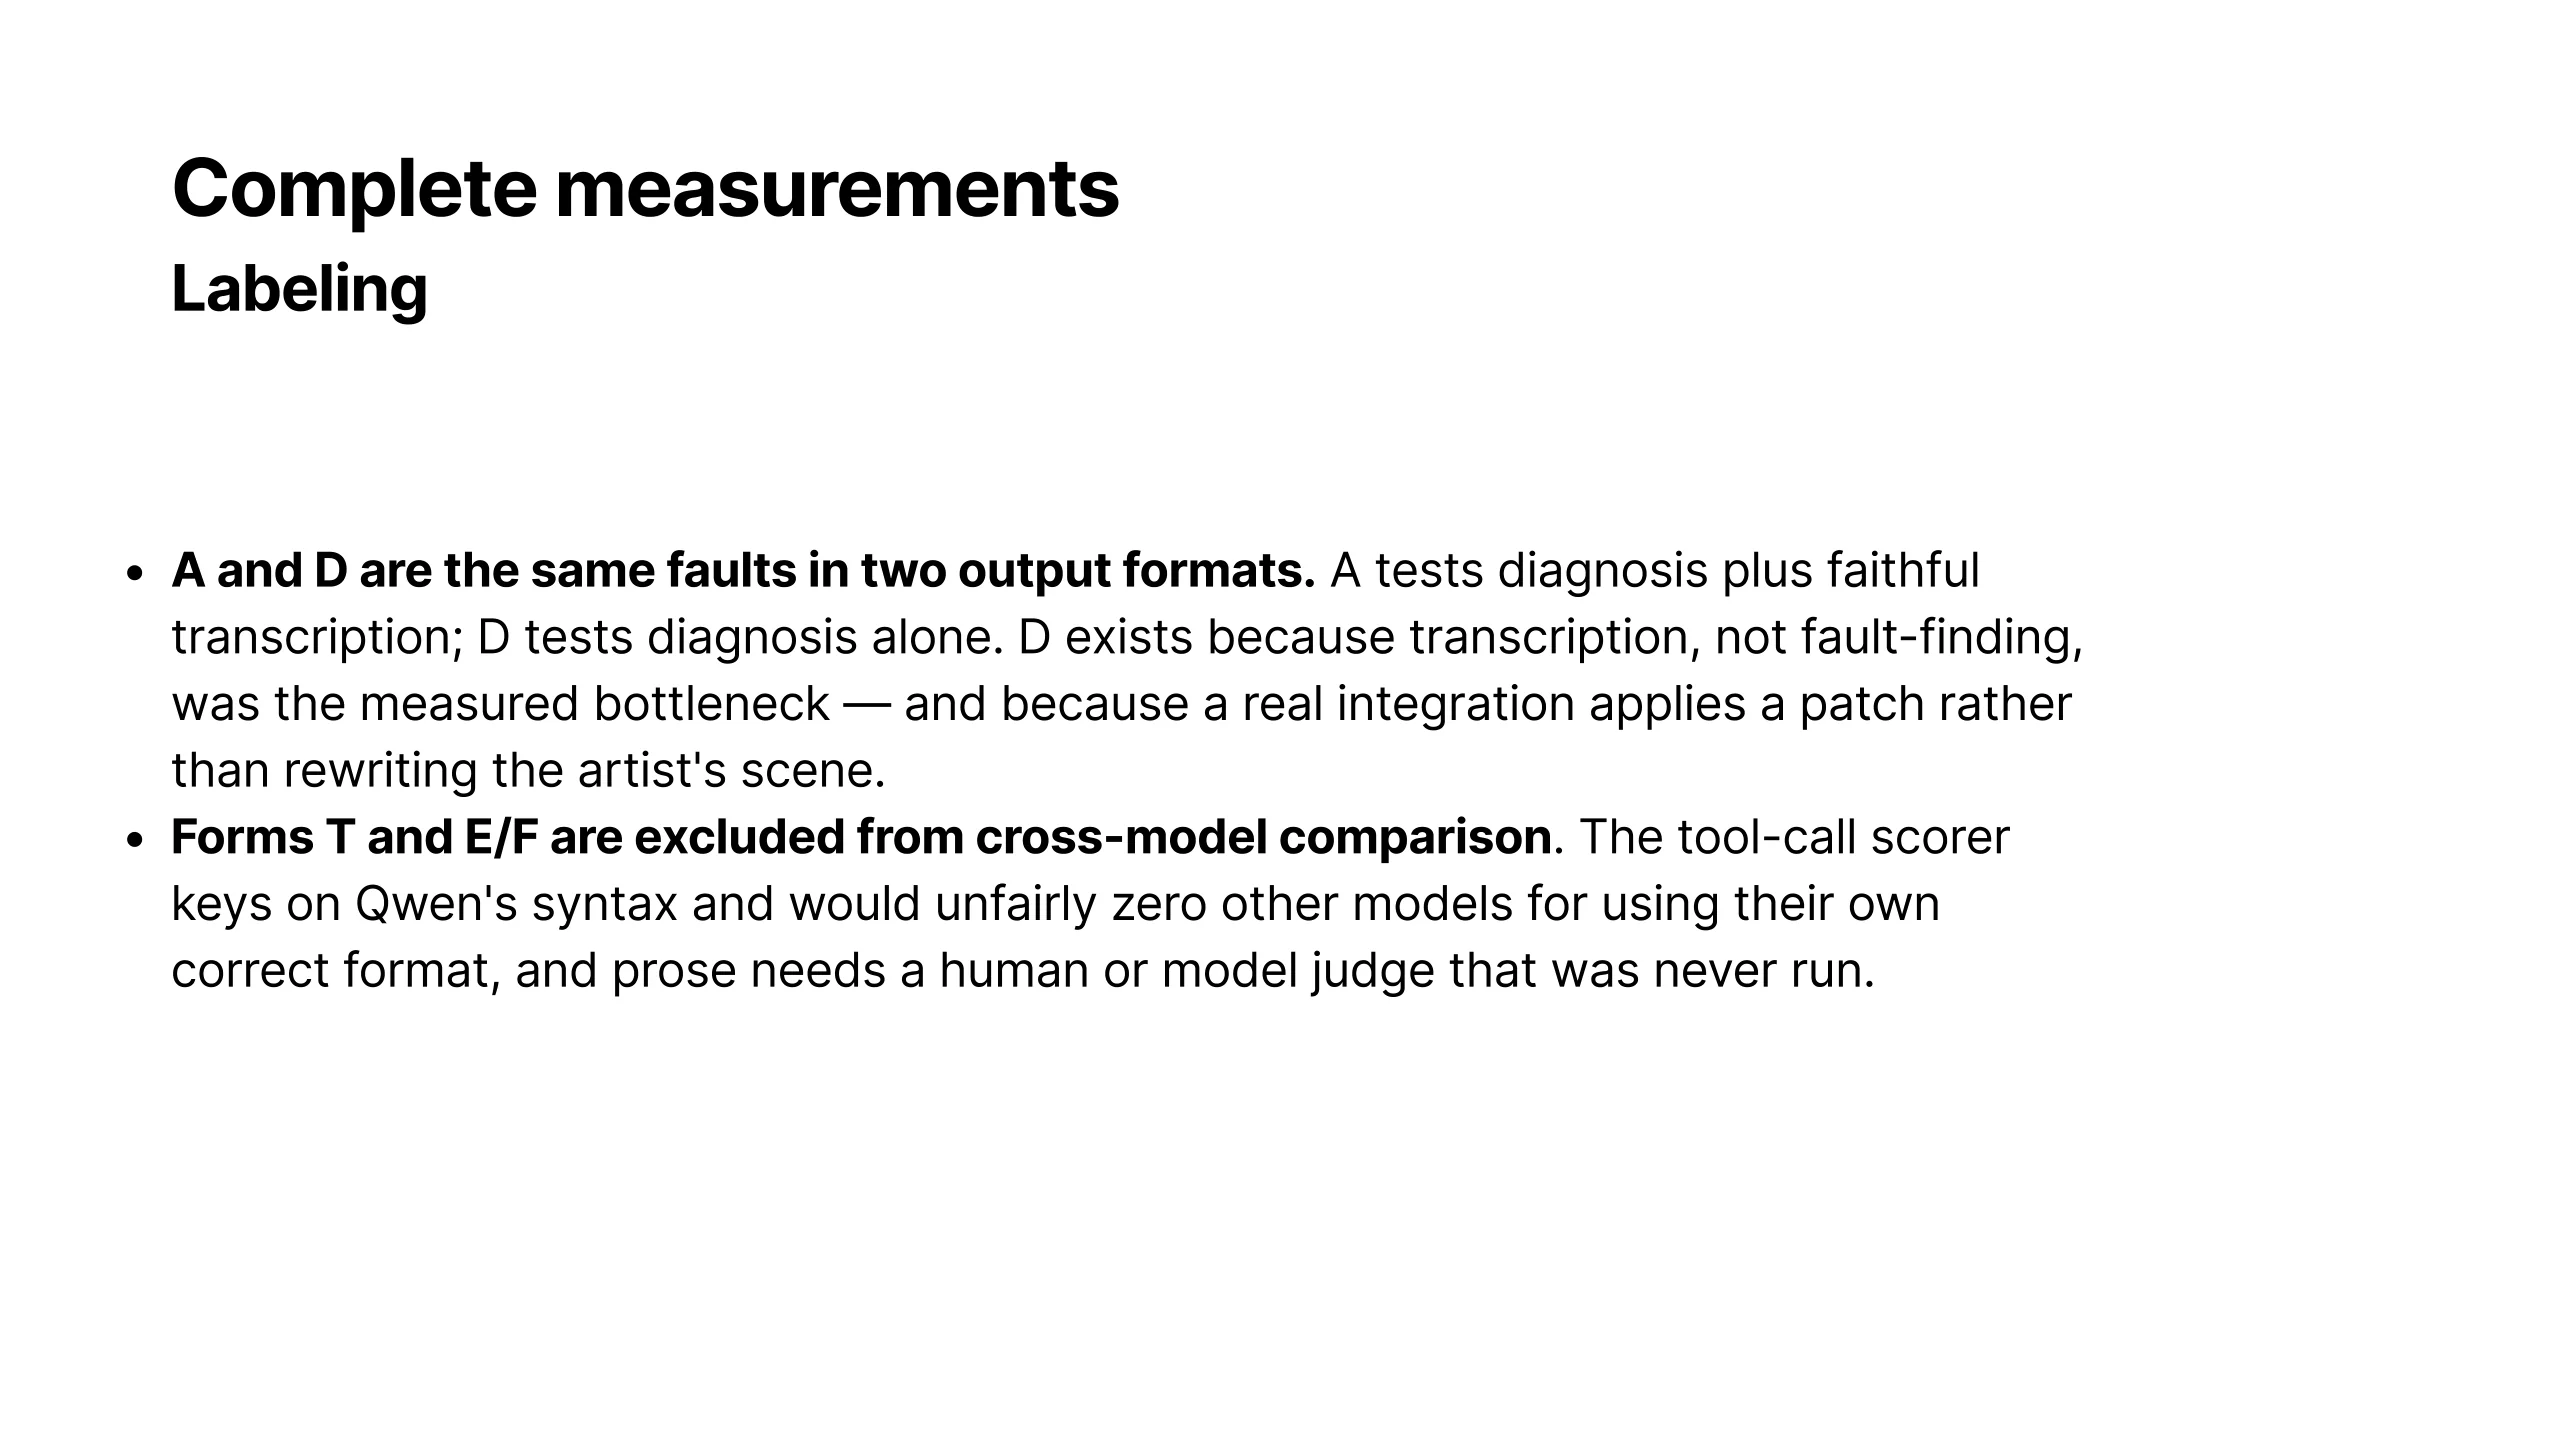
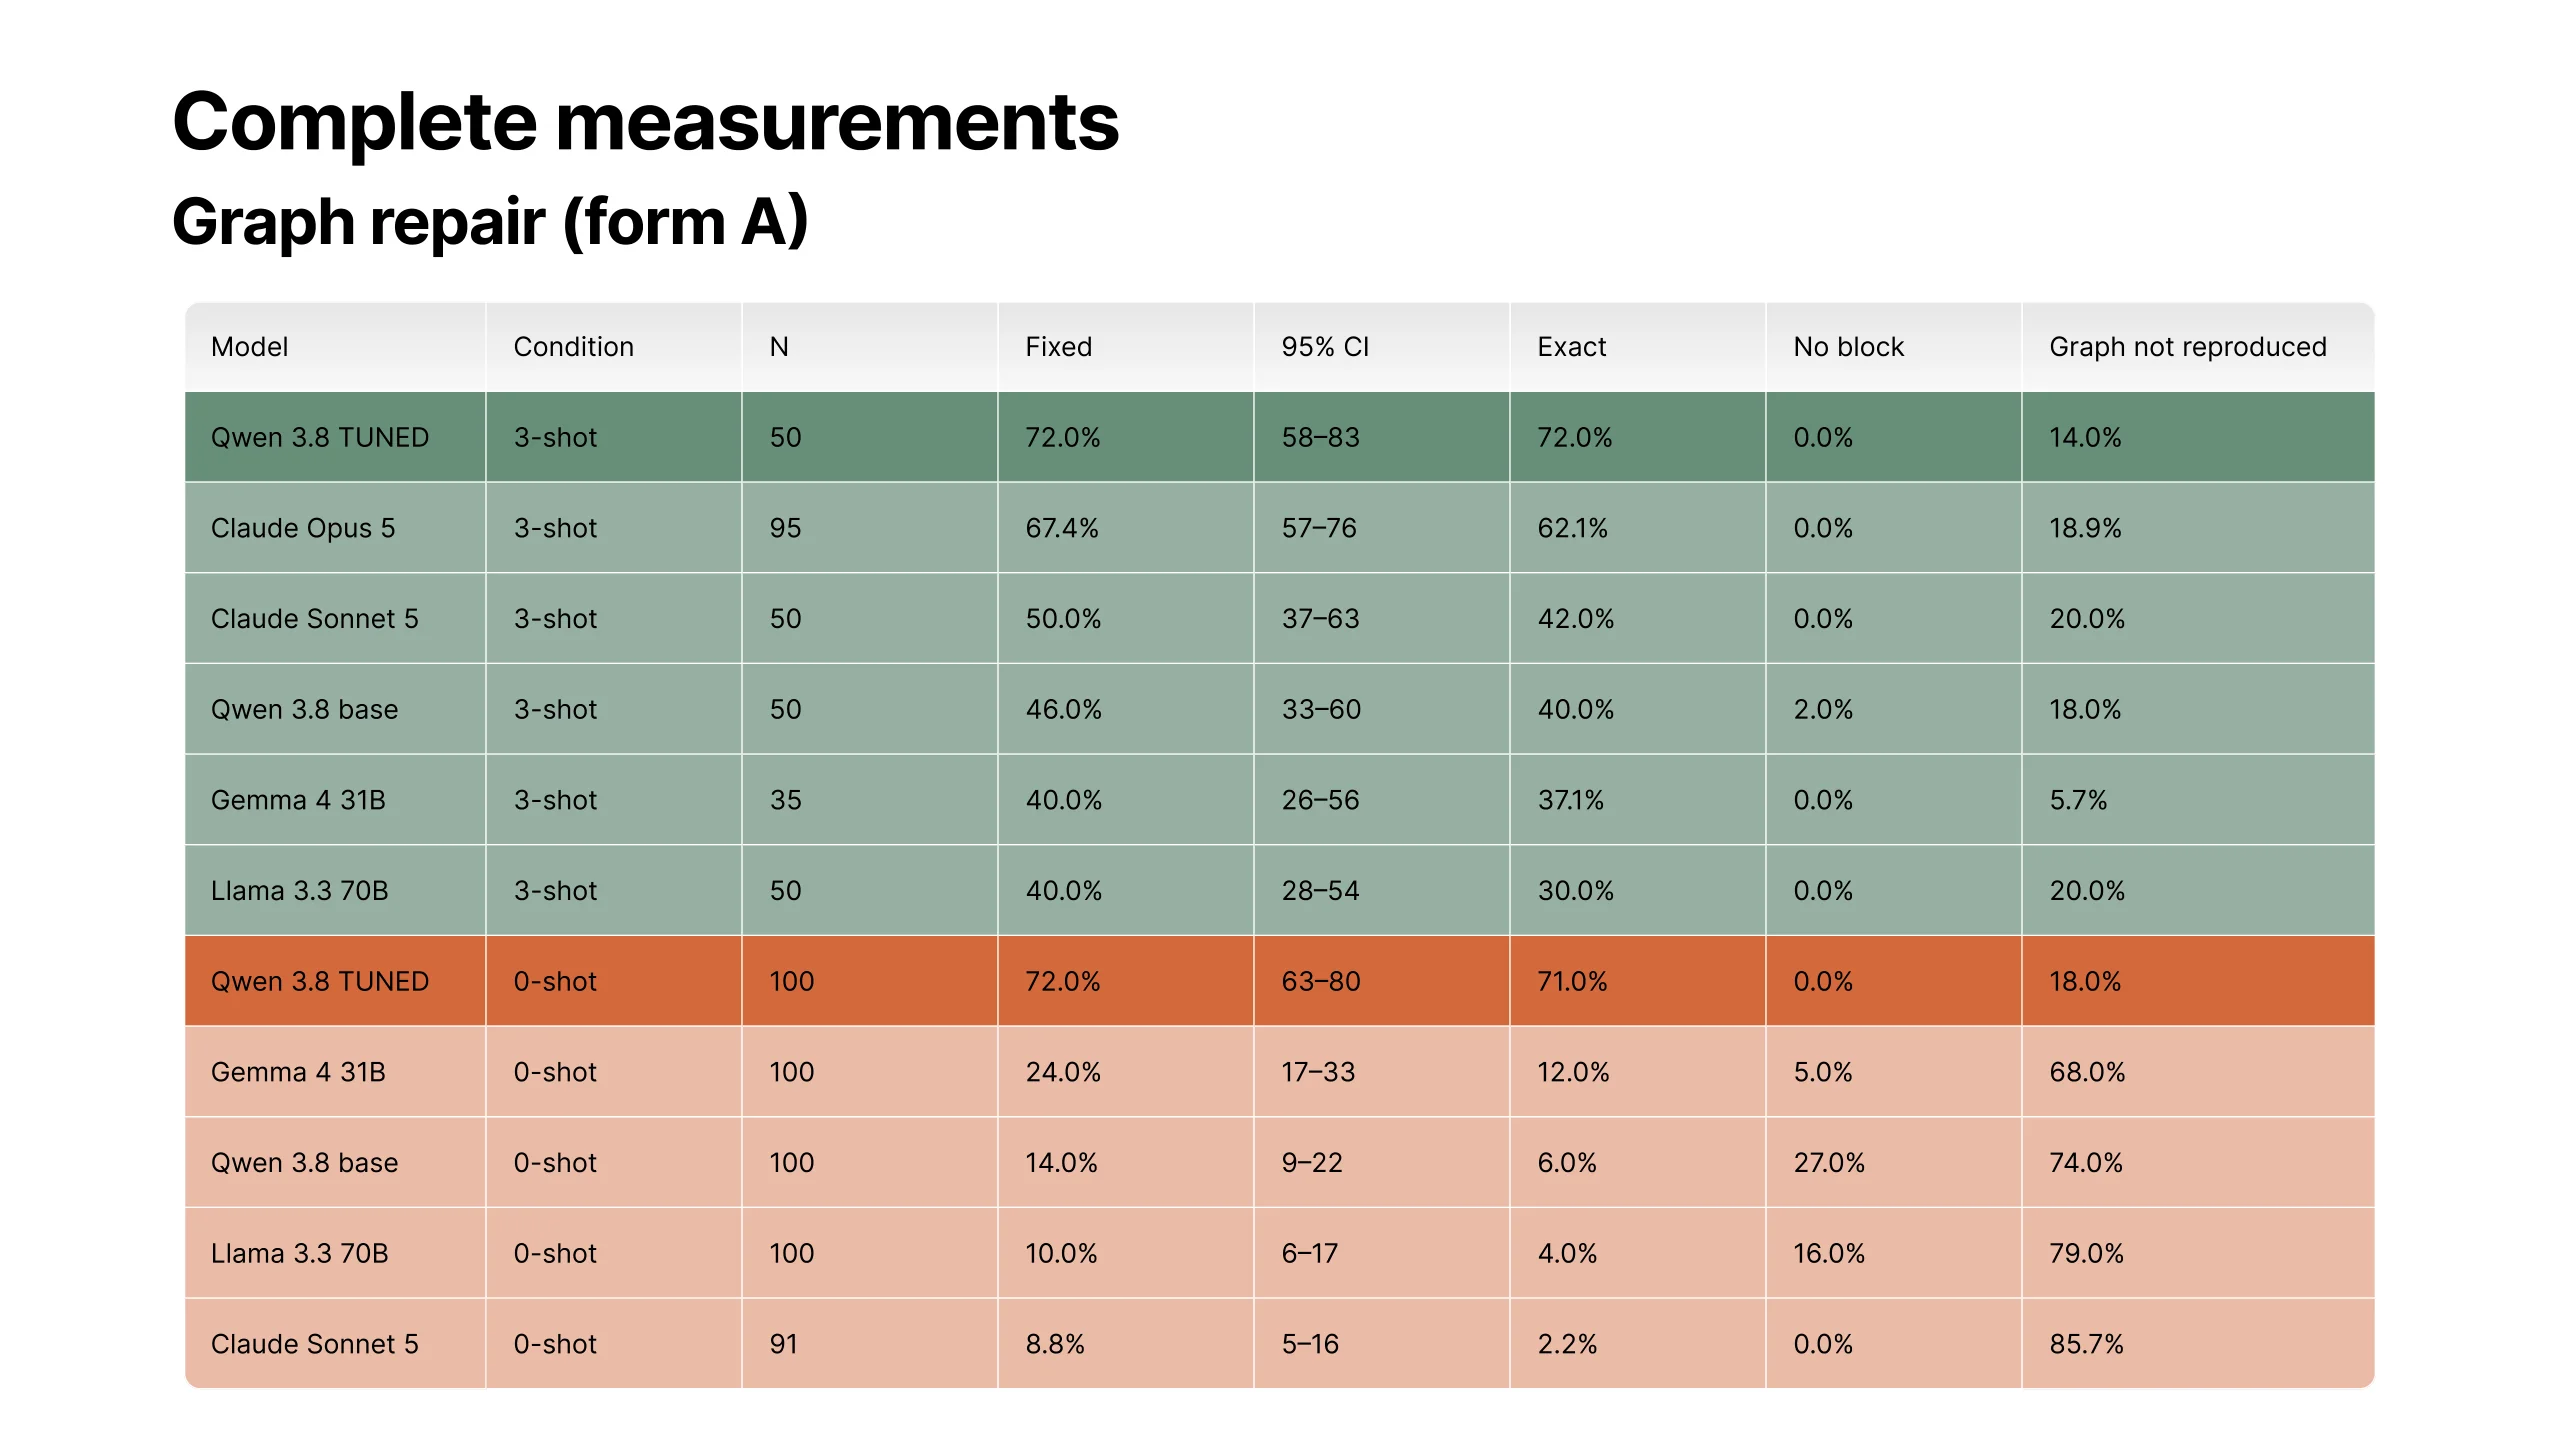
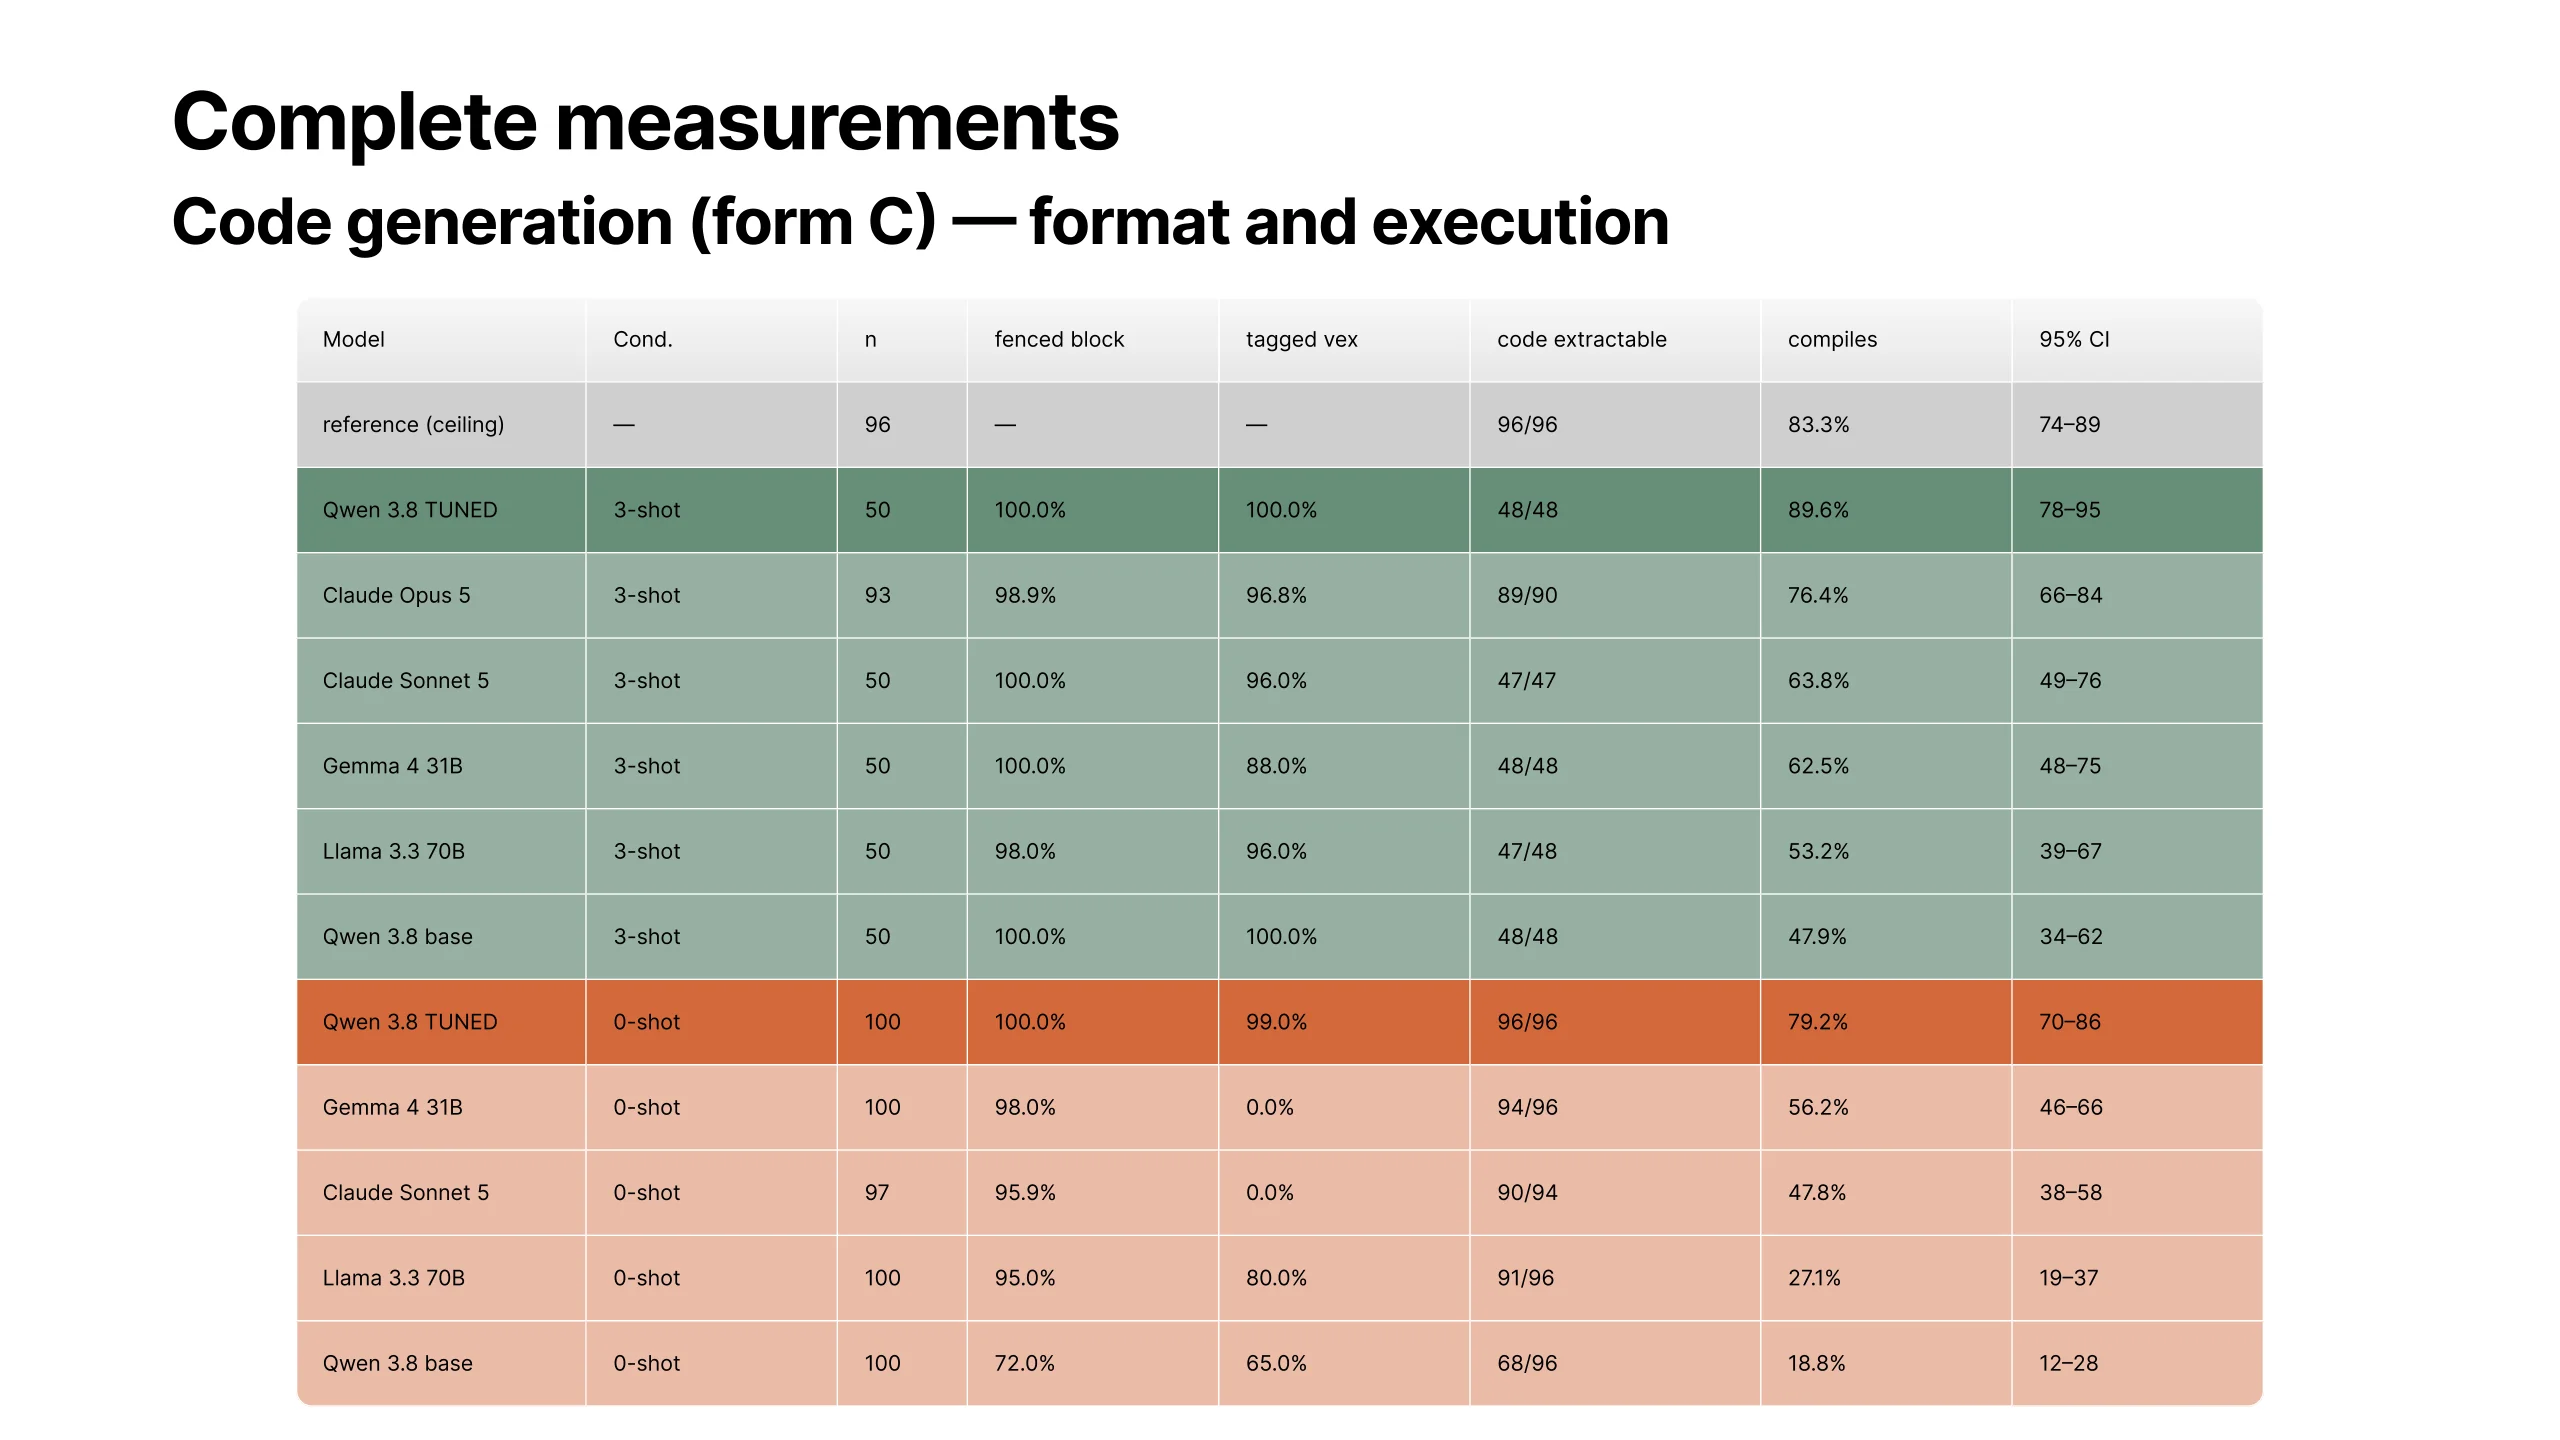
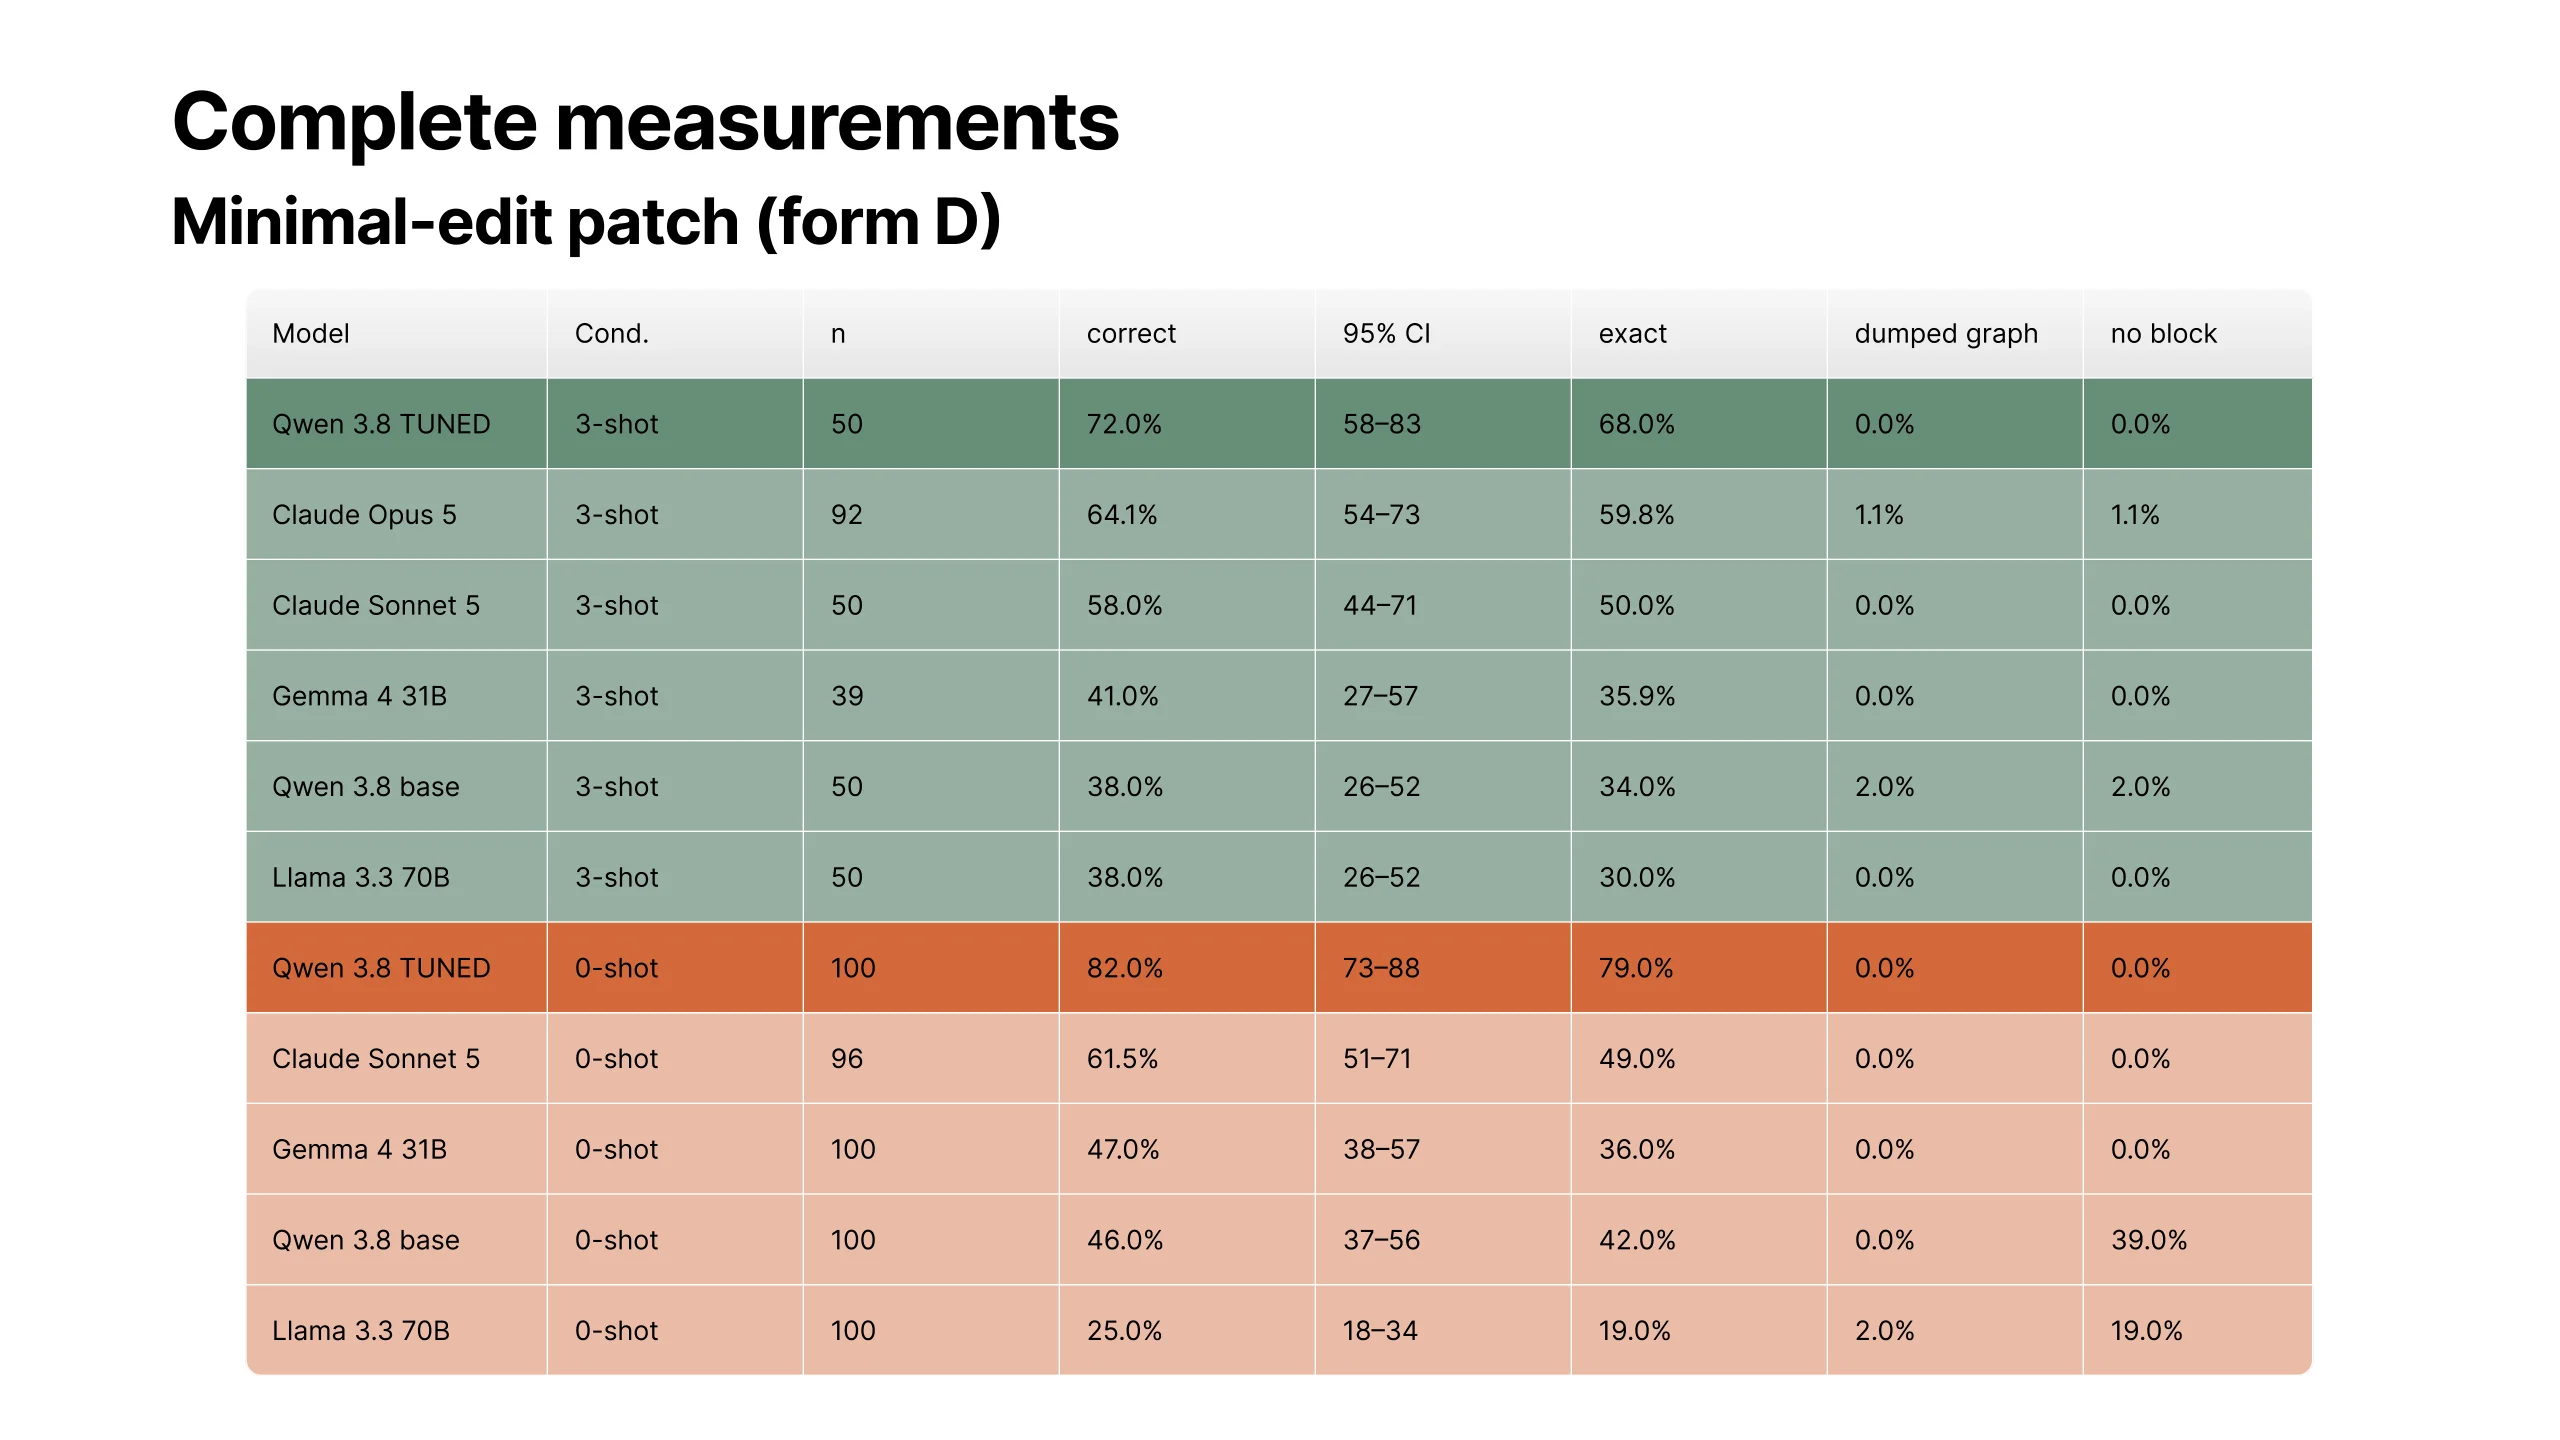
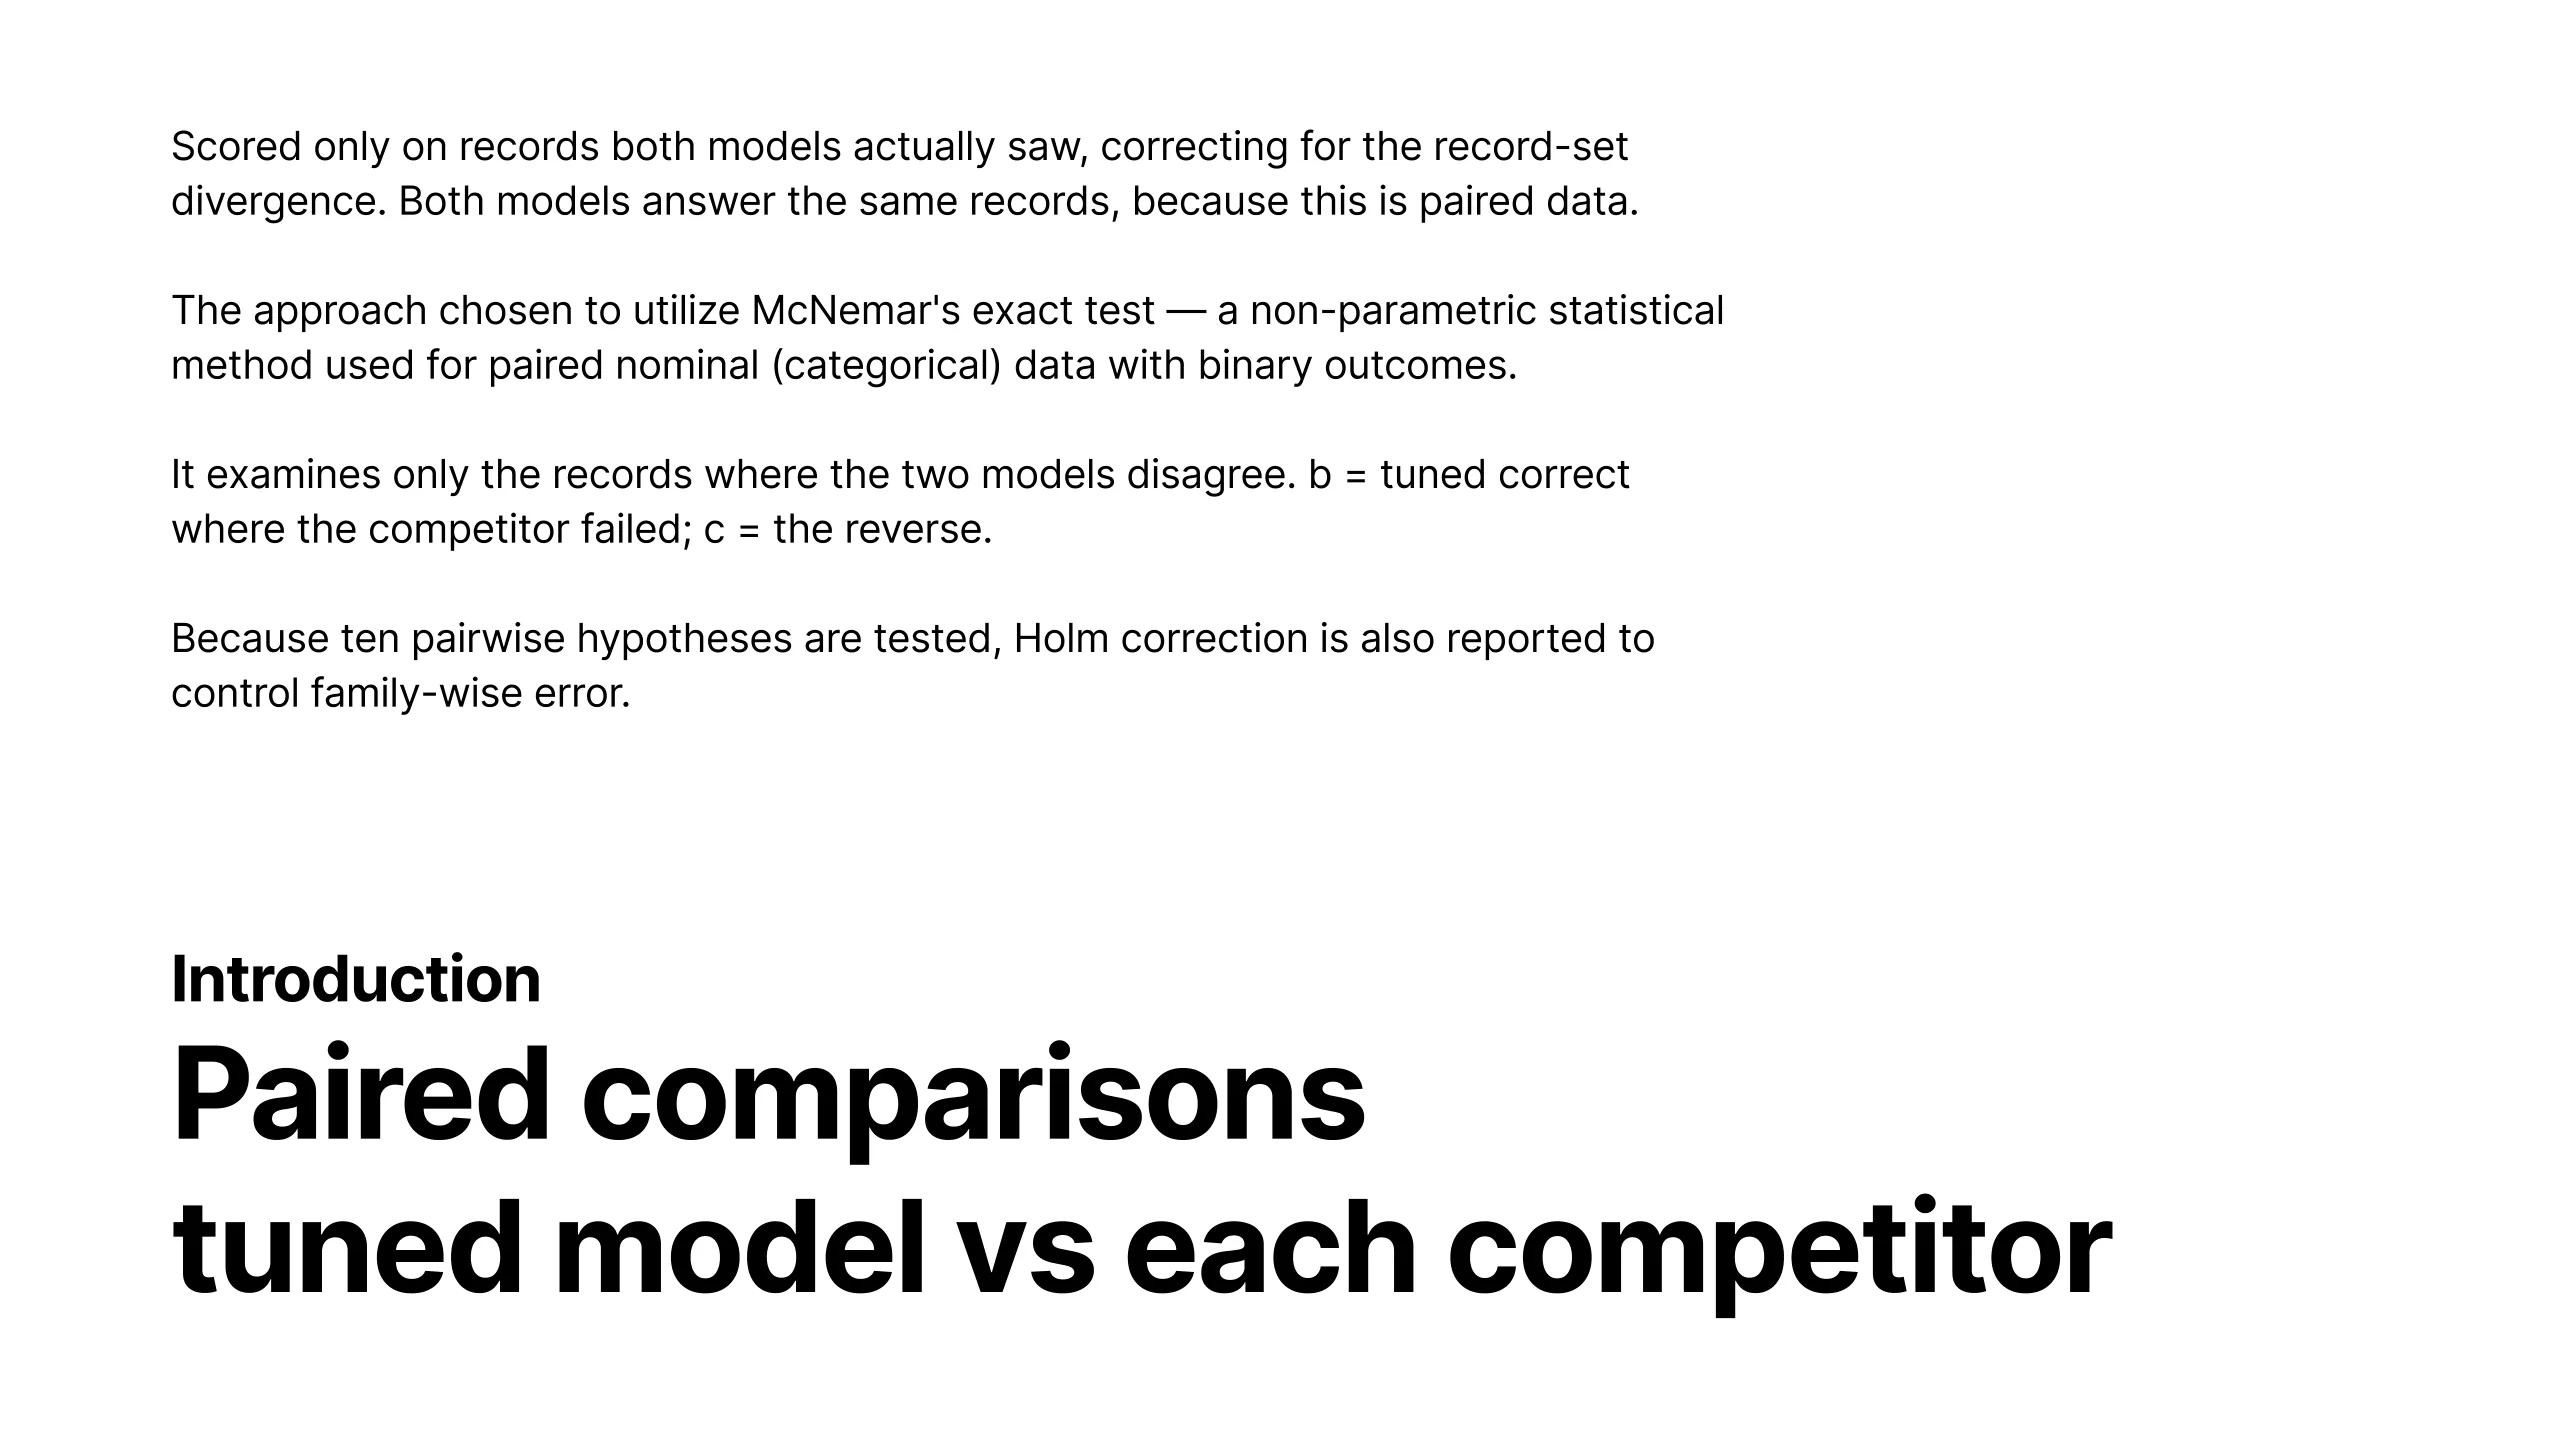
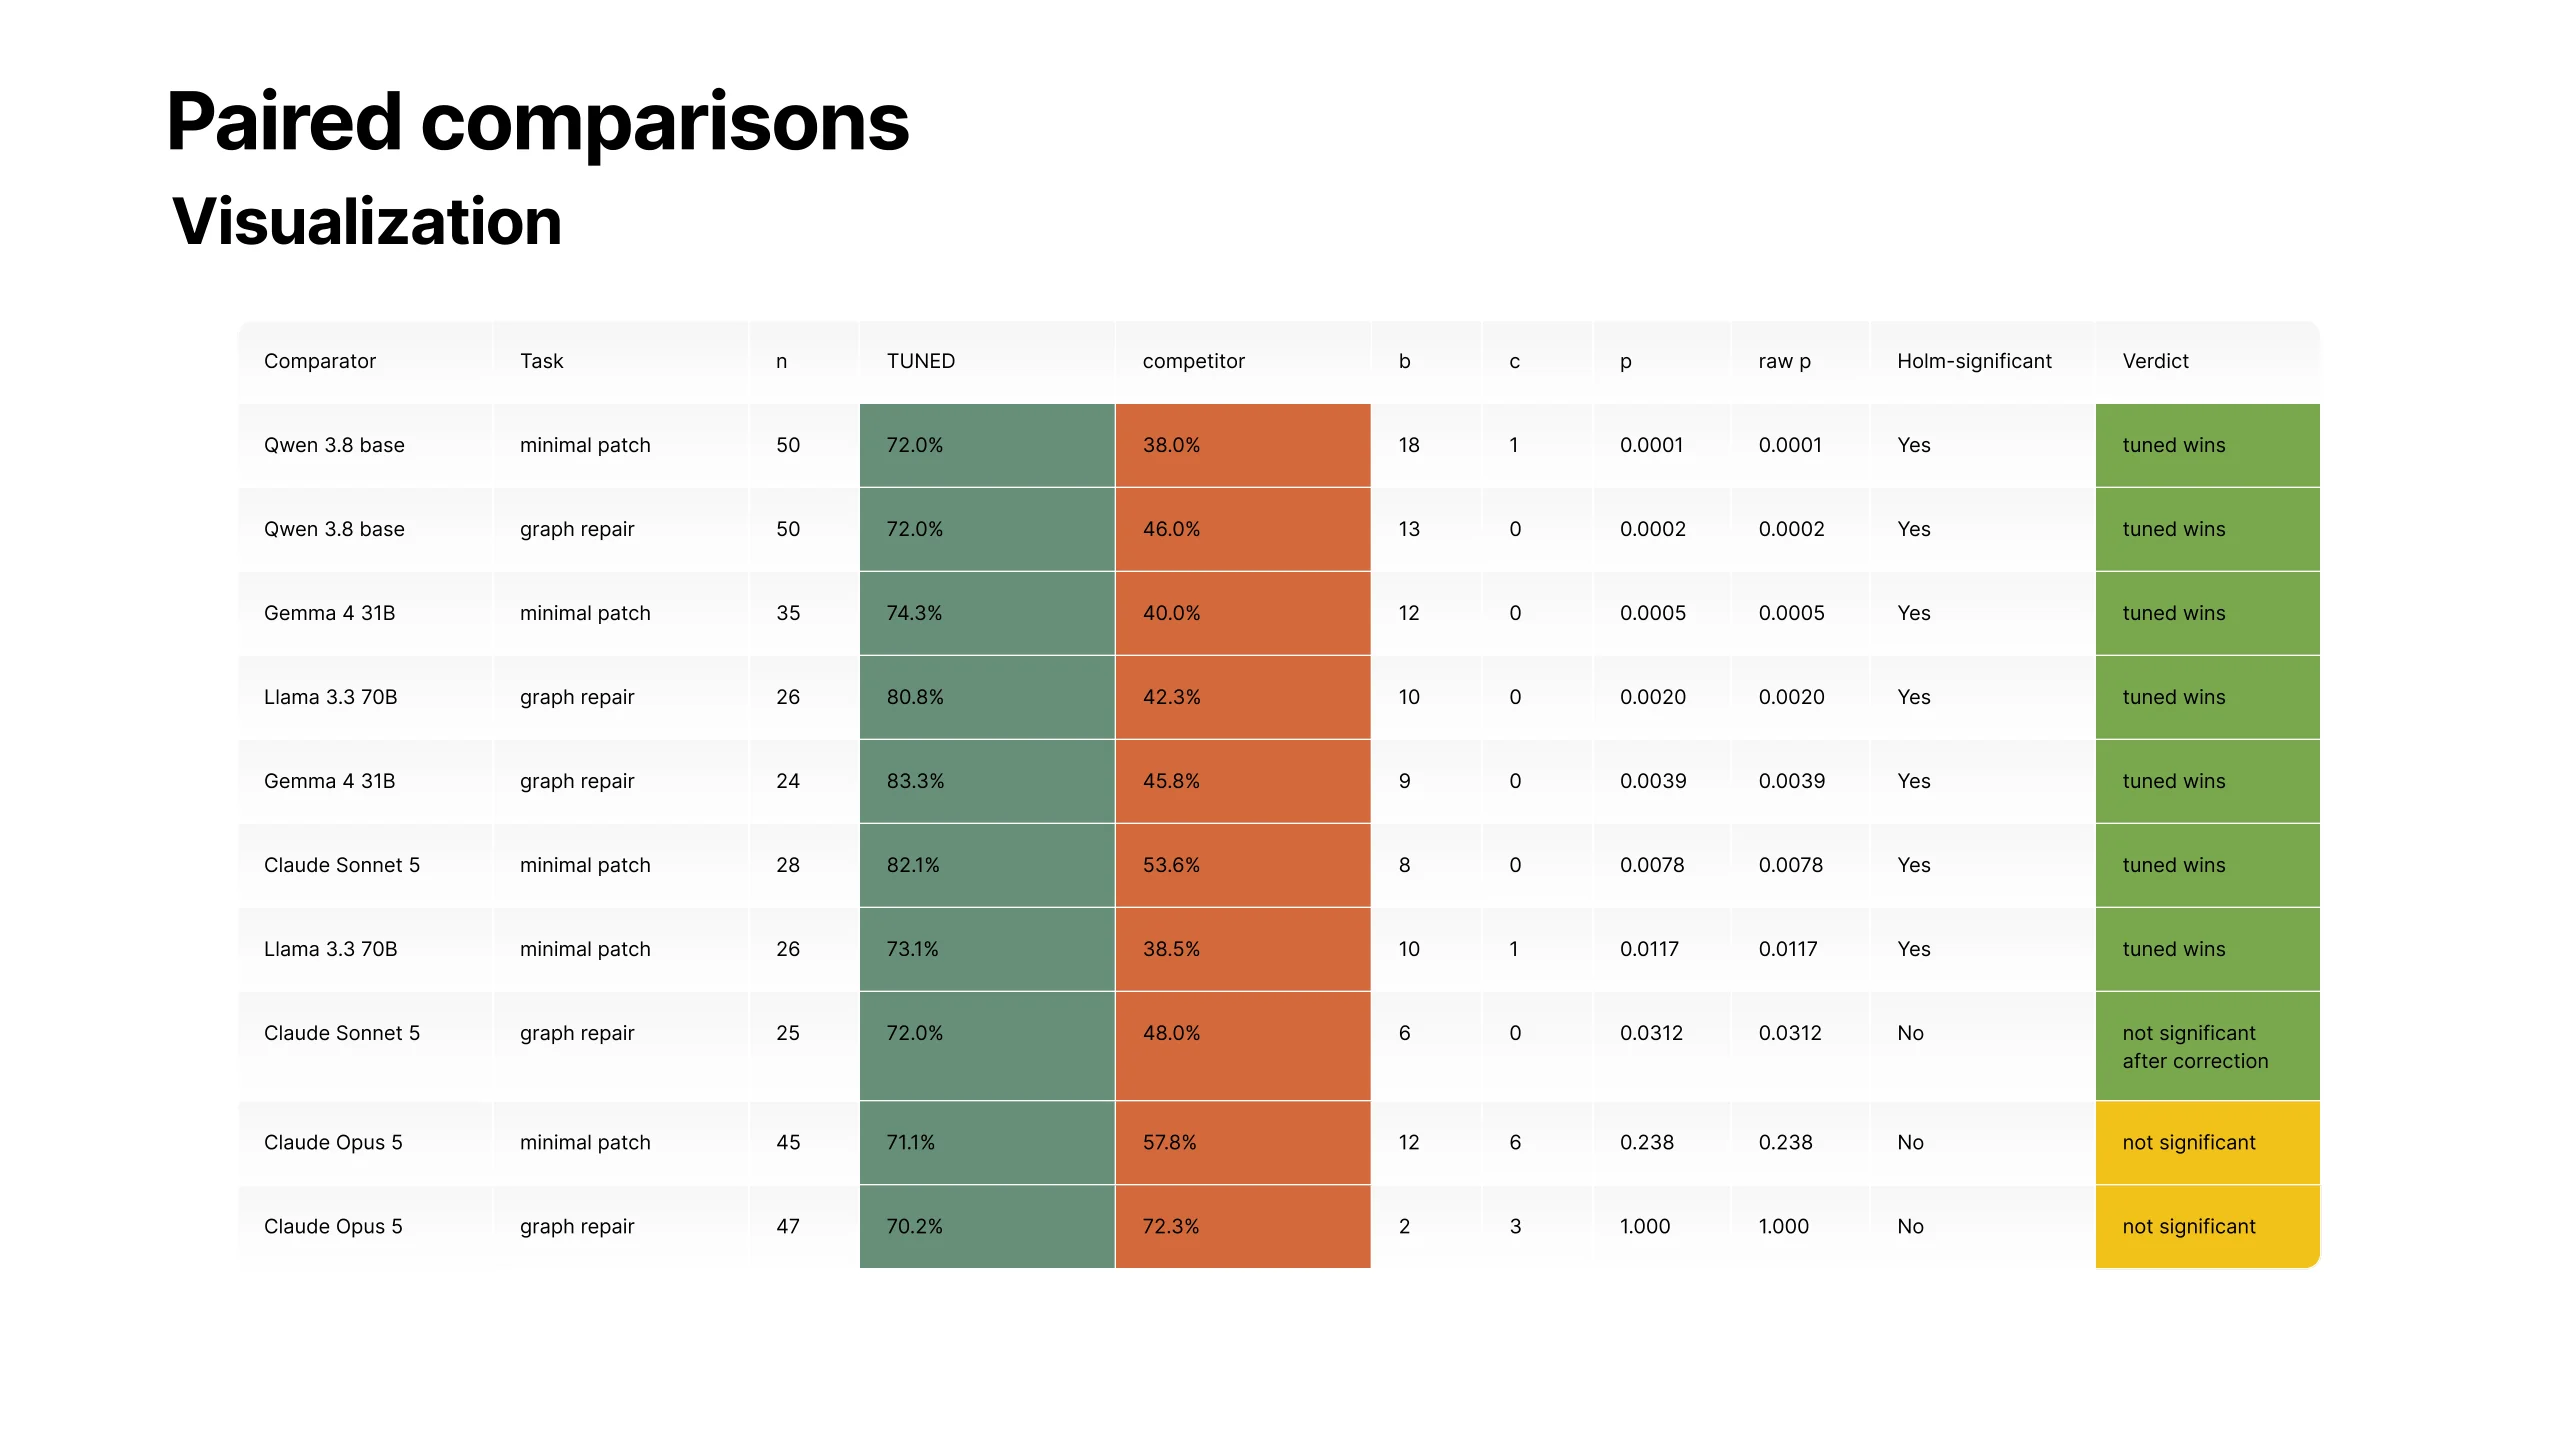
Six models were tested under identical conditions on 2,221 held-out examples that share no source threads with the training data. Every model was shown three worked examples first, a condition that helps the untuned models most. Every generated VEX snippet was compiled and run in a live Houdini 22 session, so either it works or it does not. Models were compared on the same examples using McNemar’s exact test, with Holm correction for testing ten comparisons at once.
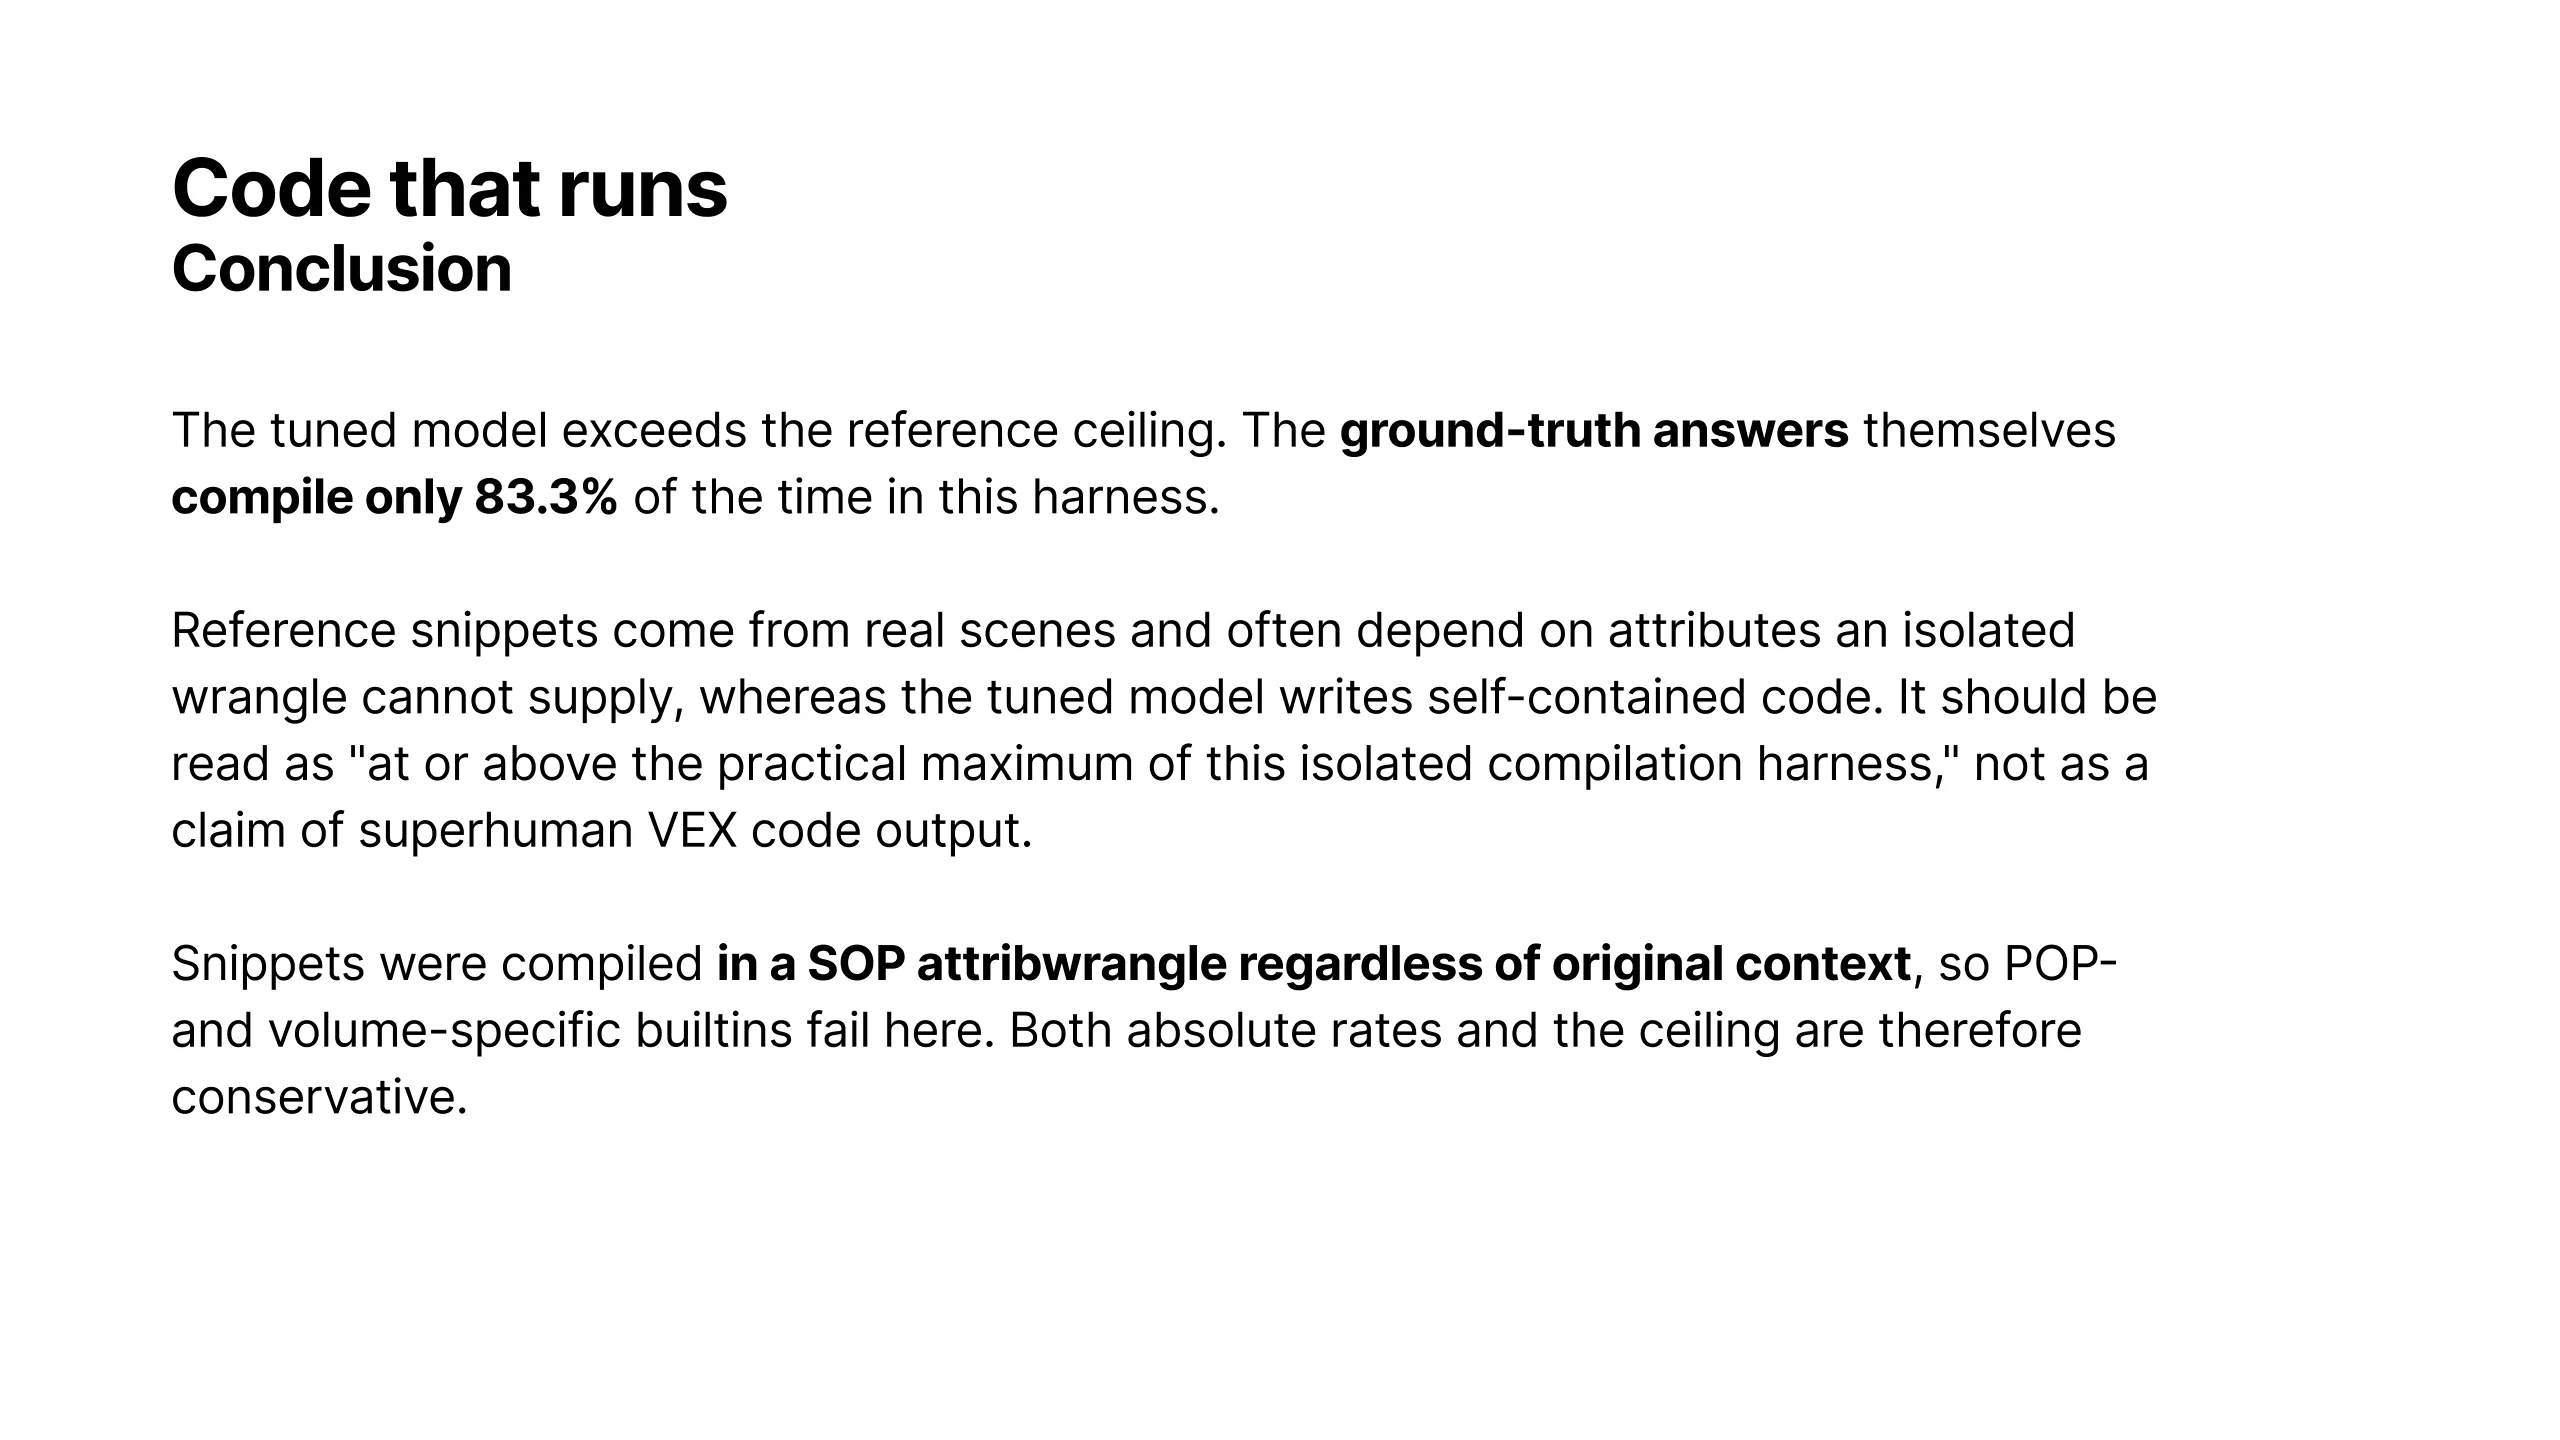
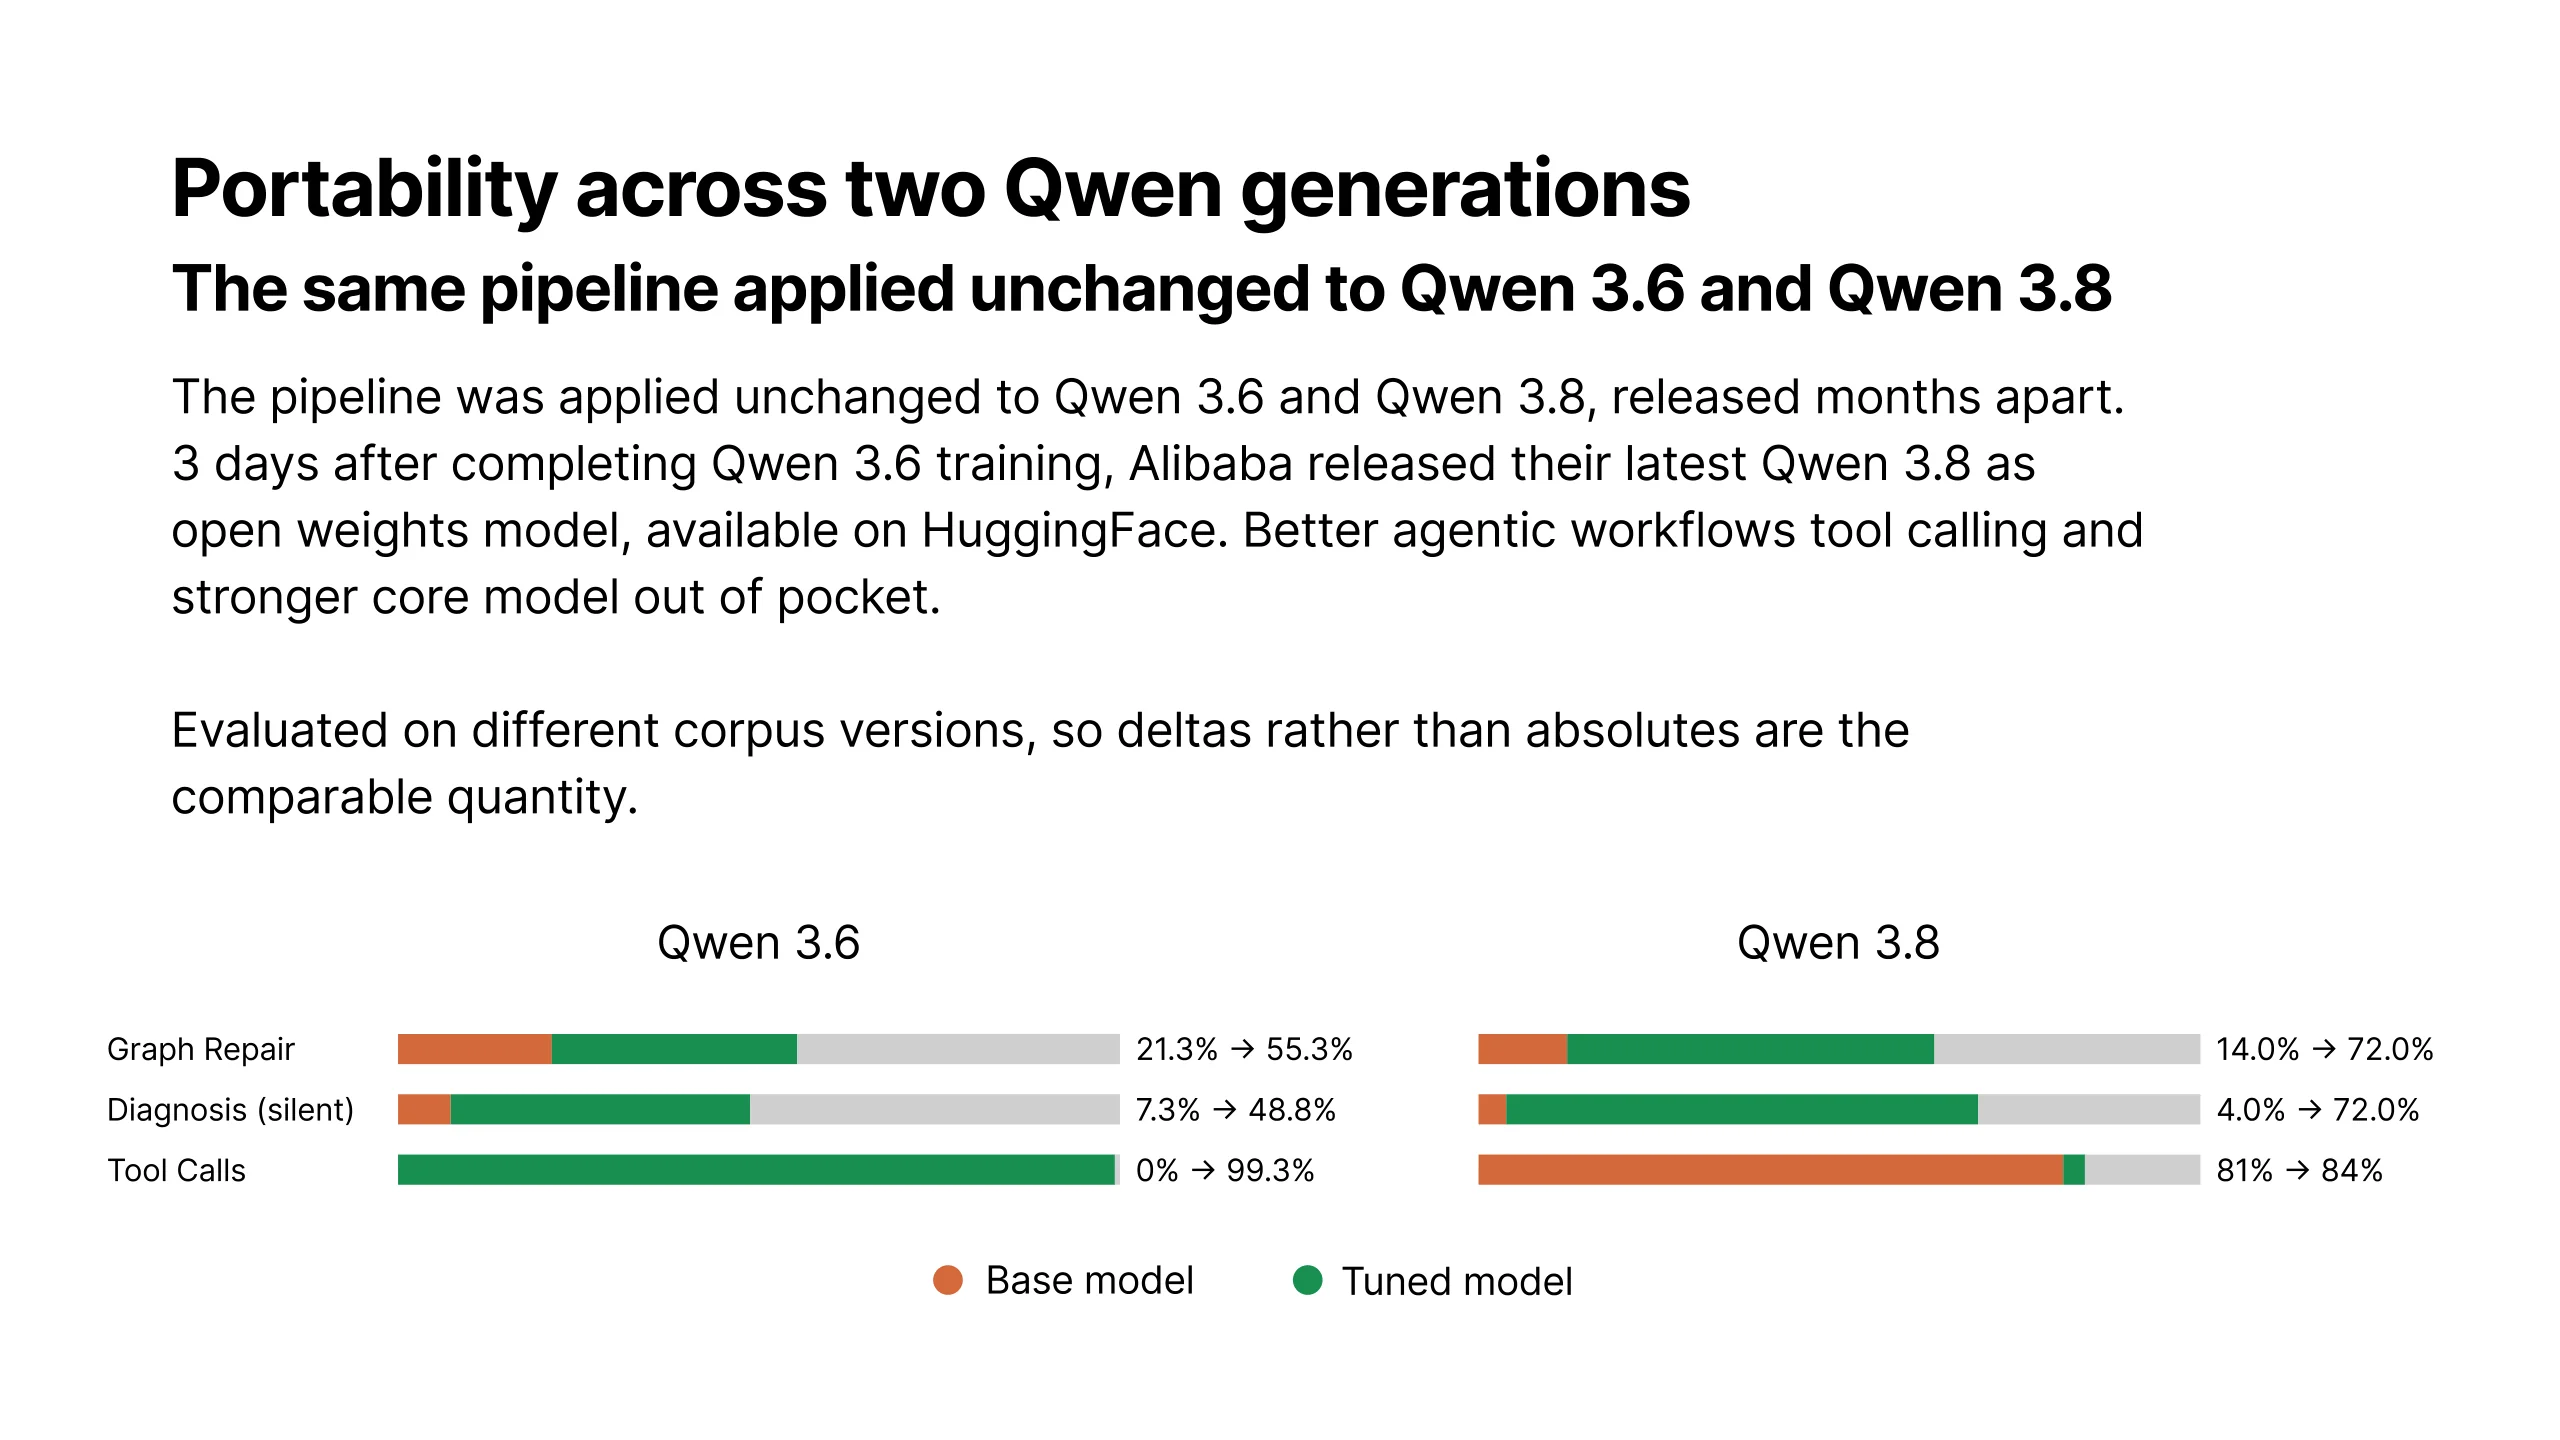
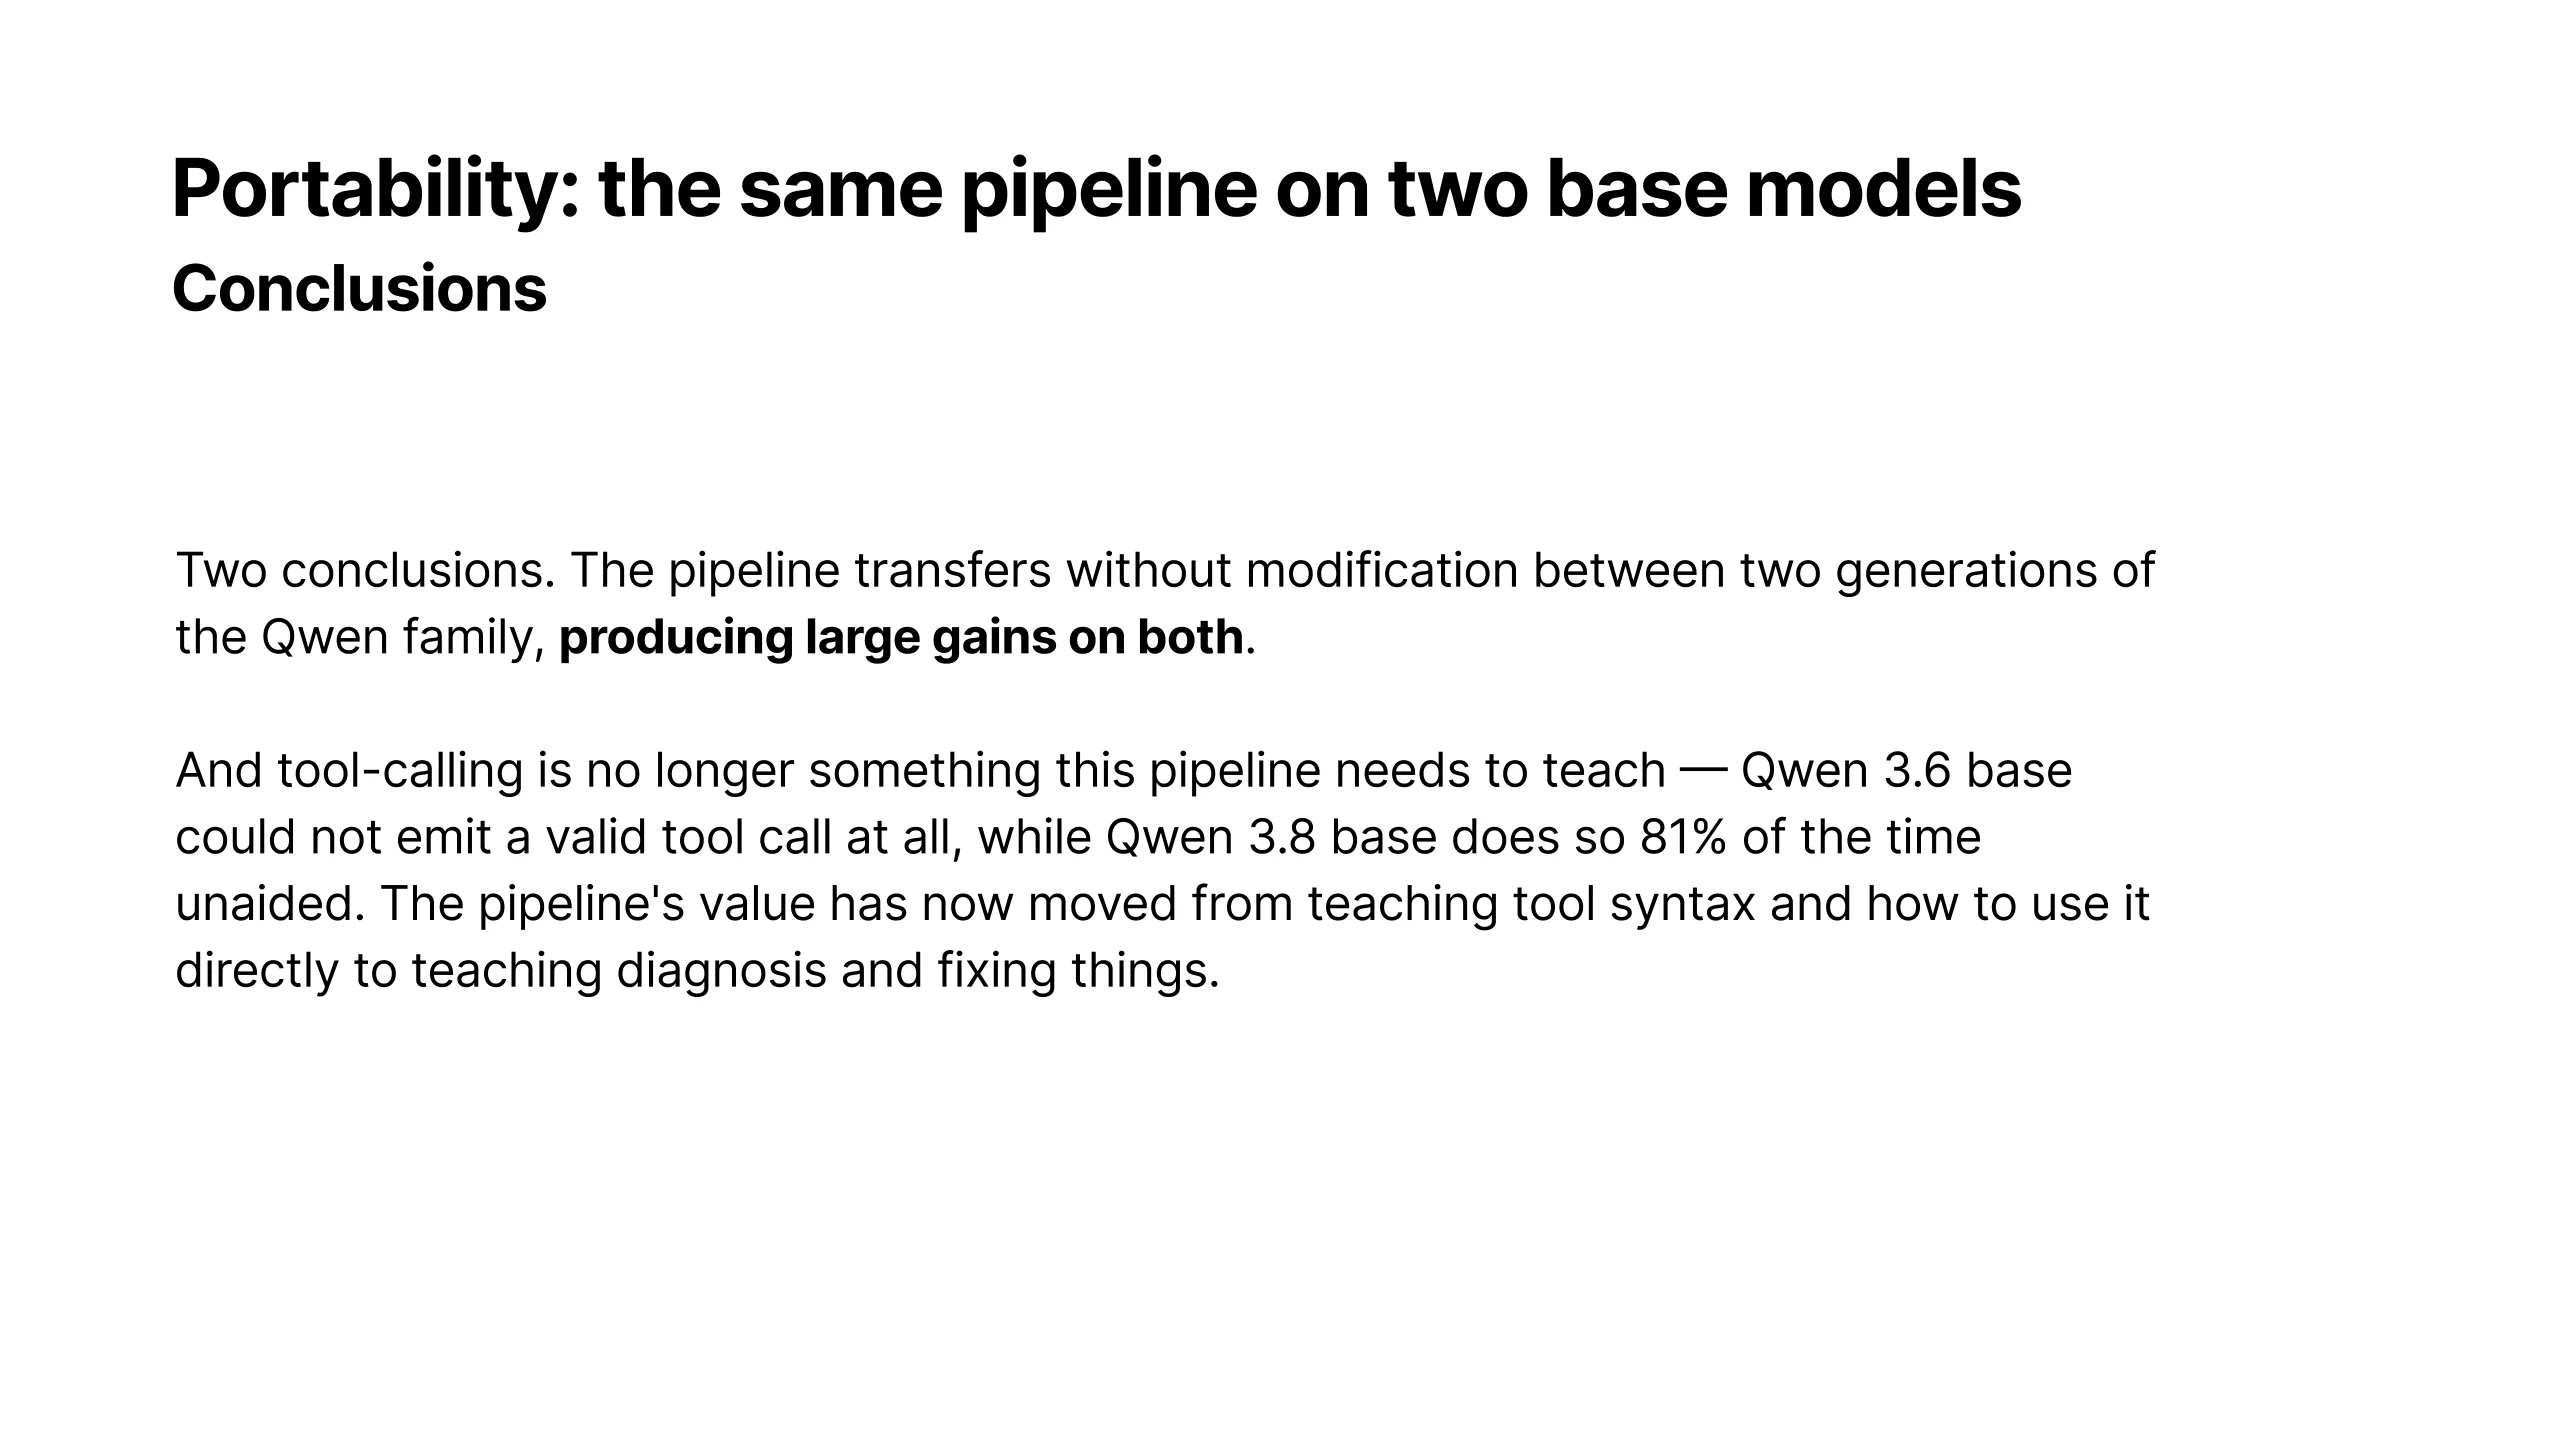
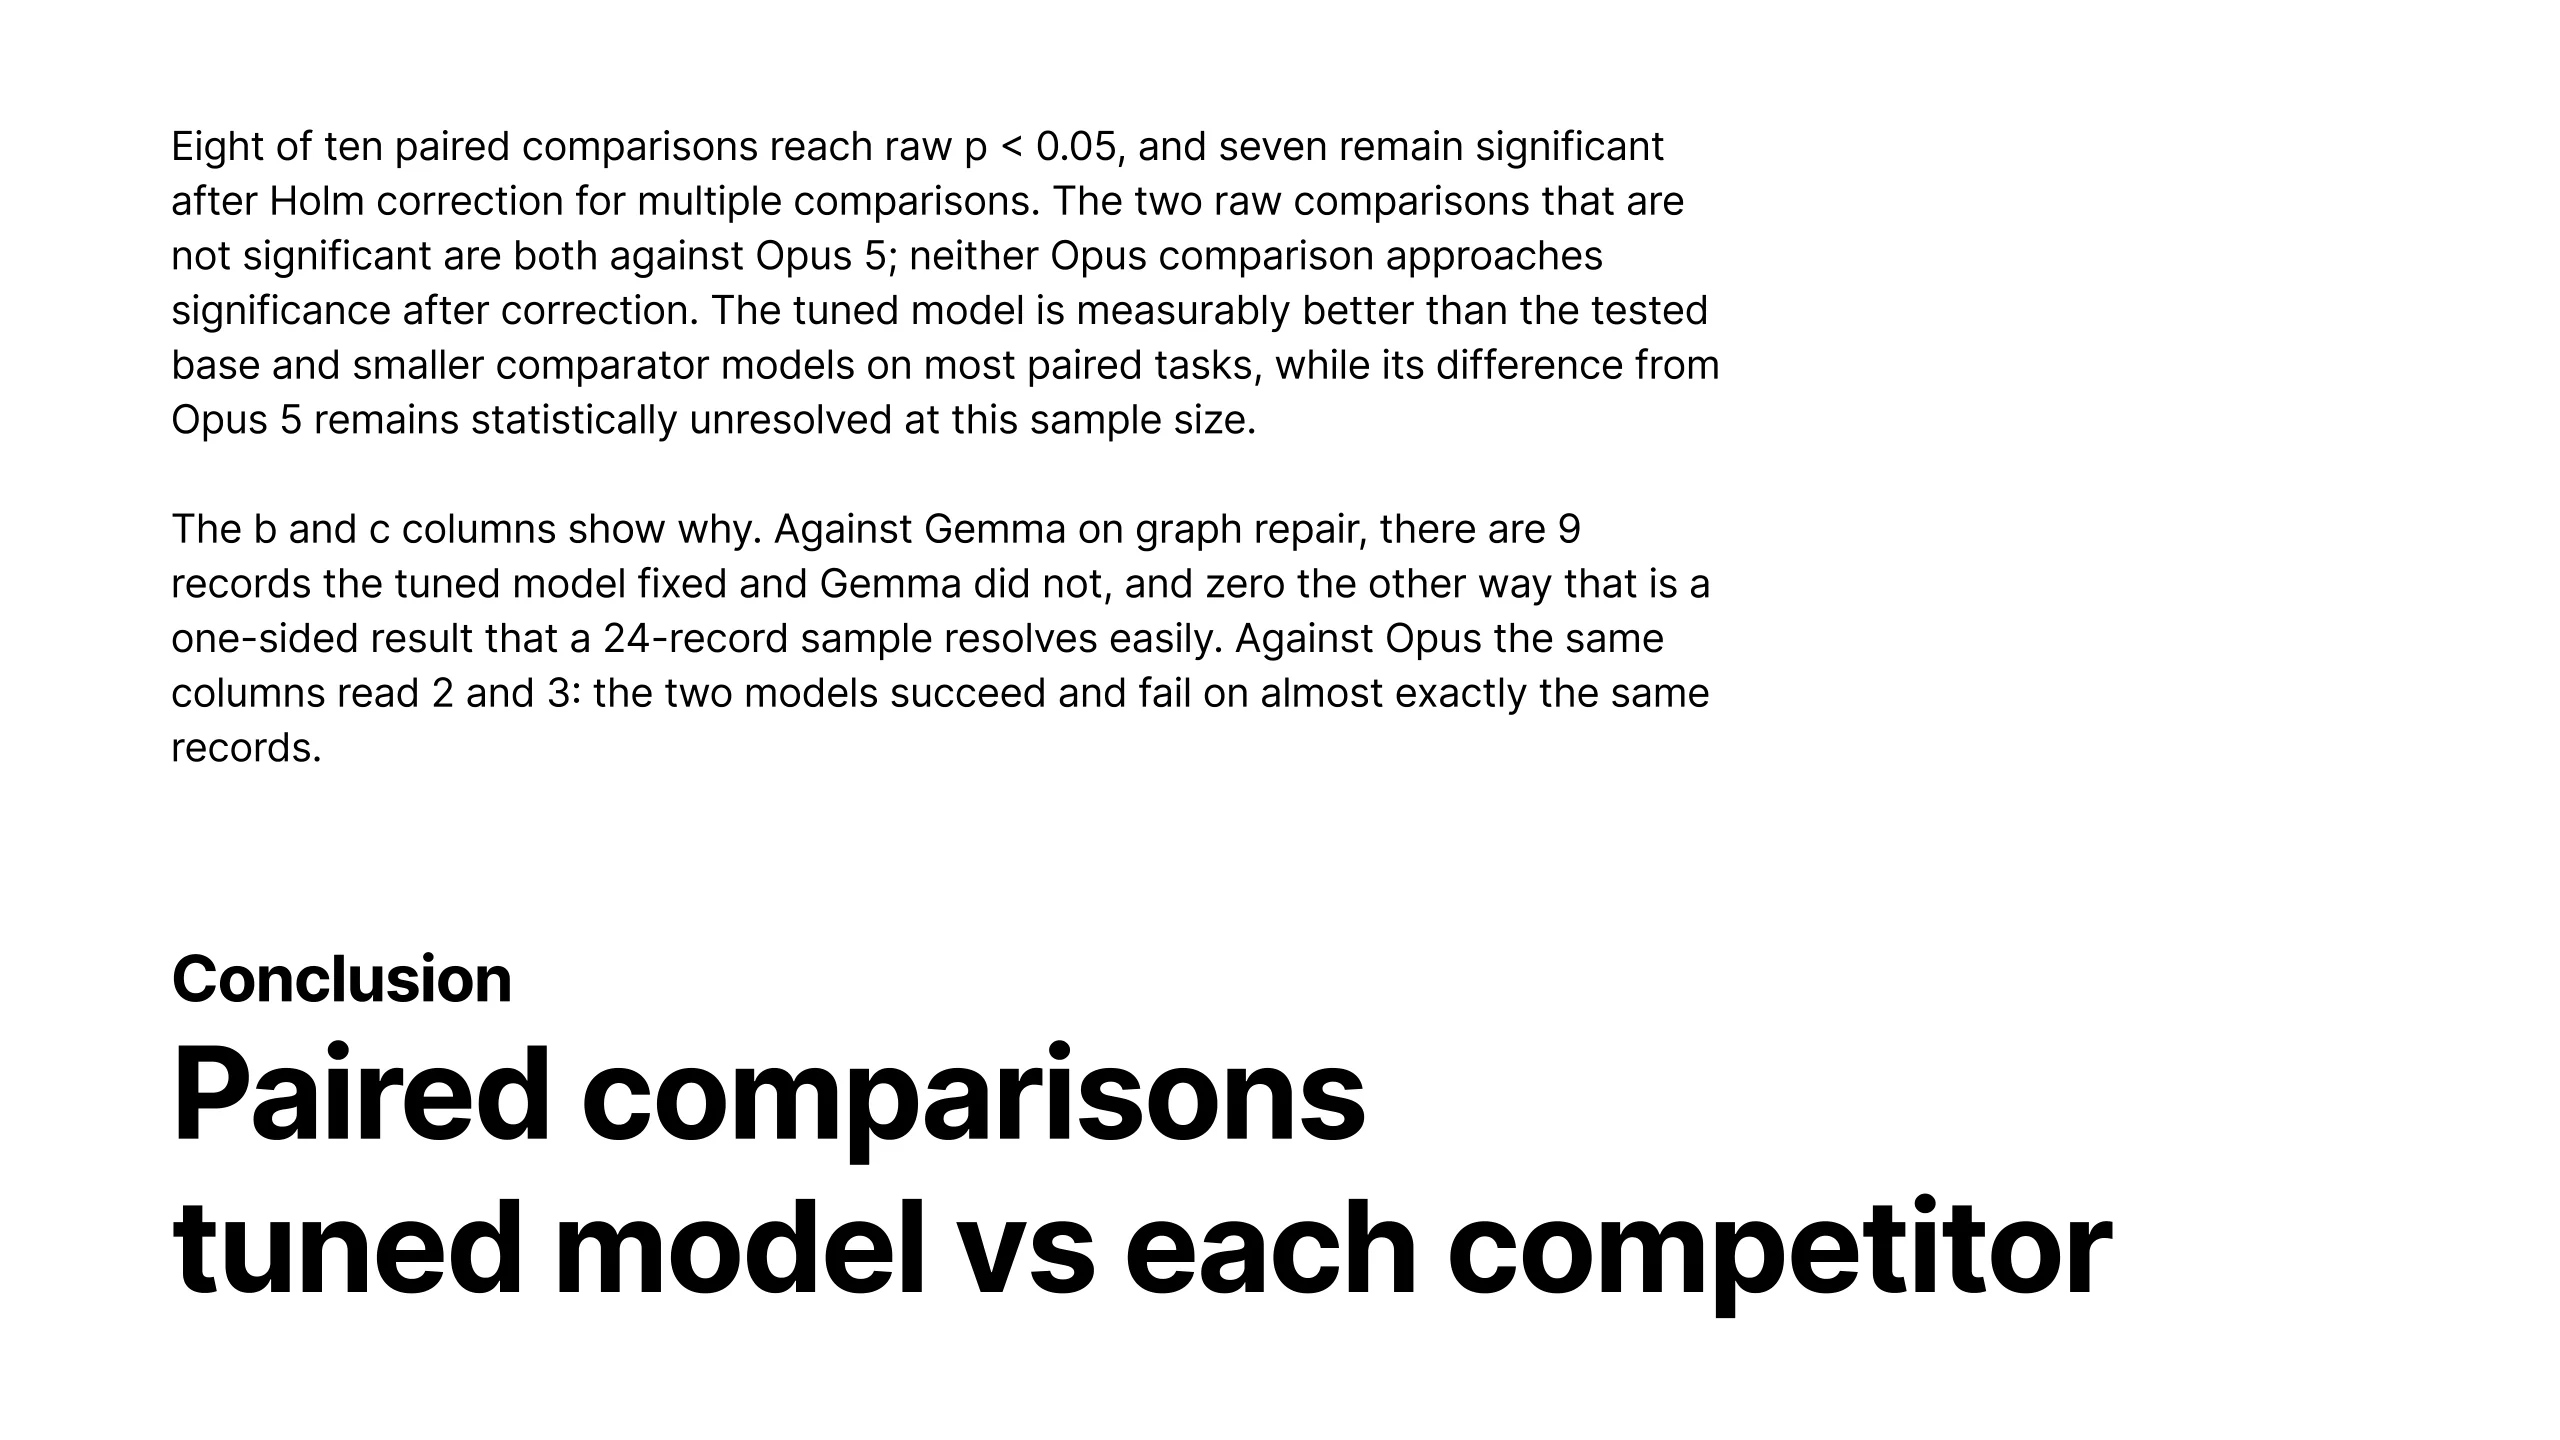
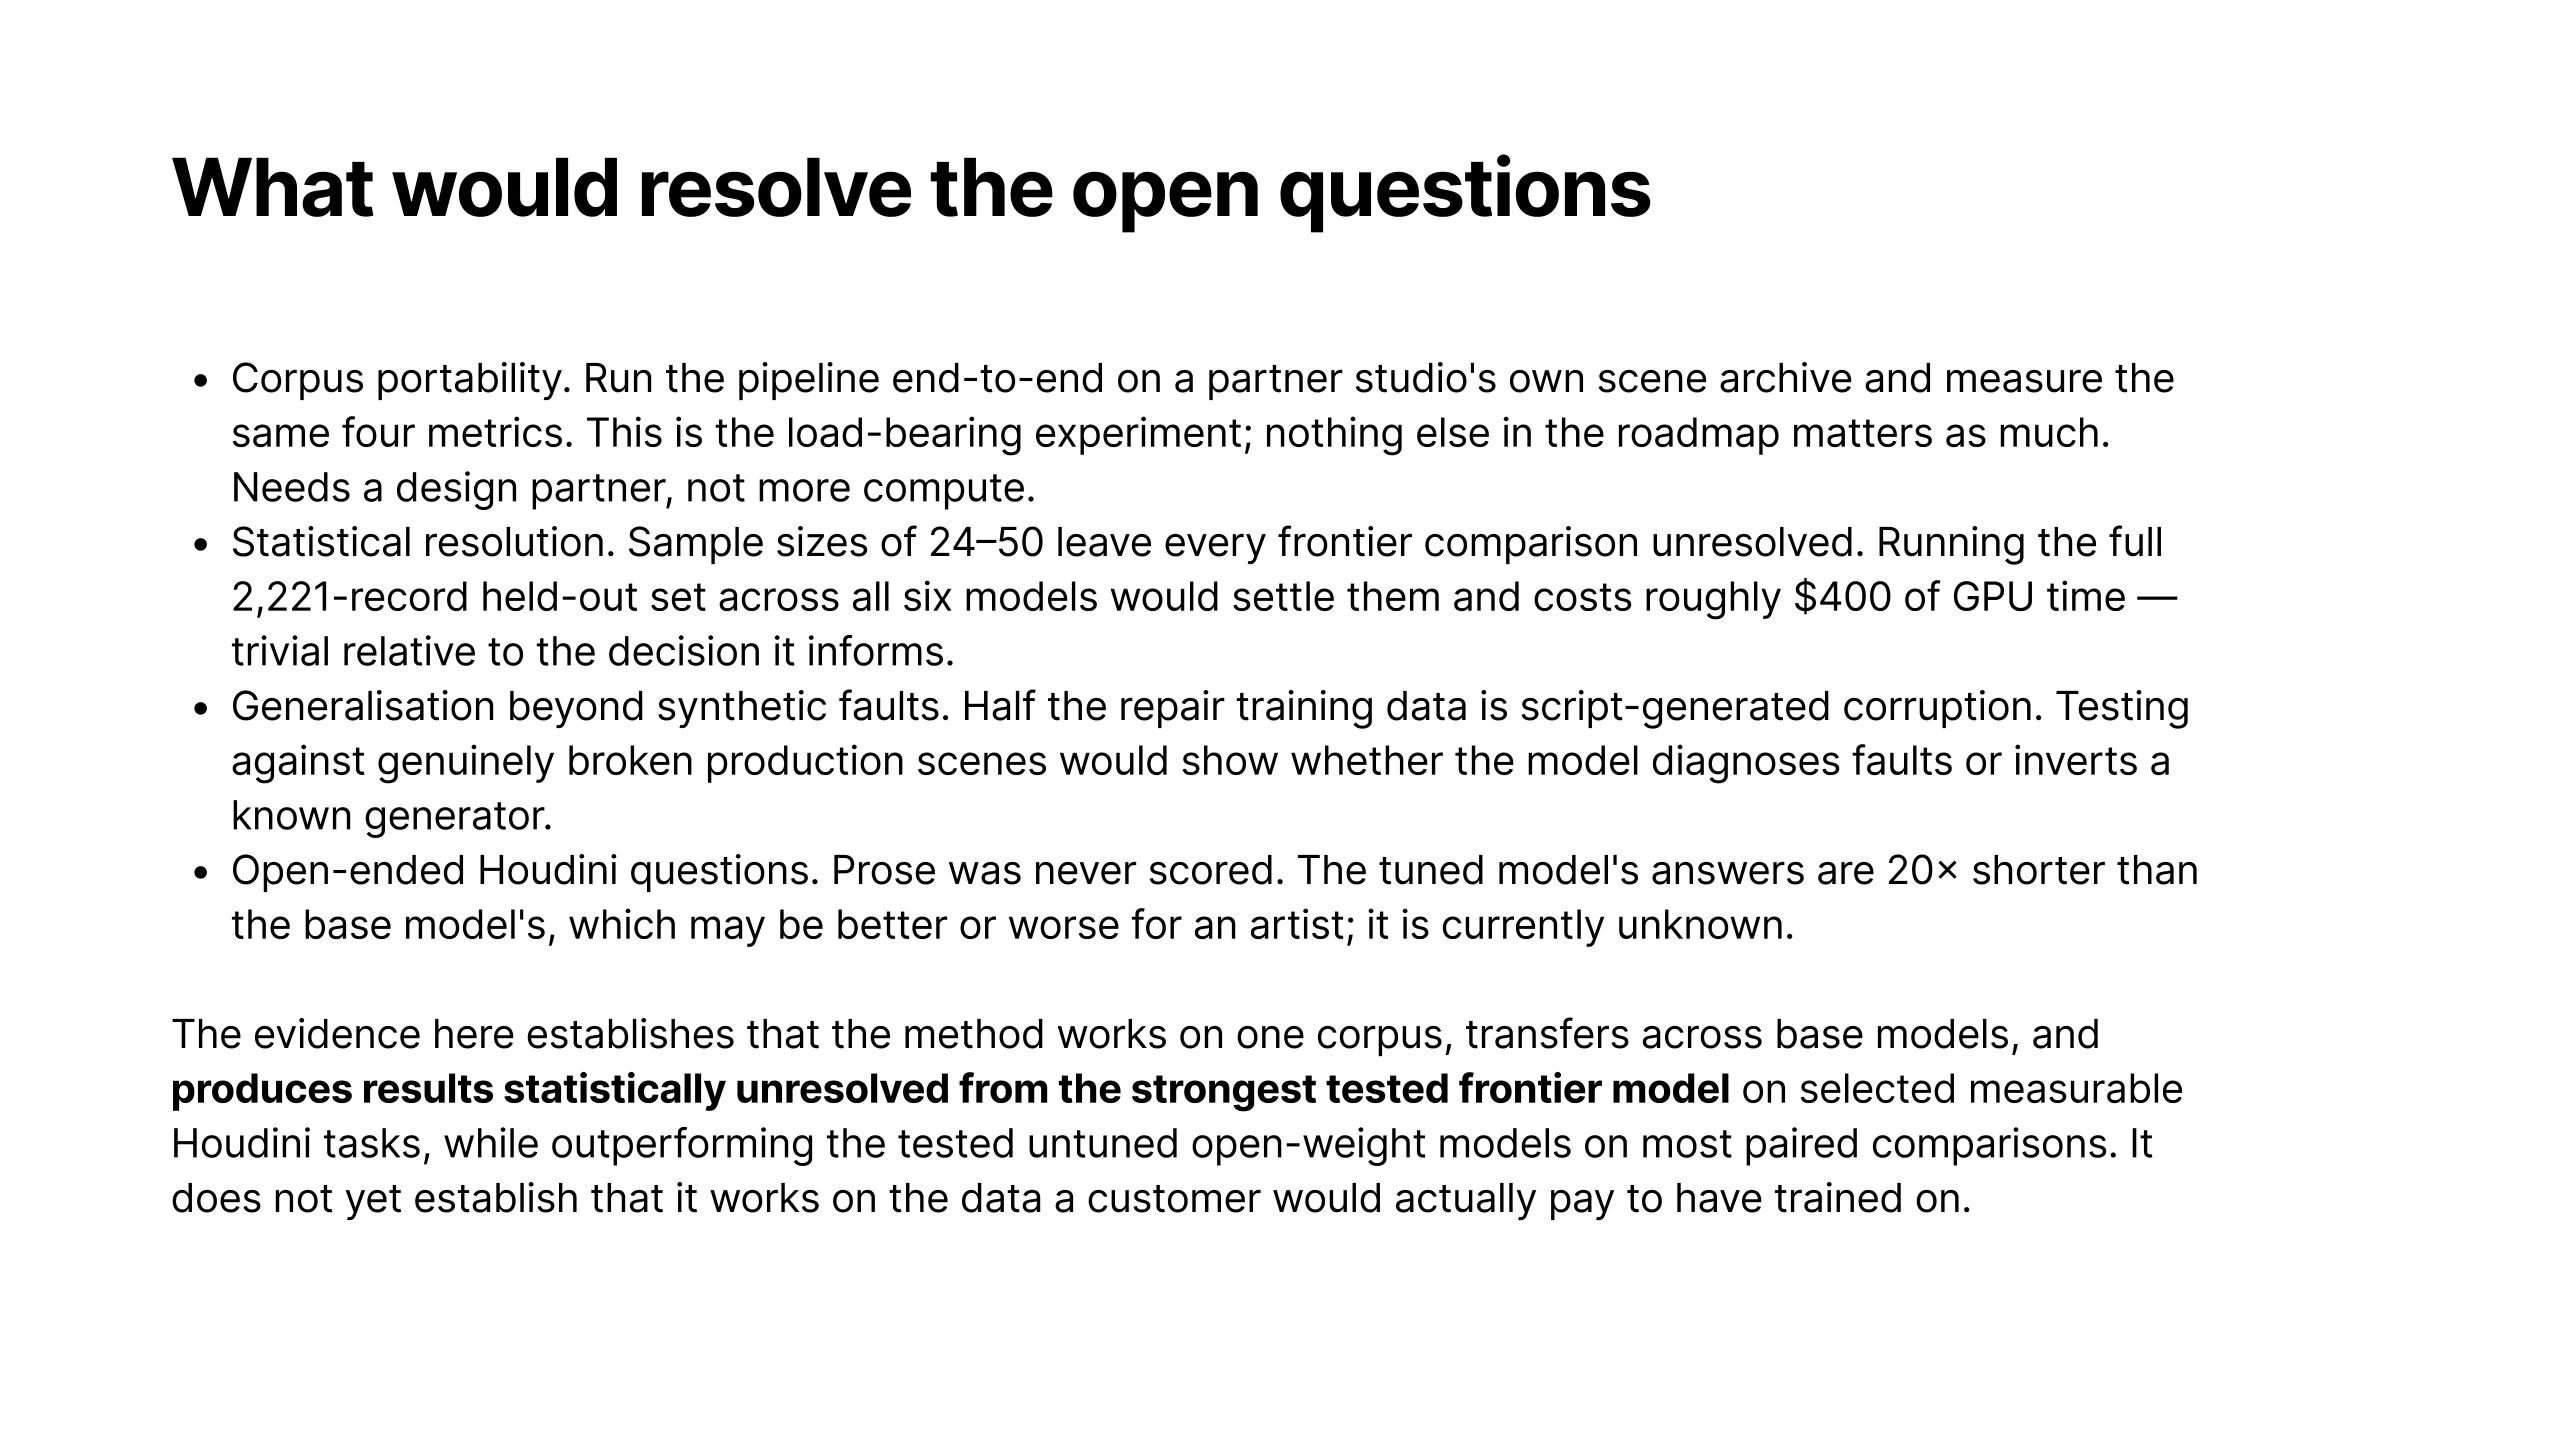
The tuned model compiled 89.6% of its VEX, more than any other model and above the 83.3% of the reference answers themselves. On graph repair (72.0%) and on diagnosing faults with no hints (54.5%), it showed no statistically detectable difference from Claude Opus 5 at this sample size, and it outperformed every untuned open-weight model tested. The same pipeline, applied unchanged to two generations of Qwen, lifted graph repair from 14% to 72%.
The question that matters most is still open: whether the same lift holds on a studio’s own scenes and conventions. That is the next experiment.
The product overview and the full technical report follow below, slide by slide. To see the report in full quality, you can download it by clicking here.